Developers · Stack
The AI-Native App Tech Stack (2026)
The modern AI-native stack layers models, orchestration, retrieval, a memory layer, vector storage and observability: here’s each component, how to choose it, and where memory fits in production agents.
2026 stack
Overview
What are the layers of an AI-native tech stack?
Seven layers, each with a distinct role in agentic apps, with memory carved out as its own row rather than folded into retrieval.
| Layer | Role | Common options | Choose when |
|---|---|---|---|
| Models | Reasoning, generation, tool use | GPT-4o, Claude, open weights (Llama, Qwen) | Latency, cost, compliance, tool-calling quality |
| Orchestration | Agent loops, tool routing, state | LangGraph, Letta, custom loops, n8n | Team skills, graph vs paging model, framework lock-in tolerance |
| Retrieval / RAG | Document-grounded answers | LlamaIndex, custom chunk+embed pipelines | Static knowledge bases, compliance docs, product catalogs |
| Memory layer | Cross-session facts, user prefs, agent learning | Engram, Mem0, Zep, Letta, LangMem | Stateful agents, personalization, multi-turn continuity |
| Vector store | Embedding storage and similarity search | Weaviate, Pinecone, pgvector, Qdrant | Scale, hybrid search needs, existing Postgres investment |
| Observability | Traces, evals, memory audit logs | LangSmith, Arize, custom OpenTelemetry | Production SLAs, LOCOMO/LongMemEval in CI |
| App / API | User-facing surface, auth, tenancy | Next.js, FastAPI, existing SaaS backend | user_id scoping, delete APIs, rate limits |
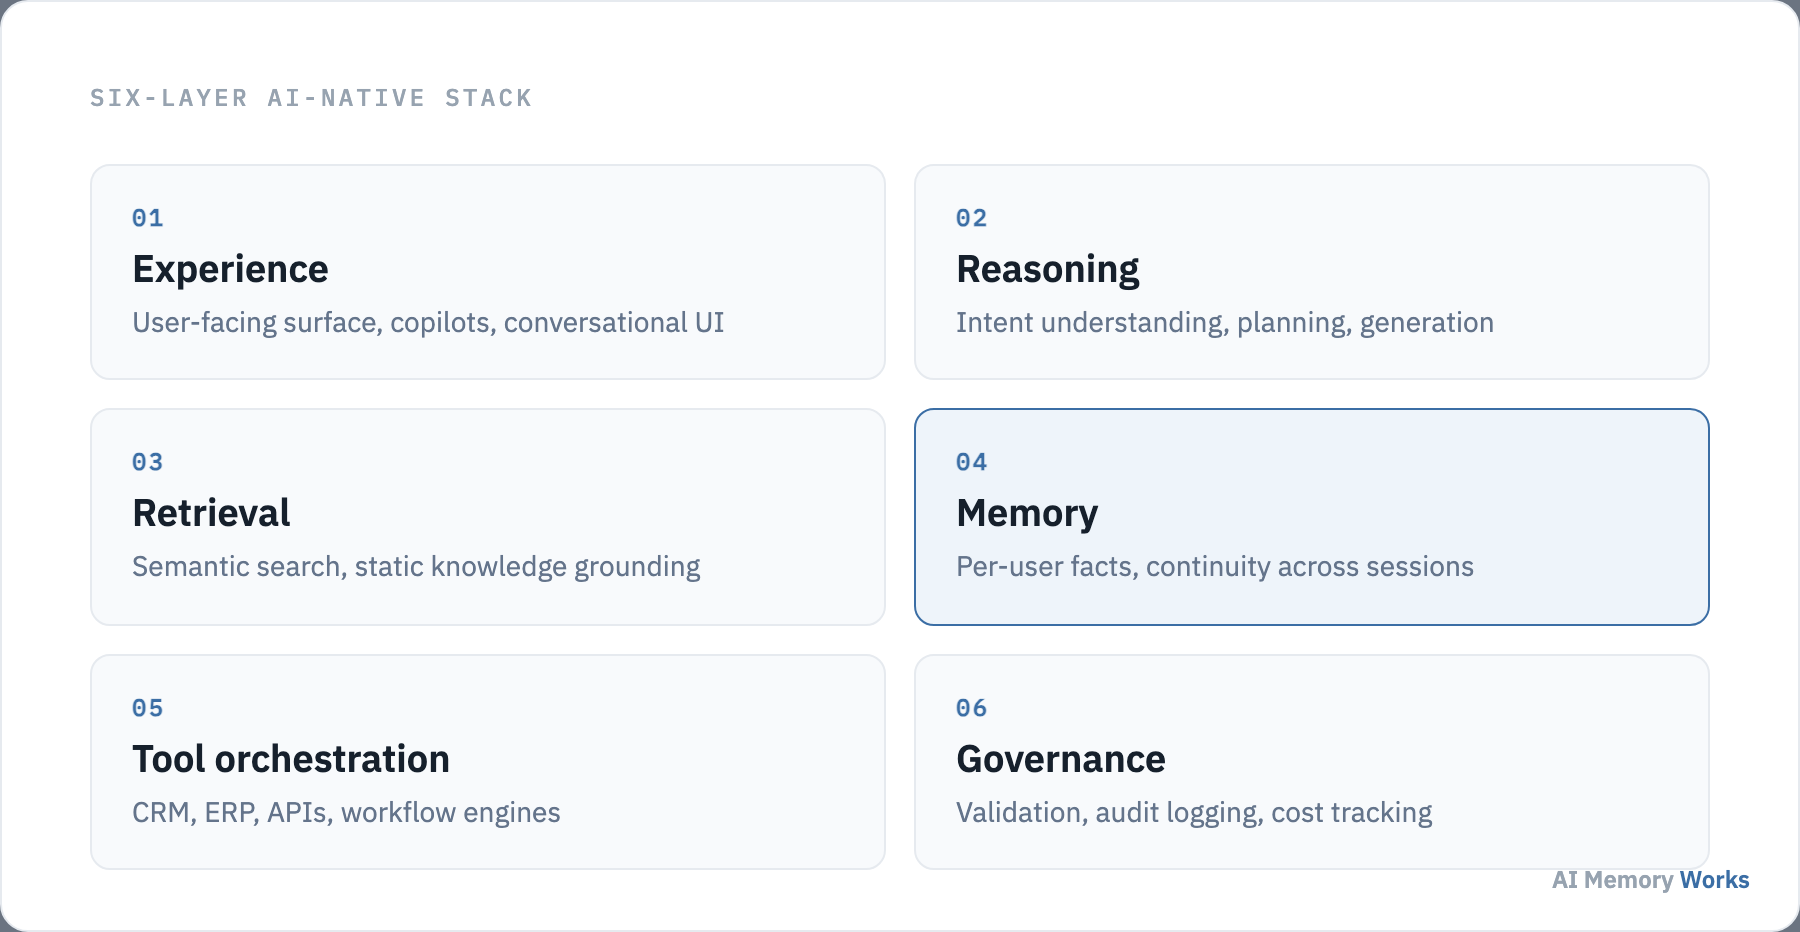
Two vendor engineering write-ups, published independently of each other and of this site, land on the same structural call. Impala Intech’s own breakdown of AI-native architecture names 7 components (Foundation Model, Orchestrator, Planner, Execution Engine, Memory Module, Knowledge Base, Controller); Techment’s separate 6-layer framework names Experience, Reasoning, Retrieval, Memory, Tool Orchestration and Governance layers. Neither team wrote from the other’s work, and both still isolated memory as its own layer rather than treating it as a sub-feature of retrieval or of the reasoning model. That kind of convergence, arrived at twice from two different starting points, is a stronger signal than either framework would be alone.
Techment’s reference architecture also fixes memory’s position in the request flow rather than just naming it as a layer: a request moves through reasoning, then retrieval, then memory, then tool execution, then governance, before a response is generated. That ordering matters for the table above: memory is read and written after retrieval has already assembled document context, not before, so the memory layer’s job is to add what retrieval structurally cannot, namely facts about this specific user and this specific agent’s own prior decisions, rather than duplicate what a knowledge base already grounds.
Why a separate layer
Why does memory need its own layer at all?
Request/response architecture is built to return the same output for the same input; a memory layer is what breaks that assumption on purpose.
Traditional software architecture assumes a request enters, passes through deterministic business logic, and produces a repeatable result. An AI-native application inverts that: the reasoning and retrieval layers can be built perfectly and an agent will still forget a returning user between sessions, because nothing in a stateless request pipeline was ever built to carry a fact forward on its own. That gap is architectural, not a model-quality problem, which is why it needs its own dedicated layer rather than a bigger prompt or a longer context window.
Once memory is treated as infrastructure rather than a prompt trick, it has to answer 3 questions a request/response layer never had to: what gets written, what gets retrieved for this specific turn, and what gets forgotten or overwritten when a fact changes. Every row in the stack table above exists to answer one of those 3 questions for one part of the pipeline.
This is also why bolting a memory feature onto an existing SaaS backend tends to feel awkward rather than straightforward, the same mismatch IT Idol Technologies’ own engineering research describes for AI-native systems generally: the original request/response architecture was never built with a per-user, cross-session dependency in mind, so the fix is a new layer with its own lifecycle, not a wider column on an existing table.
Prime layer
Where does the memory layer sit in the stack?
Sits between agent orchestration and raw data infrastructure: extraction, retrieval orchestration, update policies and multi-tenant scoping.
Without a memory layer, agents reset every session. With one, they remember user preferences, prior decisions and conversation facts. Mem0 reports LOCOMO J 66.9 with median search 0.148 s and p95 total 1.44 s vs 17.1 s full-context (Chhikara et al., 2025). Zep scores LongMemEval 71.2% gpt-4o (+18.5% vs baseline) on temporal reasoning (Rasmussen et al., 2025).
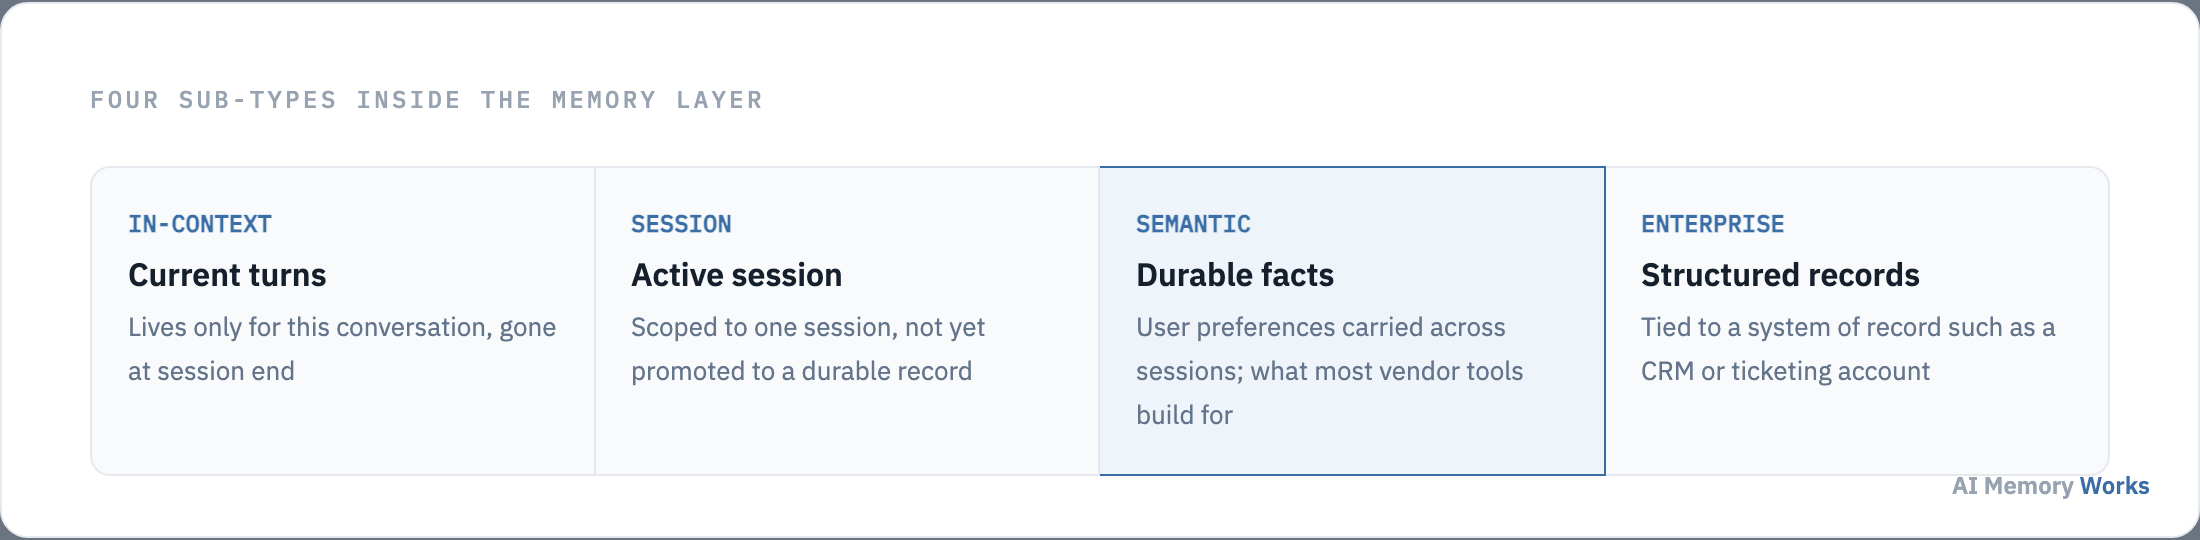
Techment’s own architecture research splits what “the memory layer” holds into 4 distinct sub-types rather than treating it as one undifferentiated store: in-context memory (the current conversation’s own turns, gone once the session ends), session memory (facts scoped to one active session but not yet promoted to a durable record), semantic memory (durable user facts and preferences carried across sessions), and structured enterprise memory (records tied to a business system of record, such as a CRM or ticketing account). Most vendor tools in the table below implement semantic memory as their core product; session and in-context memory are usually handled by the orchestration layer directly, and structured enterprise memory is typically bridged in through a tool call rather than stored inside the memory layer itself.
Engram is the Weaviate-native memory layer: dynamic extraction, hybrid search and scoped collections (GA June 2026). If your stack already uses Weaviate, Engram adds agent semantics without a separate memory vendor. Public LOCOMO/LongMemEval numbers for Engram are not yet published.
- Engram: Weaviate-native; best when vector infra is already Weaviate
- Mem0: framework-agnostic managed API; fastest POC path; LOCOMO J 66.9
- Zep: temporal knowledge graph; LongMemEval +18.5%; DMR 94.8%
- Letta: virtual-context paging; MemGPT DMR 93.4% (Packer et al., 2023)
- LangMem: LangGraph-integrated; LOCOMO J 58.1
→ Memory layer deep dive · Engram explained · Best AI memory tools
Storage
How is the memory layer different from the vector store?
Stores embeddings; distinct from the memory layer that decides what to remember and how to retrieve it.
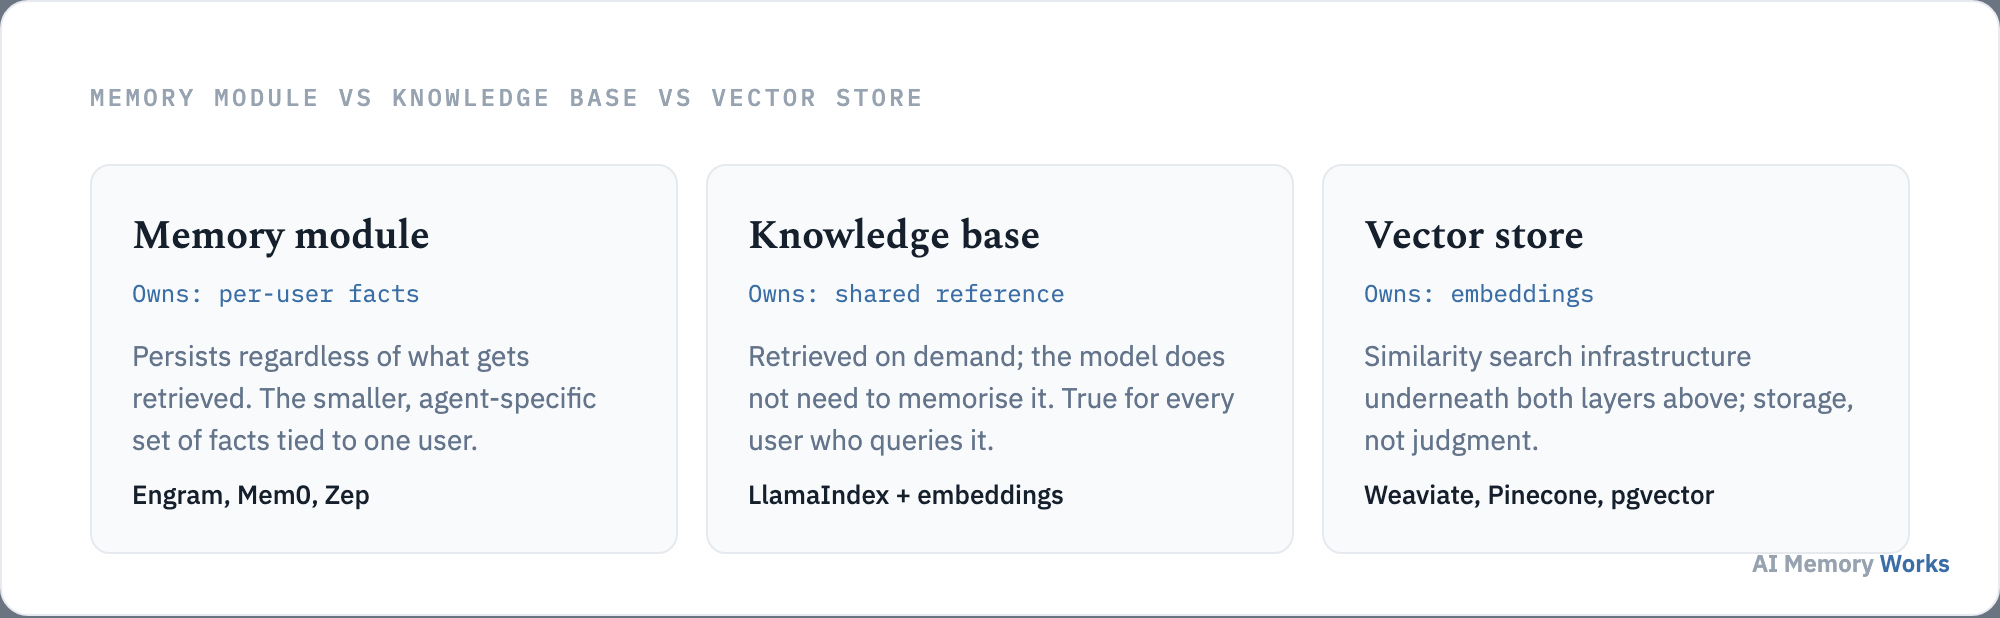
Weaviate, Pinecone, pgvector and Qdrant handle similarity search at scale. The memory layer sits above: extracting facts from conversations, deduplicating, applying forget policies and formatting retrieved context for the LLM. Impala Intech’s own architecture write-up draws the same line from a different angle, separating a “Memory Module” from a “Knowledge Base” on the grounds that “the model does not need to memorise everything”: the knowledge base holds reference material retrieved on demand, while the memory module holds the smaller, agent-specific set of facts that must persist regardless of what gets retrieved. Engram illustrates the split in practice: Weaviate is storage, Engram is the agent-oriented layer on top.
The practical test for which side of the split a given fact belongs on is ownership, not size: a product manual sits in the knowledge base because it is true for every user and every agent that queries it, while a user’s stated preference sits in the memory module because it is true for exactly one user and would be wrong to serve to anyone else. Teams that skip this distinction tend to store everything in one vector index and then discover, once 2 users share a query, that the retrieval layer has no concept of whose facts it just served.
Production reality
What breaks when the memory layer runs at production scale?
Two failure modes hit memory specifically, separate from the general operational load of running any model in production.
The first is drift, not in the model’s weights but in what it thinks it knows about a given user. A memory layer that extracted a preference 6 months ago and never revisited it will keep serving that stale fact with full confidence, because nothing about retrieval quality flags a fact as outdated on its own; only an explicit update or eviction policy does. This is the same failure this site’s own conflicting-memories and forgetting-and-eviction pages document from the storage side; here it shows up as a stack-design problem, since teams that skip a memory layer entirely also skip the update policy that would have caught it.
The second is cost that compounds per user rather than per request. A retrieval-only stack pays for search once per query; a memory layer pays for extraction on every write, storage that grows for as long as an account exists, and a retrieval step on every turn on top of whatever the retrieval layer already does. At meaningful user counts, that turns memory from a fixed infrastructure line item into one that scales with active users, which is the reason most teams choosing between the 5 tools in the table above weigh update-frequency and retention policy as heavily as raw benchmark scores.
Neither failure mode shows up in a demo. Both surface only once a memory layer has been running long enough, and across enough real users, for stale facts and storage growth to accumulate, which is exactly the gap between a working proof of concept and a stack that is actually ready for production traffic.
Decision
How do you choose a stack for your use case?
Match team skills, compliance requirements and use case, not hype.
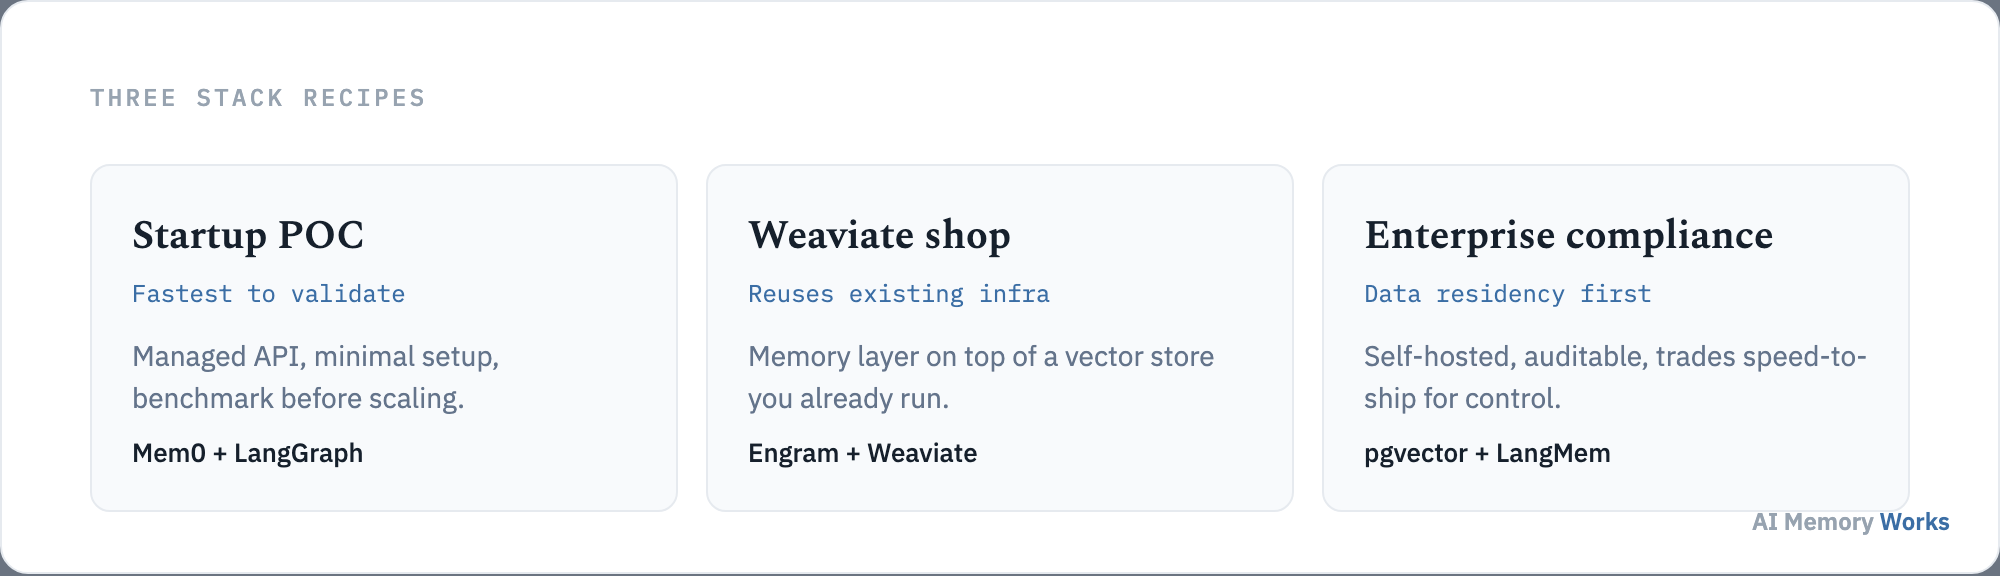
- Startup POC: Mem0 API + LangGraph; validate on LOCOMO before scaling
- Weaviate shop: Engram memory layer on existing Weaviate cluster
- Temporal reasoning: Zep knowledge graph for fact invalidation over time
- Long-context agents: Letta paging when context window limits bite
- Enterprise compliance: OSS stack (pgvector + LangMem) or self-hosted Zep
- Managed vs OSS: trade speed-to-ship against data residency and cost at scale
Orchestration-pattern choice (single agent, multi-agent, human-in-the-loop checkpoints) shapes how the memory layer gets called, but it’s a separate decision from which memory layer to run; see agentic architecture patterns for that side of the stack. In practice, the 2 decisions collapse into one question worth asking before any vendor call: does this agent need to recall one user across many sessions, or recall many documents within one session? The first points at the memory layer row in the table above; the second points at the retrieval layer, and a fair number of production stacks eventually need both rows filled in rather than picking one.
FAQ
Frequently asked questions
The layer placements, sub-types and vendor tradeoffs above, answered as direct questions.
What layers does an AI-native stack need?
Models, orchestration, retrieval/RAG, memory layer, vector store, observability and app/API. Memory is the layer most teams skip, and the one that separates demos from production agents.
Memory layer vs vector database?
Vector DB stores embeddings. Memory layer adds extraction, deduplication, update/forget policies and agent-oriented retrieval. See memory layer guide.
Where does Engram fit in the stack?
Between agent orchestration and Weaviate: a Weaviate-native memory layer with async extraction and hybrid search (GA June 2026). See Engram explained.
Mem0 vs building your own memory layer?
Engram is the Weaviate-native managed memory layer (GA June 2026). Mem0 is a framework-agnostic API alternative. DIY gives control but costs engineering time.
Typical LangGraph stack in 2026?
GPT-4o/Claude + LangGraph loops + Engram or Mem0 for memory + Weaviate or pgvector + LangSmith for evals.
Open-source vs managed memory in the stack?
Managed (Engram, Mem0, Zep cloud) ships faster. OSS (LangMem, self-hosted Zep) suits data residency. See OSS vs managed.
Is RAG a separate layer from memory?
Yes: RAG grounds answers in static documents. Memory stores per-user facts across sessions. Many production agents use both. See memory vs RAG.
What changed in AI-native stacks in 2026?
Memory layers went GA (Engram June 2026), LOCOMO/LongMemEval became standard CI gates, and context-engineering plus memory replaced raw long-context stuffing.
AI-native stack examples?
Weaviate shop: LangGraph + Engram. Support bot: LangGraph + Mem0 + Pinecone. Temporal agent: Zep + Neo4j. See use cases.
Deep dive on the memory layer?
See the memory layer in the AI-native stack: placement, evaluation criteria and implementation checklist.
What are the sub-types inside the memory layer?
In-context memory (current conversation turns), session memory (facts scoped to one active session), semantic memory (durable user facts and preferences), and structured enterprise memory (records tied to business systems). See memory layer guide.
Why do two different vendor architecture write-ups agree on a separate memory layer?
Impala Intech's 7-component framework and Techment's 6-layer framework were written independently, and both split memory out from retrieval and from knowledge-base storage. Convergent, independently-derived structure is stronger evidence than either source alone.