Fundamentals · How it works
How Does AI Memory Work? Write, Store, Retrieve, Forget
AI memory works as a loop: the agent writes what matters to a store outside the model, retrieves the relevant parts on each turn, updates them when facts change, and forgets what has gone stale. That loop is what turns a stateless model call into an assistant that still knows you next week. This page walks each operation, with the published latency and accuracy figures beside it.
The memory loop
The model
What are the four operations of AI memory?
Every production memory system runs the same four operations on every turn: write, store, retrieve, and forget or update. Tools differ in how each step is implemented, not in whether the step exists, which is why the loop is the right thing to learn before any individual product.
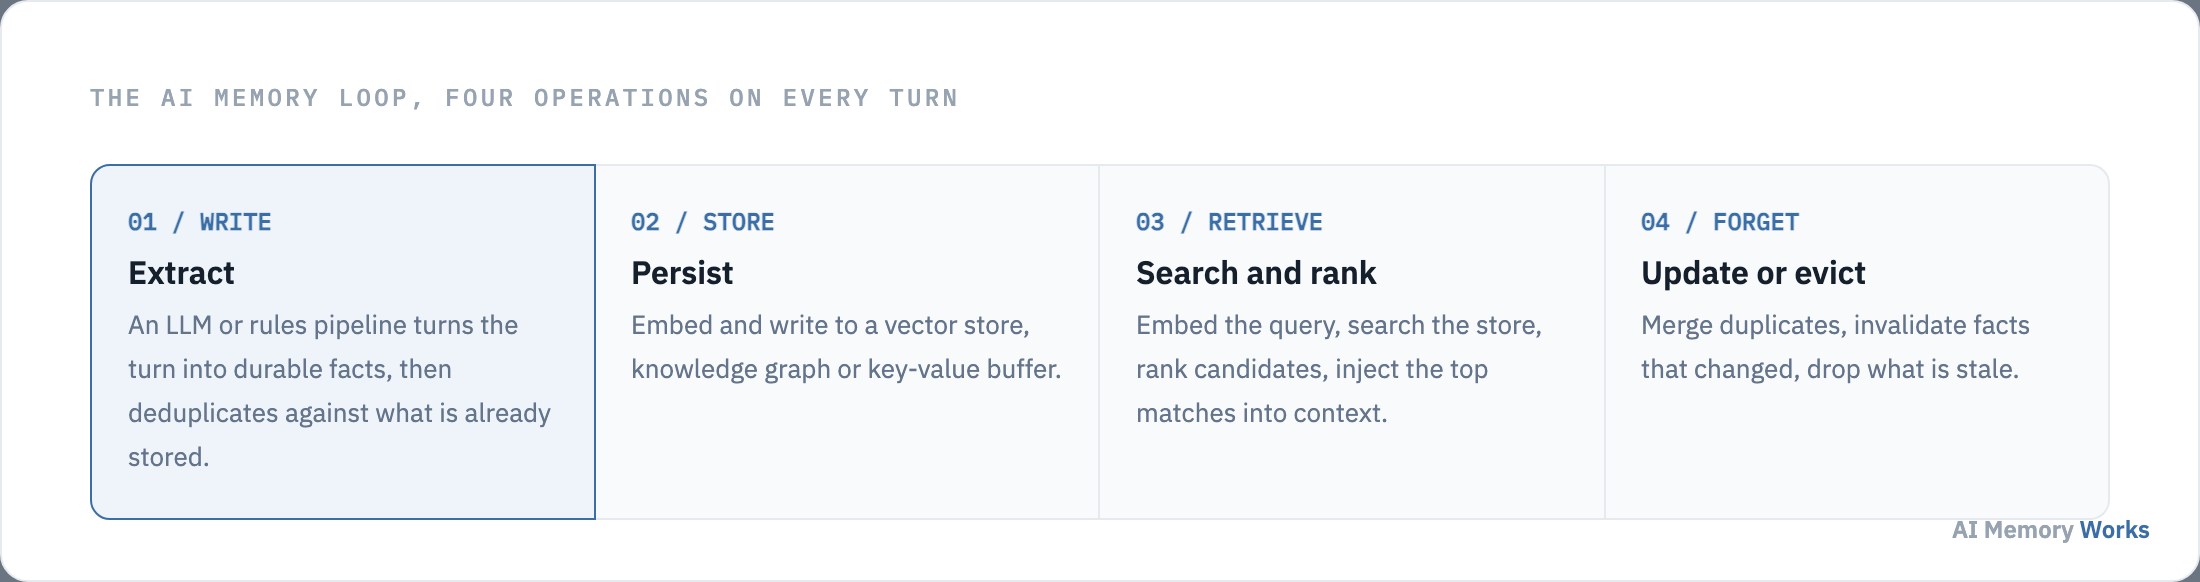
The loop is deliberately not the same as the model’s own inference. Nothing here changes the weights: the entire mechanism is external storage plus a decision about what to put into the prompt, which is what separates memory from fine-tuning.
The first operation is also the one that decides the quality of everything after it, because a store full of noise cannot be rescued by good retrieval: how an agent decides what to remember.
Step 1, write
How does an agent decide what to remember?
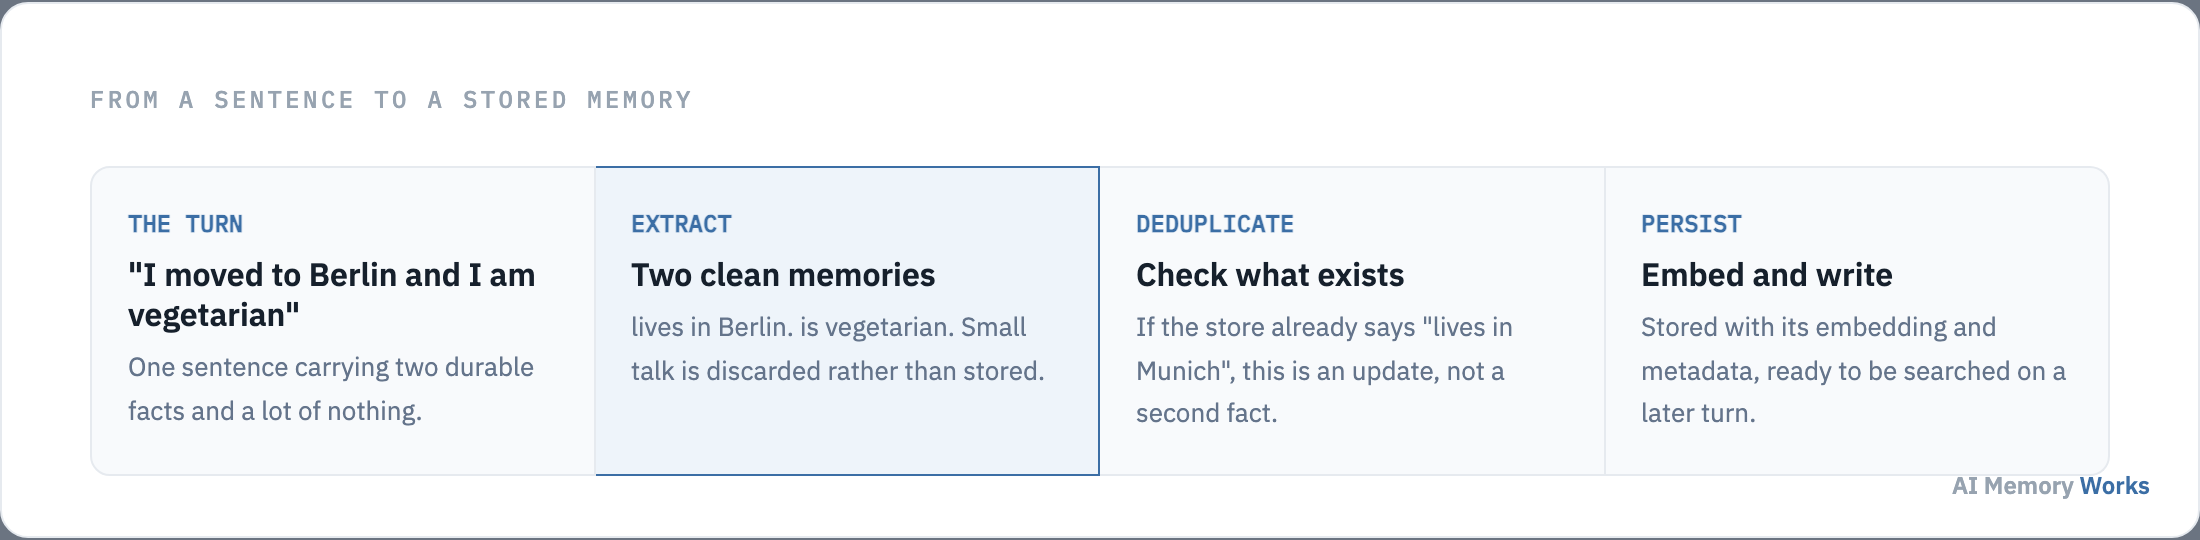
An extraction step reads each turn and keeps only the durable parts, turning conversation into a small number of clean facts before anything is stored. The trigger is usually end-of-turn processing, a tool call, or an explicit write such as Mem0’s memory add.
The worked example is the clearest way to see it. The sentence “I moved to Berlin and I am vegetarian” carries two facts worth keeping and a lot of phrasing that is not. Extraction produces “lives in Berlin” and “is vegetarian”, then checks them against what is already stored, so that a previous “lives in Munich” is treated as an update rather than as a competing fact.
Extraction quality is measurable rather than a matter of taste. The Mem0 paper (Chhikara et al., 2025) reports a LOCOMO LLM-as-a-judge score of 66.9 for its extract-and-store pipeline, and 68.4 with graph memory, against 72.9 for a full-context baseline that costs roughly fifteen times as many tokens. The full mechanism is covered in how agents write and store memories.
Once a fact has been extracted it has to live somewhere, and where it lives determines how fast it can be reached: where an agent’s memories are stored.
Step 2, store
Where are an agent’s memories stored?
In two places at once: a short-term store, which is the context window itself, and a long-term store outside the model, usually a vector database, a knowledge graph or a key-value buffer. The short-term store is fast and disappears at the end of the session. The long-term store survives and is reached only by an explicit search.
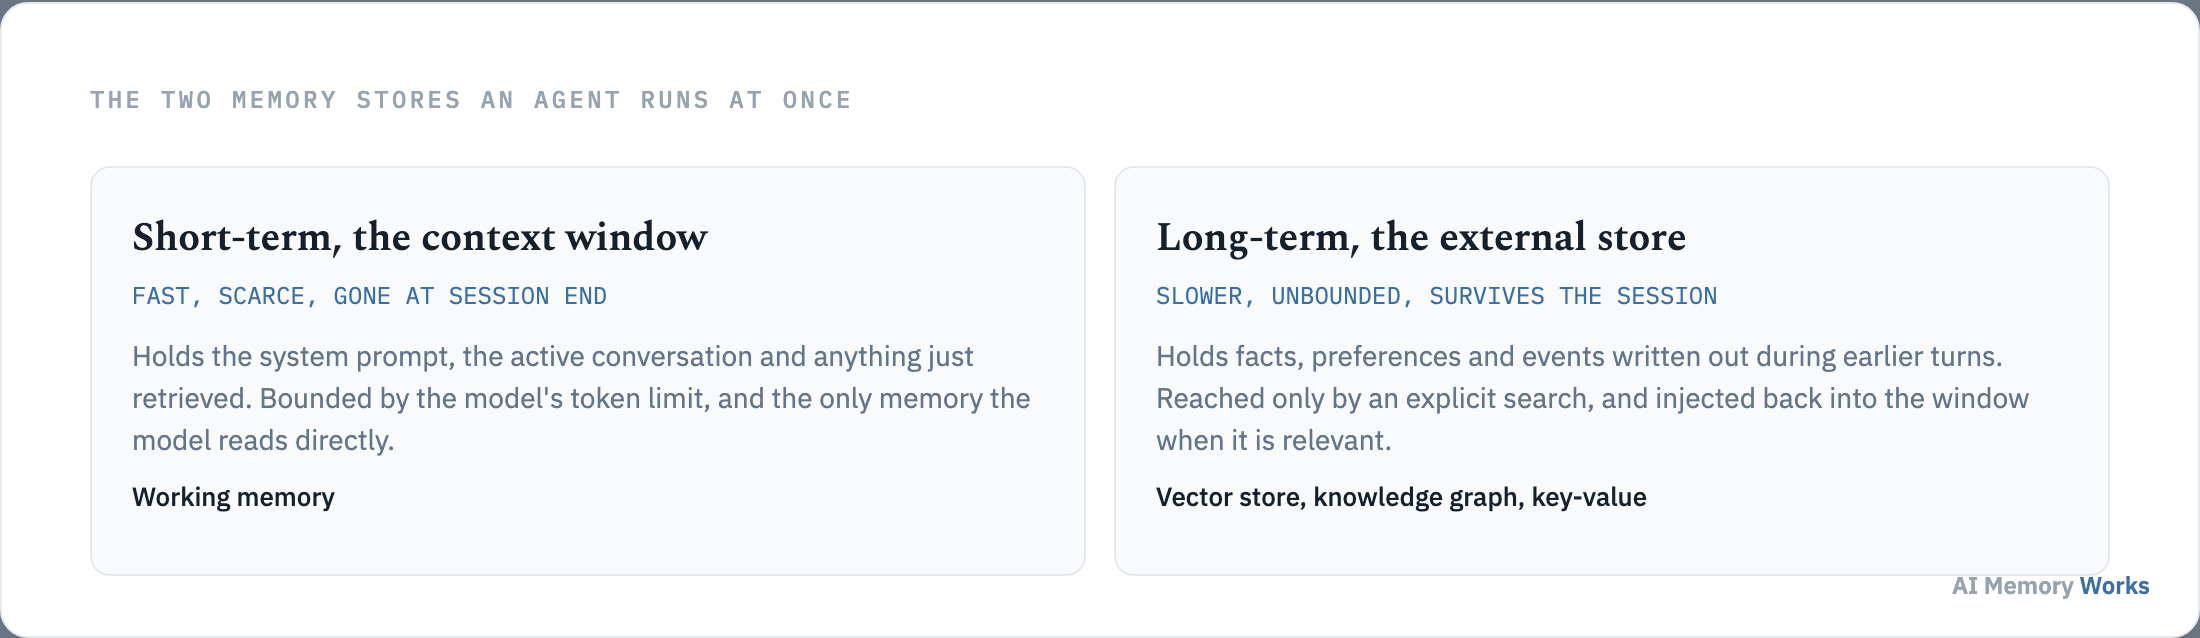
Production systems usually run three tiers rather than two: the context window as the hot tier, a fast buffer such as Redis as the warm tier, and a vector or graph store as the cold tier. The MemGPT research line (Packer et al., 2023) pages memories between those tiers the way an operating system pages between RAM and disk, and scores 93.4% on the Deep Memory Retrieval benchmark it introduced. Tiering is covered in what a tiered memory hierarchy is, and the paging design on what virtual context is.
Storing a fact is only useful if the right one comes back at the right moment, and that selection step is where most memory systems succeed or fail: how an agent finds the right memory.
Step 3, retrieve
How does an agent find the right memory?
Retrieval runs before the answer: the agent embeds the incoming query, searches the store, ranks the candidates, and injects only the top matches into the context window. Semantic vector search is the default, and production systems add recency weighting, keyword matching and graph traversal on top of it.
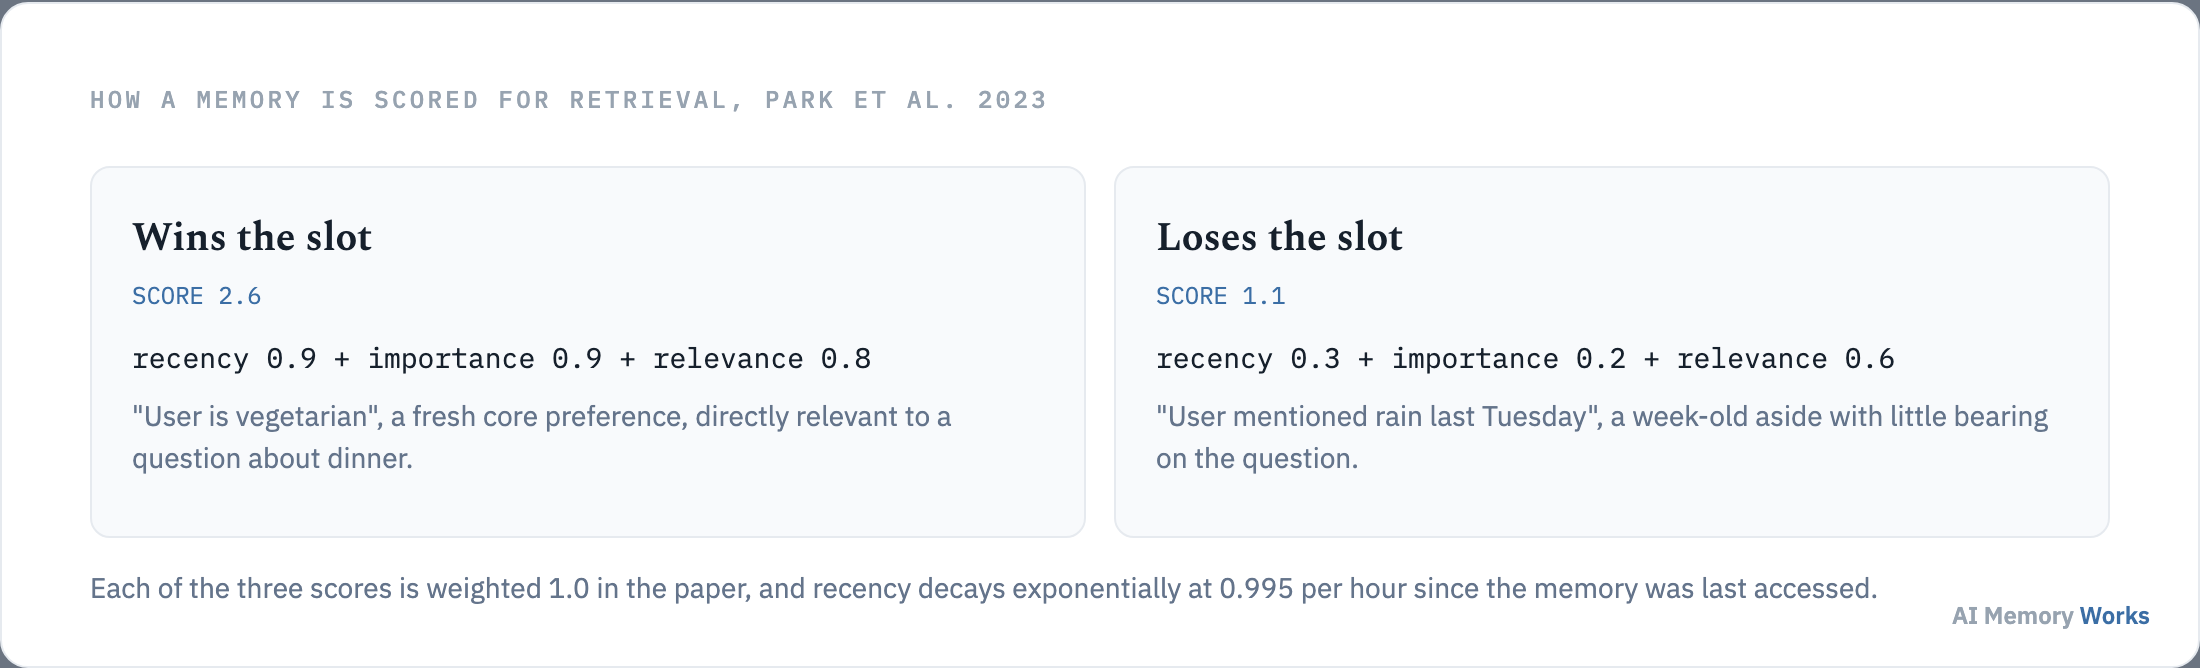
The canonical scoring formula comes from the Generative Agents paper (Park et al., 2023), which scores each memory on recency, importance and relevance, implemented as a weighted sum of the three normalised scores with each weight set to 1.0, and with recency decaying exponentially at 0.995 per hour since the memory was last accessed.
Selective retrieval is also the reason memory is cheaper than resending the transcript. On the LOCOMO benchmark, Mem0 retrieves with a median search latency of 0.148 seconds and answers with a p95 total latency of 1.44 seconds, against 17.1 seconds for a 26,000-token full-context baseline, a 91% reduction, while consuming roughly 1,800 tokens per query instead of 26,000 (Chhikara et al., 2025). The mechanism is covered in memory retrieval and the ranking detail in scoring and ranking memories.
Retrieval assumes the stored fact is still true, which is an assumption with a shelf life: how an agent updates and forgets.
Step 4, update and forget
How does an agent update or forget a memory?
When new information arrives the agent either updates the existing memory, merges duplicates into one, or invalidates the old version, and it evicts what has gone stale so the store does not grow without limit. Consolidation usually runs between sessions or as a background job rather than in the middle of a turn.
Updating properly is worth real accuracy. Zep’s temporal knowledge graph, which invalidates superseded facts instead of deleting them, improved LongMemEval accuracy by up to 18.5% over a full-context baseline while cutting response latency by around 90% (Rasmussen et al., 2025). Keeping the superseded version is what allows an agent to answer questions about what used to be true.
Forgetting is the operation teams skip, and it fails quietly. Without eviction the store grows unbounded, retrieval slowly degrades as near-duplicates compete, and contradictory facts sit side by side with equal confidence. Time-to-live rules, decay policies and relevance pruning are covered in forgetting and eviction, and the merge step in memory consolidation.
That is the whole loop as an engineer sees it. Most people meet AI memory from the other side, as users of an assistant that suddenly knows things, which raises a fair question: does AI remember everything you say.
From the user’s side
Does AI remember everything you say?
No. An assistant with memory stores a small, filtered set of facts it judged durable, not a transcript of the conversation. The extraction step described above exists precisely to throw most of the conversation away, because storing everything makes retrieval worse rather than better.
Three consequences follow, and they explain most of the surprising behaviour people notice.
- It forgets things you thought were important. If extraction did not classify a detail as durable, it was never written, and no amount of asking will recover it from a later session.
- It remembers things you would rather it did not. A stated preference is exactly the kind of fact extraction is built to keep, including ones you mentioned once in passing.
- It can be wrong in a stable way. A fact stored before it changed will keep being retrieved until something invalidates it, which is the failure temporal memory addresses.
Within a single session the behaviour is different again, because the whole conversation is still in the context window and nothing has been filtered yet. That distinction is the subject of memory versus the context window, and the privacy dimension is one to raise with whichever tool you use rather than assume.
The related question people ask most often is about the limit itself: what happens when an assistant’s memory is full.
Limits
What happens when an assistant’s memory is full?
Two different limits get called “full”, and they behave in opposite ways. Confusing them is why the same phrase produces contradictory answers.
- The context window fills up during a conversation. This is the hard, technical limit, and something has to leave. Systems either drop the oldest turns, or summarise them into a shorter form, or page them out to external storage the way MemGPT does at a 70% threshold. Detail is lost in every case except paging, which can retrieve the original back.
- The long-term store hits a product limit. This is a policy choice by the vendor rather than a property of the model, and the usual behaviour is to stop writing new memories, or to evict the least useful ones, and to ask the user to delete some.
The practical consequence for a user is that “memory full” rarely means the assistant has lost anything permanently. It means the assistant has stopped adding, or has started compressing. For a builder the consequence is that an eviction policy is a design decision to make on purpose, since the default of never forgetting is the one option that reliably degrades.
All four operations have to be triggered by something, which raises the last structural question: which frameworks implement the loop for you.
Implementations
Which frameworks implement the memory loop?
A memory-management layer decides when each operation runs, and it is either a framework you adopt or code you write over a store such as Redis or pgvector. The table maps the main options onto the loop above.
| Class | Tool | How it runs the loop |
|---|---|---|
| Vector-native layer | Engram (Weaviate) | Managed extract, transform and commit pipeline on Weaviate |
| Memory API | Mem0, Supermemory | Managed write and retrieve calls the application makes |
| Temporal graph | Zep | Graph write plus temporal invalidation of superseded facts |
| Virtual paging | Letta (MemGPT) | Tiered stores the agent pages in and out itself |
| Framework-native | LangMem | Checkpointer plus store inside LangGraph |
| Build it yourself | Redis, pgvector | You implement each operation and its triggers |
One distinction worth keeping straight while choosing: retrieval-augmented generation reads from a fixed corpus somebody else wrote, while memory reads and writes state produced by the interaction itself. Most real systems run both, covered in memory versus RAG and how to combine RAG and memory.
The full comparison, with the published benchmark numbers and the deployment models, is on the best AI memory tools.
FAQ
Frequently asked questions
These cover the questions that follow the loop itself: what memory costs, how it differs from a longer context window, and what an agent does on its very first turn.
How do AI agents store memory?
After each turn, an extraction pipeline decides what is worth remembering, embeds it, and writes to an external store (vector DB, graph or KV). See writing and storing memories.
What role does a vector database play in AI memory?
Vector databases index embeddings so agents can find memories by semantic similarity — the typical backend for long-term semantic and episodic memory. See vector databases for memory.
How is memory retrieved in AI agents?
Before each response, the agent embeds the query, searches the store, ranks candidates by relevance and recency, and injects top matches into the prompt. See memory retrieval.
Do AI agents forget memories?
Yes — production agents evict stale, irrelevant or contradictory memories via TTLs, decay and relevance pruning. Without forgetting, retrieval quality degrades. See forgetting and eviction.
What is the difference between AI memory and the context window?
The context window is working memory for the current session only. AI memory persists in external stores across sessions. See memory vs context window.
Is AI memory the same as RAG?
No. RAG retrieves from a fixed document corpus. AI memory is dynamic and personal — updated across sessions. See memory vs RAG.
What is memory consolidation?
Consolidation merges short-term memories, summarizes threads and promotes them to durable long-term storage — often between sessions. See memory consolidation.
What is MemGPT memory paging?
MemGPT treats the context window like RAM and pages memories between a fast tier and deep store — effectively unbounded conversation history. Letta implements this pattern. See virtual context and MemGPT.
How do I build AI memory from scratch?
Pick a store, implement write after each turn, retrieve before each response, and add eviction policies. Or use a framework like Engram, Mem0 or LangMem. See add memory to an agent.
How do I measure AI memory quality?
Use LOCOMO (long-conversation recall) and LongMemEval (cross-session recall), plus track latency and token cost. See evaluation hub.