Advanced · Learning
Continual Learning and AI Agent Memory
Writing facts to memory is not the same as continual learning, and recent research shows why: the problem that makes weight updates hard, old knowledge competing with new, resurfaces inside memory retrieval instead of disappearing. Memory sidesteps the specific dangers of updating a model’s weights. It does not sidestep the underlying dilemma. Knowing the difference changes what you should expect a memory system to do for you.
Three layers
Definition
What does continual learning mean for an agent that already has memory?
Getting better at a task over time, without forgetting what already worked. That is the whole requirement, and it says nothing about which mechanism has to deliver it. Continual learning is usually defined at the level of a model updating its own weights on a stream of new data while retaining performance on old data. An agent with a working memory system already improves over time in a weaker sense: it accumulates facts and stops repeating mistakes it has a record of.
Whether that weaker sense is enough is the actual disagreement in this space, and it splits capable people. One camp argues that accumulating facts in an external store is functionally equivalent to learning, because the agent’s behaviour changes and improves as a result. Another camp argues that this is retrieval dressed up as learning, because nothing about the agent’s own capability has changed, only what it has been handed to read.
Both camps are pointing at something real, and the disagreement resolves once you separate two different things memory can be asked to do. It can make previously stated facts available again, which no one disputes it does well. Whether that also counts as learning, in the sense of the agent generalising from experience rather than looking it up, is a separate question with a specific answer: does writing facts to memory count as continual learning?
The core disagreement
Does writing facts to memory count as continual learning?
It substitutes for the update mechanism and leaves the underlying dilemma standing. The strongest argument against treating memory as a solved version of continual learning is that retrieval never forces the compression that makes learning powerful in the first place: a model that can look up any fact has not been forced to find the structure behind it, only to store it.
Recent research puts a sharper point on this. A 2026 study of memory-augmented agents shows that the stability-plasticity dilemma, the classic tension between retaining old knowledge and acquiring new knowledge that makes weight updates hard, does not disappear when learning moves to an external memory. It resurfaces at the memory level: under a bounded context window, old and new experiences compete during retrieval, which relocates the bottleneck from parameter updates to memory access rather than removing it.
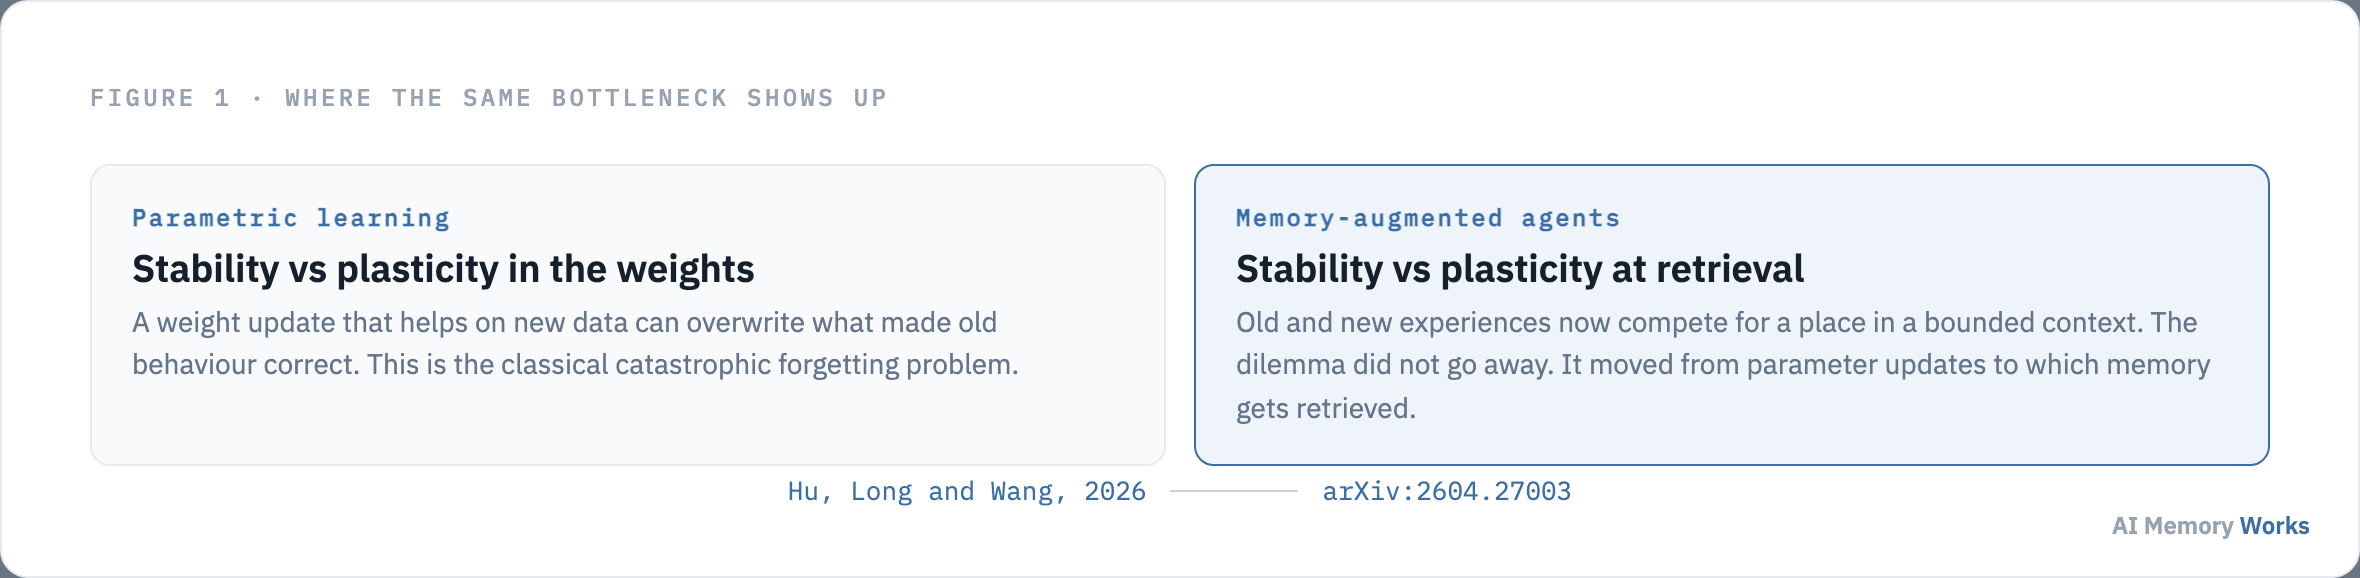
That reframes the question builders should actually be asking. Not “does my agent have memory” but “when an old memory and a new one compete for a place in the prompt, which one wins, and is that the one that should.” That is exactly the job of memory scoring and of conflict resolution, and it means those two pages are doing real continual-learning work even though neither one touches a weight.
So the honest answer is neither yes nor no. Memory substitutes for the update mechanism in weight-based learning and inherits a version of its central problem rather than escaping it. What it clearly does avoid is a separate set of failure modes that come specifically from updating weights: what can memory not do that a weight update can?
The honest limit
What can memory not do that a weight update can?
Encode a pattern that cannot be put into words. This is the strongest limit on memory as a learning substrate, and stating it plainly is more useful than pretending memory is a complete replacement for weight updates.
A memory record is text. It can hold a preference, a fact, a summary of an outcome, anything that can be said in a sentence. Some patterns genuinely cannot be. The visual texture that separates a benign anomaly from a serious one in a scan, the micro-variation in audio that identifies a speaker, the tacit feel of a well-formed piece of code that an experienced engineer recognises before they can articulate why: these live in a kind of representation that a written memory cannot capture, no matter how long the record or how good the retrieval.
There is a related and more common failure that looks like the same limit and is not. Facts pile up in memory as loose, unconnected statements, and the agent never compresses them into a general rule; ask a slightly different question and it fails to apply what it was “told” in a different phrasing. That is not a fundamental limit of memory, it is a consolidation problem, and it is fixable by summarising and generalising stored records rather than leaving them as a flat pile, which is what memory consolidation is for.
So the real limit is narrower than it first appears: memory cannot hold what cannot be expressed in language. For the very large majority of what an agent needs to remember about a user, a task, or a decision, that boundary is rarely reached. It is worth knowing where it sits so you stop asking memory to do a weight update’s job.
Naming model weights as one place learning can happen raises an obvious question: where else can it happen, and is memory even the right name for the third place? where does learning actually happen: the model, the harness, or memory?
Three layers
Where does learning actually happen: the model, the harness, or memory?
All three, and most discussions of continual learning only name the first one. An agentic system is not just a model. It is a model, a harness of code and instructions that drives every run, and context that configures the harness for a particular user or task. Learning can happen at any of the three, and they improve on completely different timescales.
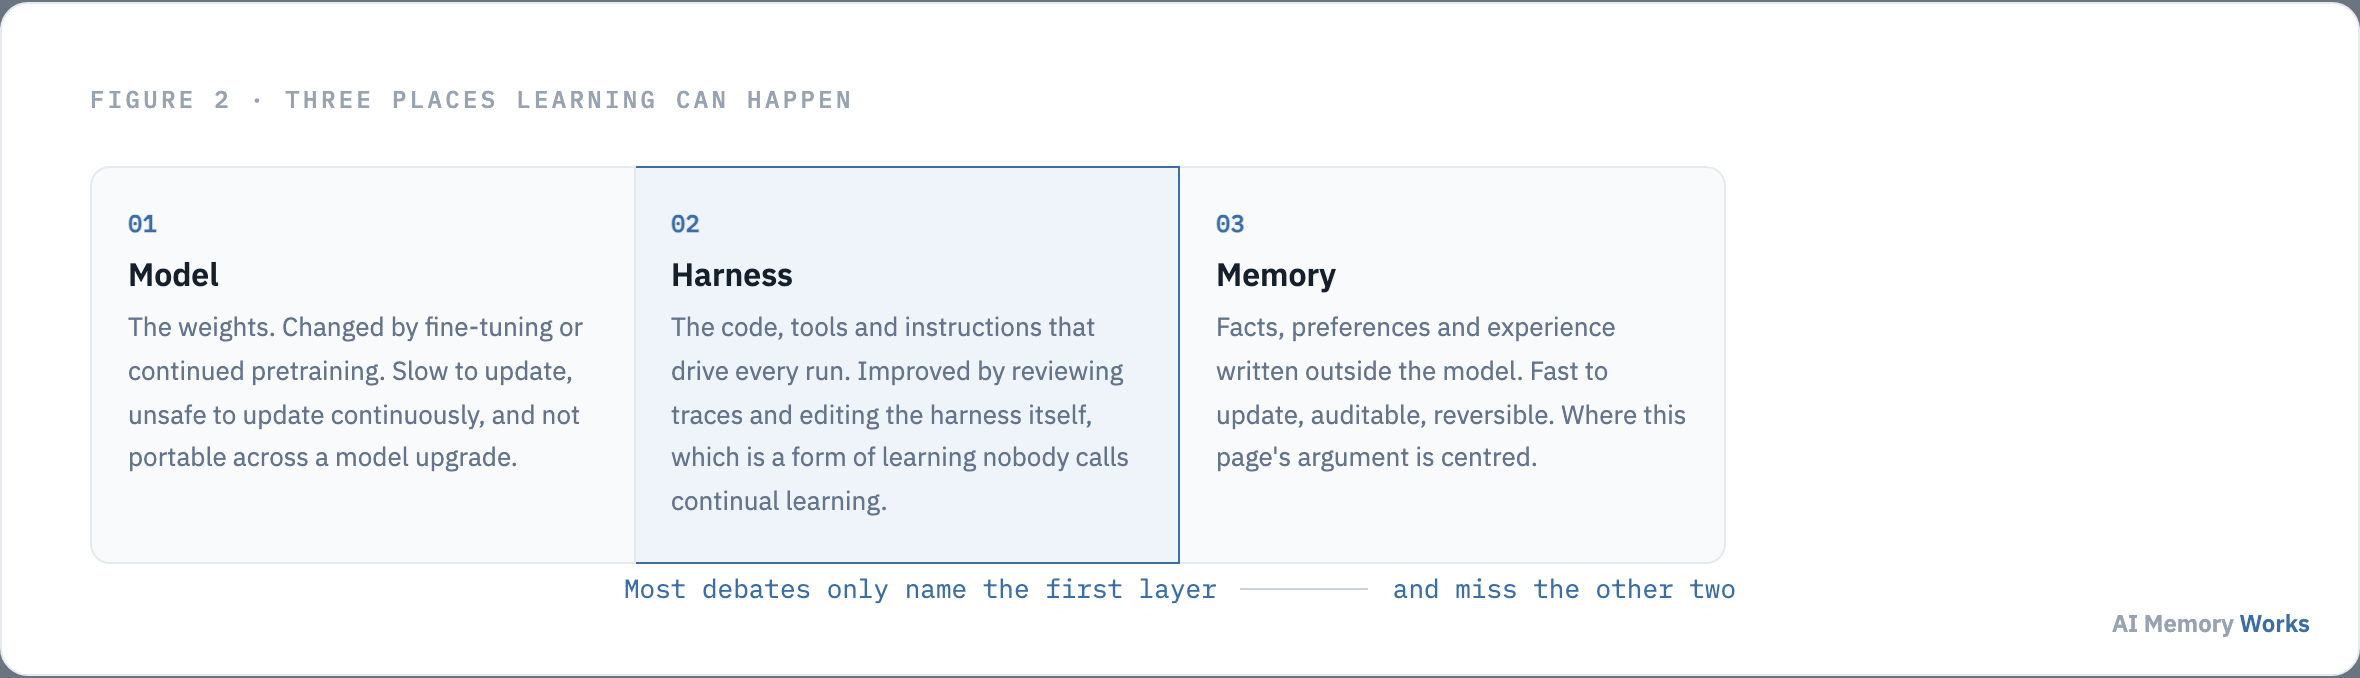
The model layer is what people usually mean by continual learning, and it is the slowest and riskiest to change, for reasons covered next. The harness layer improves when someone, or increasingly an agent reviewing its own traces, edits the code, instructions or tools that drive every run. That is a real form of learning that benefits every user of the system at once, and it happens on a release cadence rather than in real time.
The memory layer is the fastest of the three and the only one scoped to an individual user or session by default. A fact written to memory is available on the next turn, reversible by retiring the record, and inspectable by reading a row in a database. None of that is true of a weight update or, usually, of a harness change.
Seen this way, the interesting design question is not whether to use memory instead of continual learning, but which layer a given piece of learning belongs on. A correction the user makes about their own preferences belongs in memory. A pattern that would help every user of the product belongs in the harness. A capability that cannot be expressed in language at all is the narrow case that might justify touching the model, and that case is rarer than it sounds.
Given how much faster and safer the memory layer is to change, it is worth asking directly why the model layer is treated so cautiously in comparison: why do practitioners avoid continuous weight updates in production?
Why memory wins in practice
Why do practitioners avoid continuous weight updates in production?
Two independent reasons, and together they are the strongest practical argument for memory over fine-tuning. Neither is about which substrate can represent more. Both are about what happens after you ship.
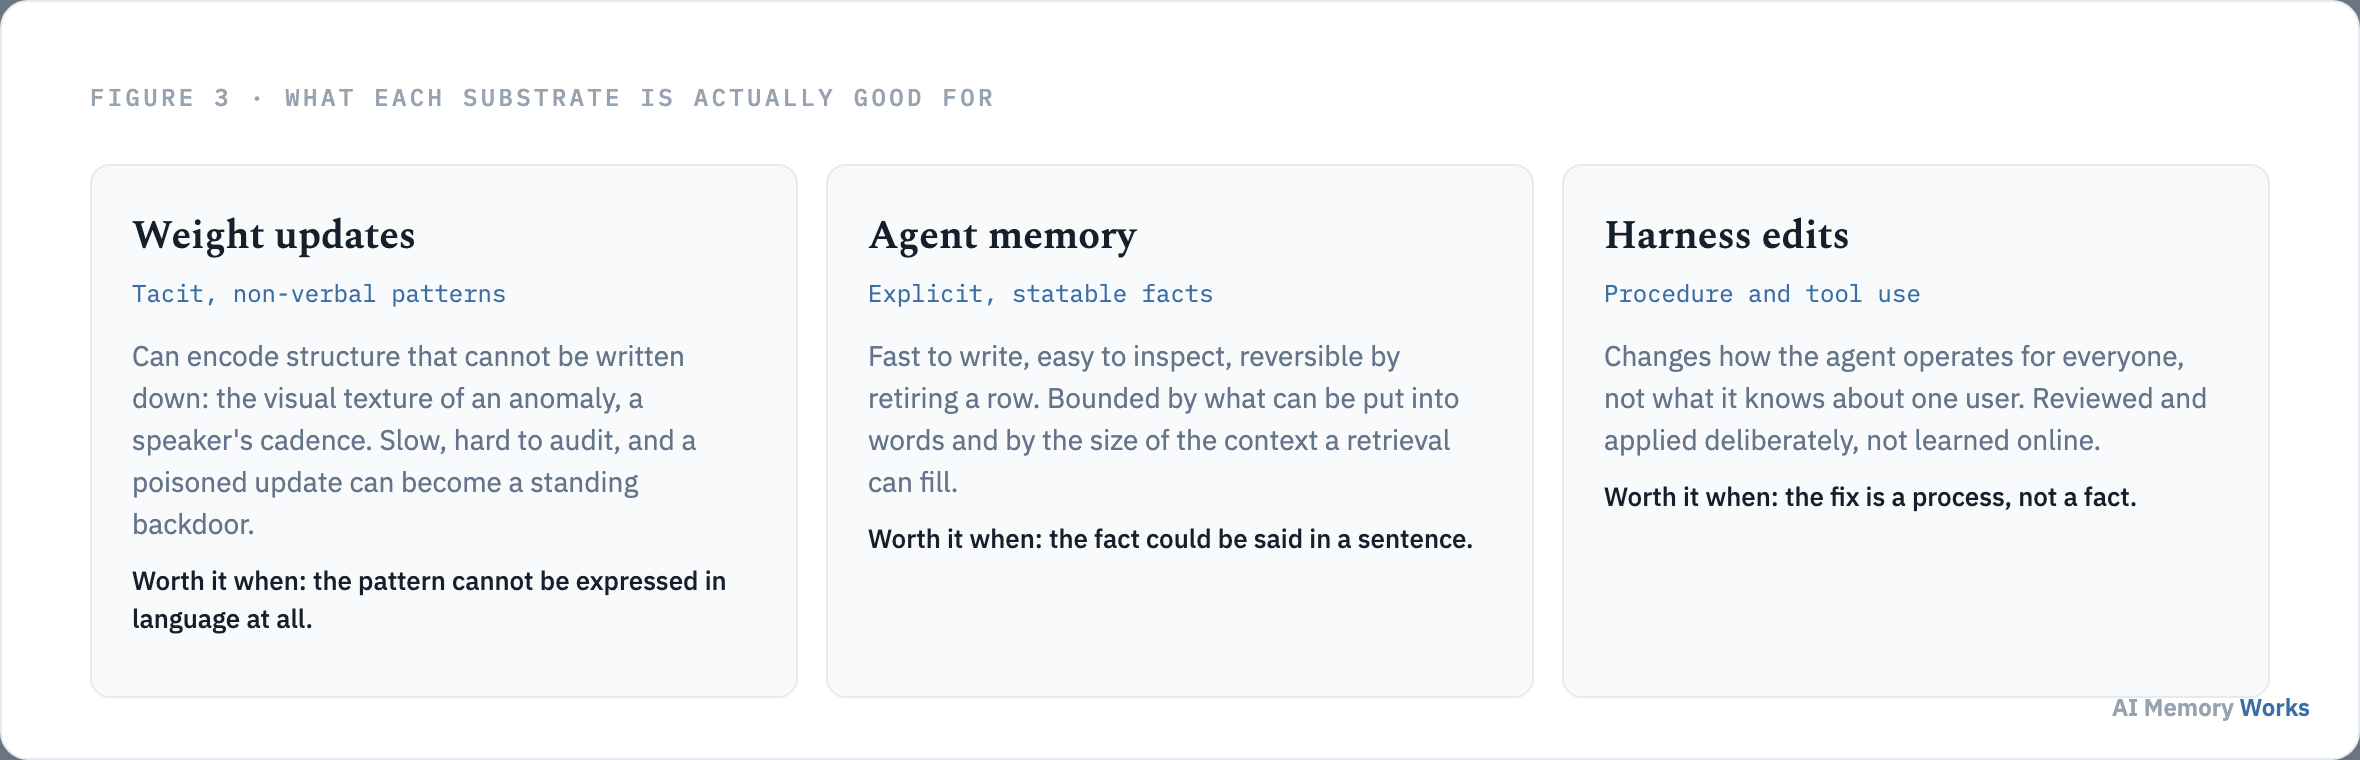
The first is safety. Prompt injection is already a known risk for systems that read untrusted content. A model that updates its own weights continuously opens a slower, quieter version of the same attack: a poisoned training signal becomes a standing change to the model rather than a single bad response, so an attacker can plant something and wait, and the effect can trigger later even in a context that was never itself compromised. A memory record carries no equivalent risk to the model, because a bad write is one row that can be reviewed, scored and retired, and it never changes what the model knows for every other user.
The second is portability. Whatever a continuously updated model has learned is encoded in its weights, tied to that specific architecture. When a better model becomes available, upgrading means either losing everything that was learned or hoping a portable adapter happens to transfer, which it may not if the architecture changed. A memory store has no such coupling: the facts are just rows, readable by whatever model is asking, so upgrading the model changes nothing about what the agent knows.
Read together, these two arguments say something neither one says alone: memory’s advantage over weight updates in practice may have less to do with what it can represent than with being auditable, reversible and detachable from any specific model. That is a property worth wanting even where memory’s representational limits, covered above, are a real constraint.
None of this means memory has escaped catastrophic forgetting. It has a version of that problem too, and it is worth being precise about what changed and what did not: does memory avoid catastrophic forgetting, or just relocate it?
The parallel failure
Does memory avoid catastrophic forgetting, or just relocate it?
It avoids the parametric version and acquires a retrieval version instead. Catastrophic forgetting in a trained model means a weight update that helps on new data overwrites the representation that made old behaviour correct, silently and all at once. Nothing in a memory store gets overwritten that way, so in the narrow, original sense, memory does avoid it.
What a memory system gets instead is subtler and just as damaging in practice. A bounded context window means only a limited number of retrieved memories reach the prompt on any turn, so old and new experiences compete for those slots. The research already cited found something specific and non-obvious here: memory designs that improve how well relevant experience transfers across tasks can simultaneously make forgetting worse, because a more finely organised memory surfaces more candidates that compete with each other.
The everyday version of this is familiar from forgetting and eviction: a stale fact that nothing has contradicted keeps winning a retrieval slot over the current one, not because it was overwritten, but because it was never asked to step aside. The mechanism is different from parametric forgetting. The user-visible outcome, the agent acting on something outdated, looks the same.
The practical implication is that memory does not let you stop worrying about forgetting. It moves the place you have to solve it, from a training pipeline to a scoring and eviction policy, which is a much easier place to instrument, test and fix. Given that the fix now lives in retrieval design, what should actually be written to memory to make it work well: what should a memory system store so experience actually transfers?
What to store
What should a memory system store so experience actually transfers?
Abstracted procedure rather than raw trajectory. This is the one place in the debate where a controlled experiment, rather than an argument, gives a direct answer.
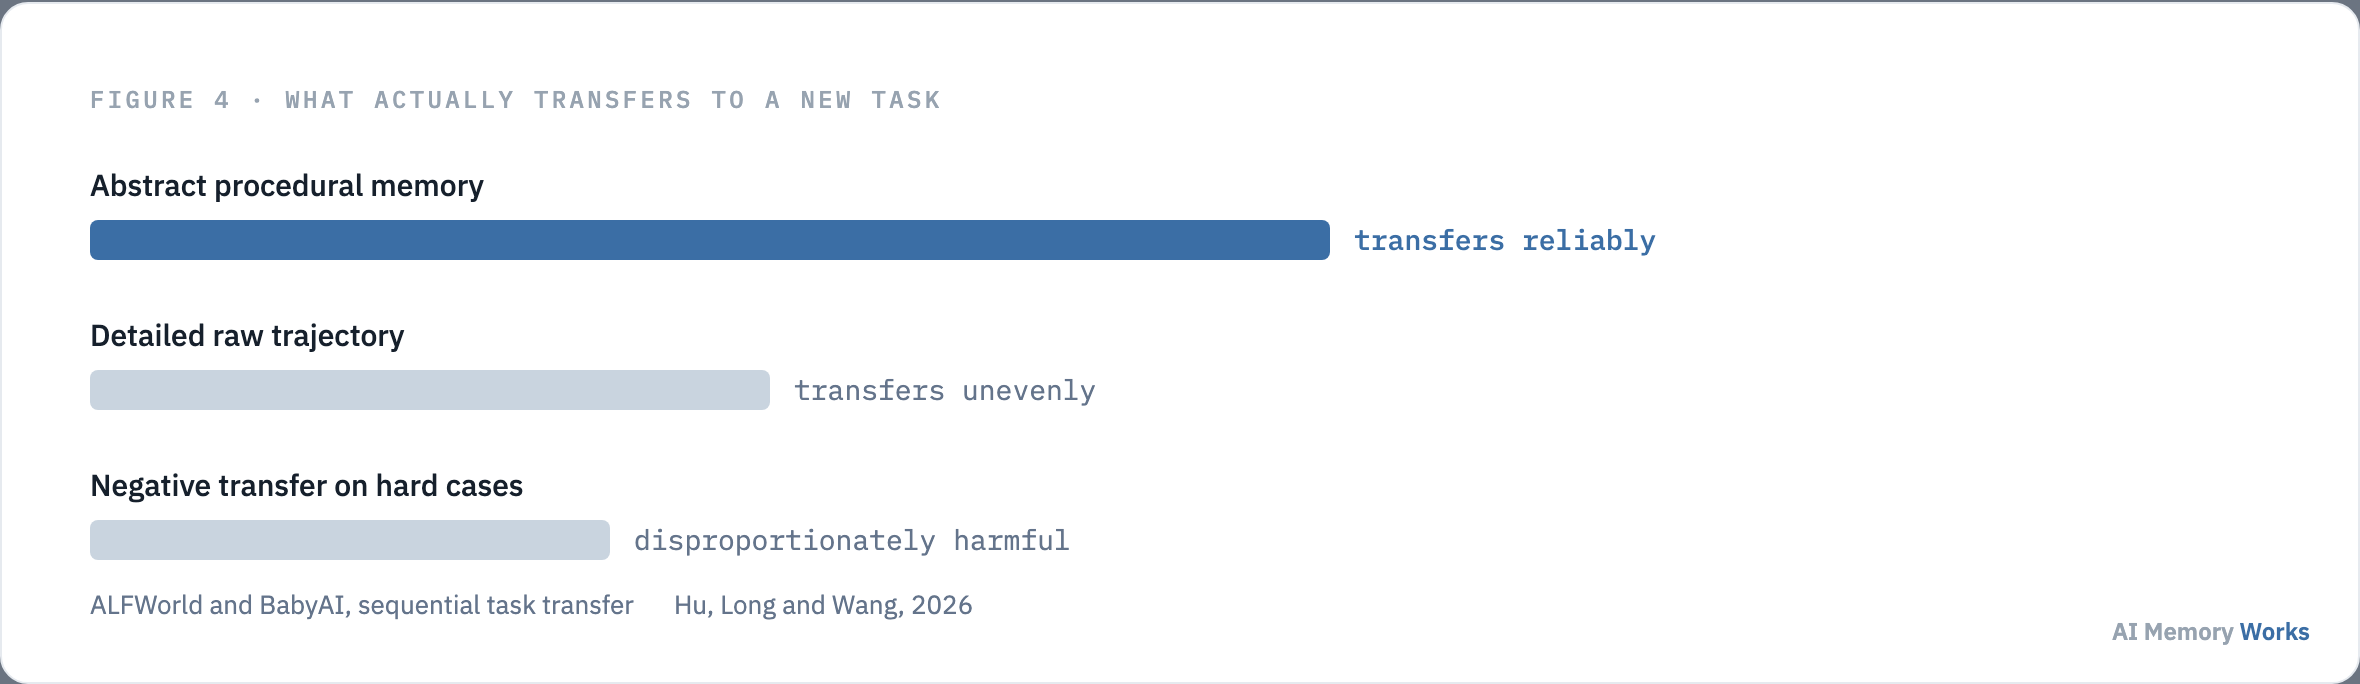
Testing sequential tasks in the ALFWorld and BabyAI environments, the study found that abstract procedural memories, summaries of what worked and why, transfer more reliably to a new but related task than detailed trajectories, meaning a step-by-step log of exactly what happened. A raw trajectory carries specifics that only applied to the situation it came from, and an agent trying to reuse it has to work out which parts generalise. An abstracted memory has already done that work.
The same study found the opposite risk is real too: negative transfer, meaning a stored memory that actively misleads on a new task, disproportionately harms the hardest cases. This matters for the design of any system, and it means a memory bank is not automatically safer the more it stores. A store full of narrowly specific trajectories can transfer worse than a smaller store of well-abstracted lessons.
This lines up with, and gives evidence for, something this site already argues on writing memories and memory consolidation: extraction and consolidation are not housekeeping, they are what makes stored experience usable later. A system that logs everything and abstracts nothing is building the raw-trajectory case the research found transfers worse.
With the mechanism, the limits and the evidence in view, the practical question a builder actually faces is simpler than the debate above suggests: should your agent use memory, fine-tuning, or both?
The decision
Should your agent use memory, fine-tuning, or both?
Memory first, always, and fine-tuning only for the narrow case memory genuinely cannot cover. The case for that ordering is not that memory is superior in every dimension. It is that memory is faster to build, safer to run, reversible when wrong, and portable across model upgrades, while fine-tuning solves a real but narrower problem at a much higher operational cost.
Reach for memory when the thing to be learned can be stated as a fact, a preference, or a lesson about what worked: almost everything a personalisation, support, or planning agent needs day to day. Reach for consolidation and better extraction, not more storage, when memory holds the fact but the agent still fails to apply it in a slightly different phrasing; that is a compression problem inside memory, not evidence that memory itself has failed. Reach for a harness change when the fix should apply to every user of the system rather than one person’s history. Reserve a weight update for the narrow, genuinely rare case where the pattern cannot be expressed in language at all, and go in with eyes open about the safety and portability costs above.
The detailed mechanism-level comparison between memory and fine-tuning, including cost, latency and what each actually changes at inference time, is on memory vs fine-tuning. This page answers the higher question that comparison assumes you have already settled: whether memory is a real substitute for continual learning at all, or a different name for retrieval. The honest answer is that it substitutes for the update mechanism and inherits a version of the same dilemma, which is exactly why the scoring and consolidation work described on memory scoring and memory consolidation is not optional polish. It is the part of continual learning that moved into memory’s court.
FAQ
Frequently asked questions
The follow-up questions builders ask once the model-versus-memory question is settled.
Is retrieval-augmented generation a form of continual learning?
In the weak sense of changing the agent's available knowledge over time, yes. In the strict sense used in machine learning, where a model updates its own weights and retains performance across a stream of tasks, no. RAG and agent memory both change what the agent can say without changing what the model itself has learned.
Does adding more memory make an agent smarter?
Not by itself. Recent research found that memory designs which improve how well experience transfers to new tasks can simultaneously increase forgetting, because a more finely organised store surfaces more competing candidates. More storage without better scoring and consolidation can make retrieval worse, not better.
When is fine-tuning actually worth it instead of memory?
When the pattern to be learned cannot be expressed in language at all, such as a visual or acoustic pattern, or when the same behaviour change needs to apply consistently to every user regardless of their individual memory. Both are narrower cases than most teams assume before they check.
Can an agent's harness learn without touching the model or memory?
Yes. Reviewing execution traces and editing the harness code, prompts or tools that drive every run is a real form of improvement that benefits every user at once. It happens on a release cycle rather than in real time, and it is a separate layer from both the model and per-user memory.
Does memory solve catastrophic forgetting?
It removes the parametric version, where a weight update silently overwrites old behaviour, and introduces a retrieval version, where old and new memories compete for a limited number of slots in the context. The fix moves from a training pipeline into a scoring and eviction policy, which is easier to test but does not disappear.
What is the safest way to let an agent improve from experience?
Write facts to memory rather than to weights, consolidate and abstract what is stored rather than logging raw trajectories, and score retrieval so current facts beat stale ones. That combination gets most of the practical benefit of continual learning without the safety and portability costs of updating a model continuously.