Architecture · Operations
How Memory Management Actually Runs
Memory management is what happens the moment an agent’s context gets compacted: raw conversation gets extracted, verified against the source, classified, and either stored as a new fact or used to supersede an old one, all before the model ever sees it again. A shipped system’s own engineering writeup shows what this looks like in practice, down to specific pipeline stages and a counterintuitive finding about which model size belongs where.
Runtime loop
The trigger
When does memory management actually happen at runtime?
At compaction, the moment an agent’s harness shortens context to stay within a model’s limits or to avoid the accuracy loss covered on this site’s context rot page. Most agents today simply discard everything at that moment. Memory management is the discipline of preserving what matters instead of losing it.
An agent, described structurally, has three parts: a harness that drives repeated model calls and manages state, a model that takes context and returns completions, and state, everything outside the current context window, conversation history, files, databases, memory. Compaction is the point where the harness has to decide what survives and what gets dropped, and it’s exactly the moment context rot’s underlying mechanism, a fixed attention budget stretched across too many tokens, makes that decision necessary in the first place. A real memory-management system integrates at this trigger in two ways: bulk ingestion of the compacted conversation into durable storage, and lightweight tools, recall, remember, forget, list, that let the model interact with memory directly without designing its own storage strategy.
Once a conversation reaches the ingestion step, the actual work of turning raw messages into durable, trustworthy memory begins. What actually happens during ingestion?
Turning conversation into memory
What actually happens during ingestion?
Extraction, verification, classification, then either a new memory or a versioned supersession of an old one, never a silent overwrite. A published engineering report from Cloudflare, describing its own shipped Agent Memory product, documents each of these stages concretely enough to serve as a real design reference rather than an abstract description.
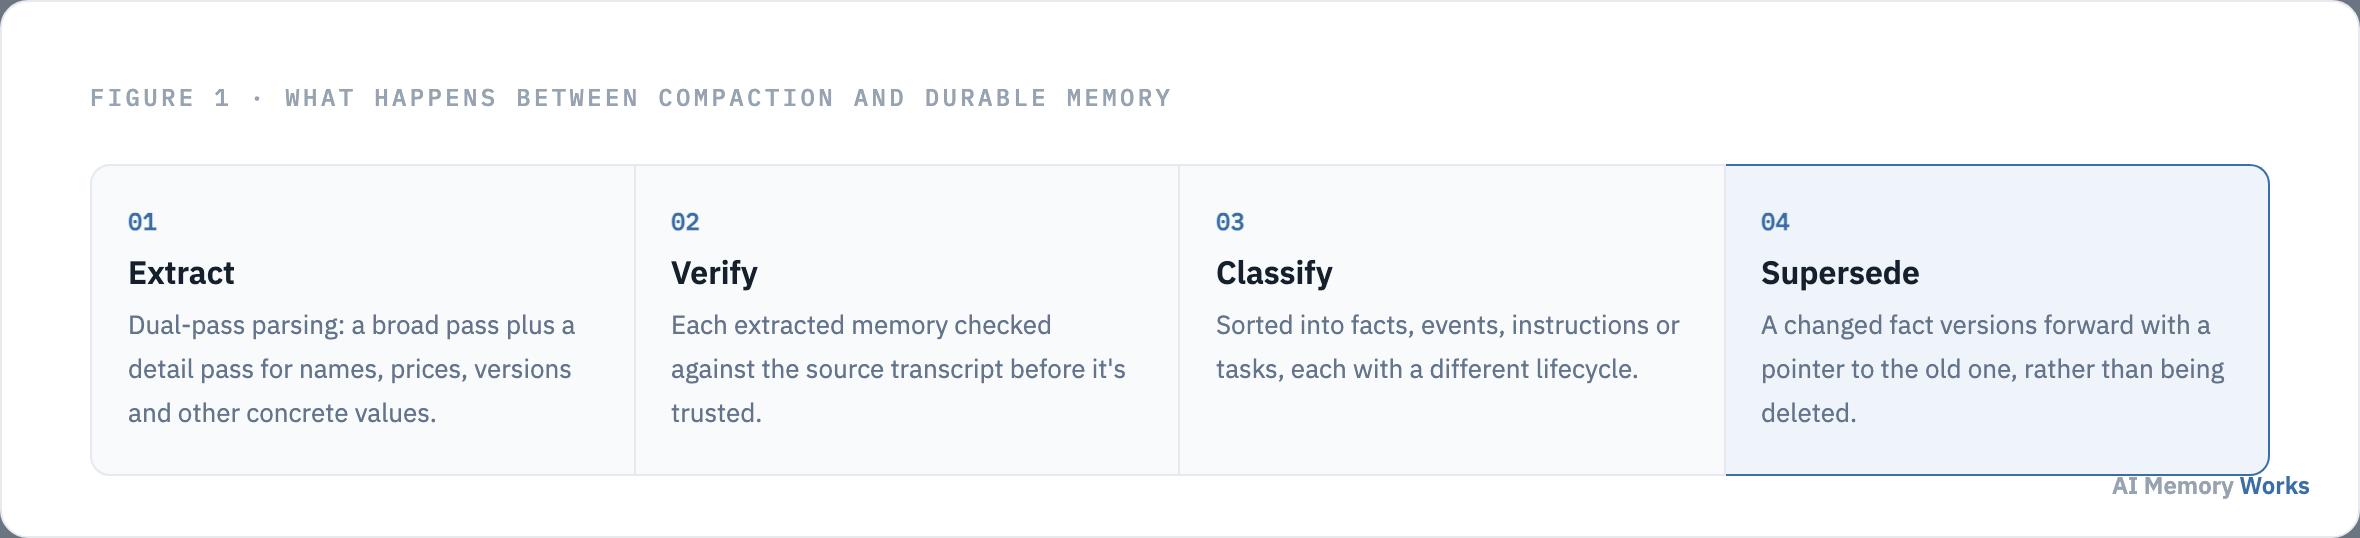
Extraction runs two passes in parallel: a broad pass that chunks the conversation and produces a structured transcript with role labels and relative dates resolved to absolutes, and, for longer conversations, a second detail pass specifically tuned to catch concrete values, names, prices, version numbers, that broad extraction tends to smooth over. Every extracted item is then verified against the source transcript before it’s trusted; Cloudflare’s own pipeline runs eight separate checks covering things like entity identity, temporal accuracy, and whether an inferred fact is actually supported by what was said, and drops or corrects anything that fails. Verified memories are classified into four types, facts (stable, atomic knowledge), events (what happened at a specific time), instructions (how to do something), and tasks (ephemeral, in-progress work), because each type has a different lifecycle and a different retrieval need.
One detail worth stating explicitly because it’s easy to skip when designing a pipeline like this: every message gets a deterministic, content-addressed ID computed from a hash of the session, the role, and the content itself, so re-ingesting the same conversation twice resolves to the same IDs rather than creating duplicates. This makes the whole ingestion step idempotent, which matters in practice because retries after a partial failure are common, and a pipeline that isn’t idempotent either silently duplicates memories or needs a separate deduplication pass bolted on afterward.
The supersession step is what separates a memory system from a plain database write. Facts and instructions get a normalized topic key, and when new information arrives under the same key, the old memory isn’t deleted, it’s superseded, with a forward pointer from old to new forming a version chain. This matters practically: a system that overwrites silently loses the ability to answer “what did we believe before,” while one that deletes loses the audit trail entirely. Versioning forward keeps both. This selective-promotion discipline, extract, verify, classify, and only then commit, echoes independent practitioner guidance making the same point from a different angle: memory should be curated on the way in, not accepted wholesale, since a system that captures everything indiscriminately ends up serving the wrong things faster, not fewer.
Ingestion decides what becomes memory. What happens when an agent later needs to find it again is a separate, equally deliberate pipeline. How does retrieval actually combine multiple signals?
Finding it again
How does retrieval actually combine multiple signals?
By running several different search methods in parallel and fusing the results with weighted ranking, because no single retrieval method performs best across every query shape. A query where the exact term is known needs different handling than one phrased as a vague, indirect question.
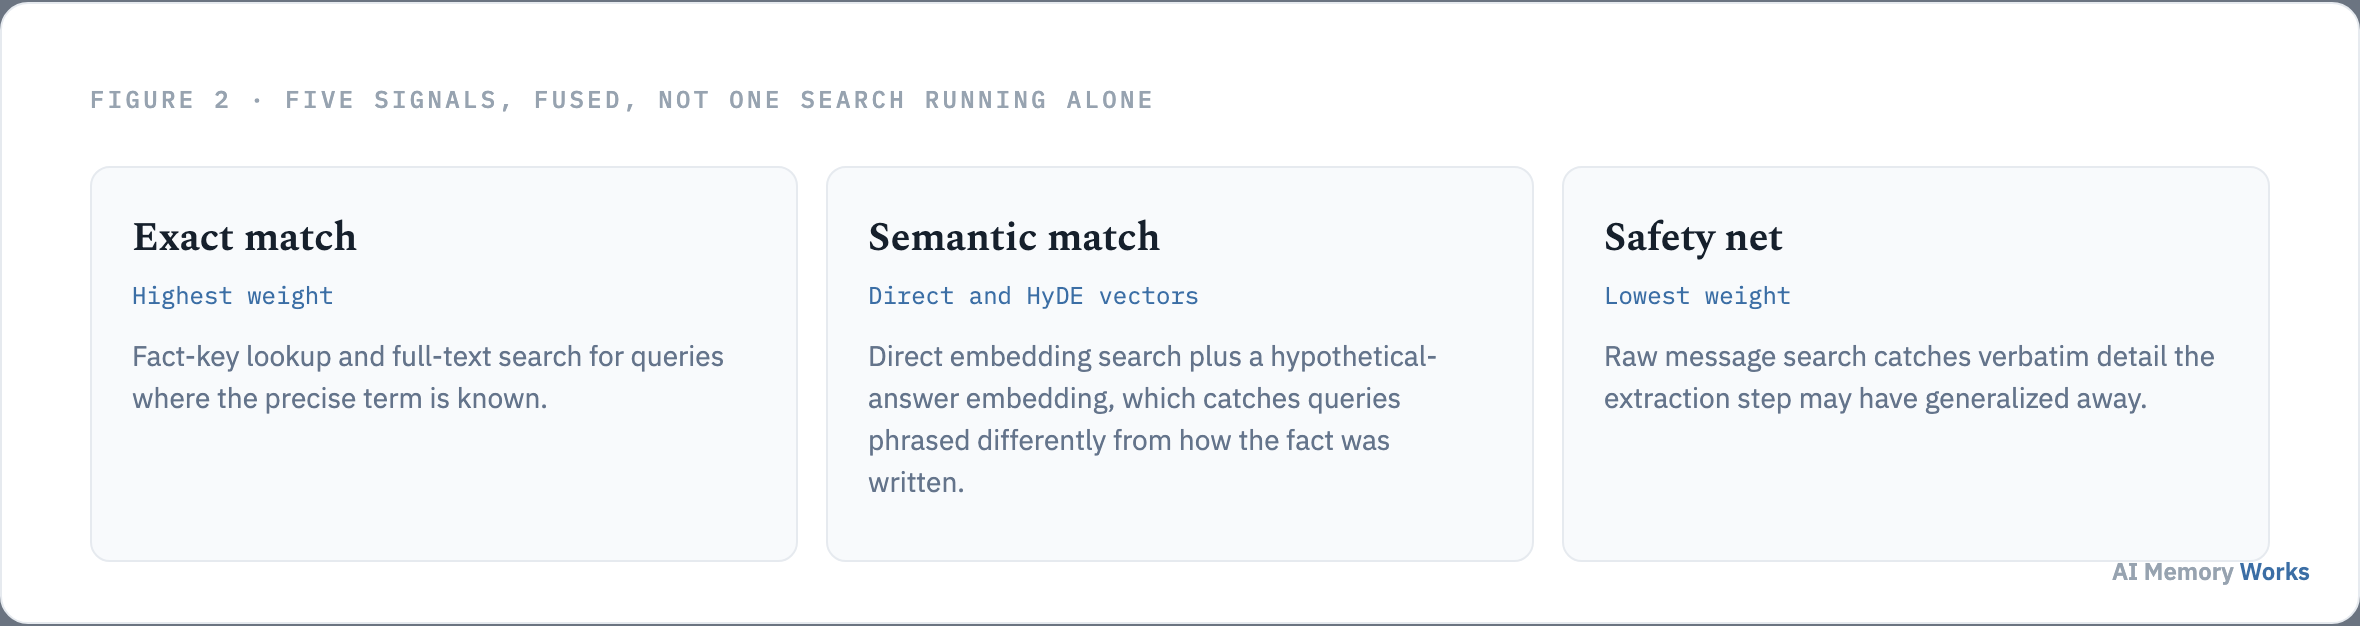
Cloudflare’s documented pipeline runs five channels concurrently: full-text search with stemming for keyword precision, exact fact-key lookup for queries that map directly to a known topic, raw message search as a safety net that catches verbatim detail the extraction step may have generalized away, direct vector search for semantic similarity, and HyDE vector search, embedding a hypothetical answer to the query rather than the query itself, which surfaces results direct embedding misses on abstract or multi-hop questions. The five results are then merged with Reciprocal Rank Fusion, a weighted scoring method where an exact fact-key match counts for more than a fuzzy semantic match, and the raw-message safety net counts least, functioning purely as a backstop. One detail worth calling out specifically: temporal computation, working out how many days passed between two dates, isn’t handled by the model at all. It’s computed deterministically with regex and arithmetic and injected into the prompt as a pre-computed fact, because, in the documented rationale, models are unreliable at date math and there’s no reason to gamble on that when a calculator-level computation solves it outright.
Retrieval architecture is only half the picture. Getting the fusion weights and the extraction quality right depended on a specific, checkable finding about which model size actually belongs at which stage. Does a bigger model make a memory pipeline more reliable?
Model sizing
Does a bigger model make a memory pipeline more reliable?
Not at every stage. A documented production finding: a smaller model outperformed a larger one at structured extraction, verification and classification, while the larger model only earned its extra cost at the final answer-synthesis step. This runs against the reflexive assumption that a bigger model is the safer default wherever it’s affordable.
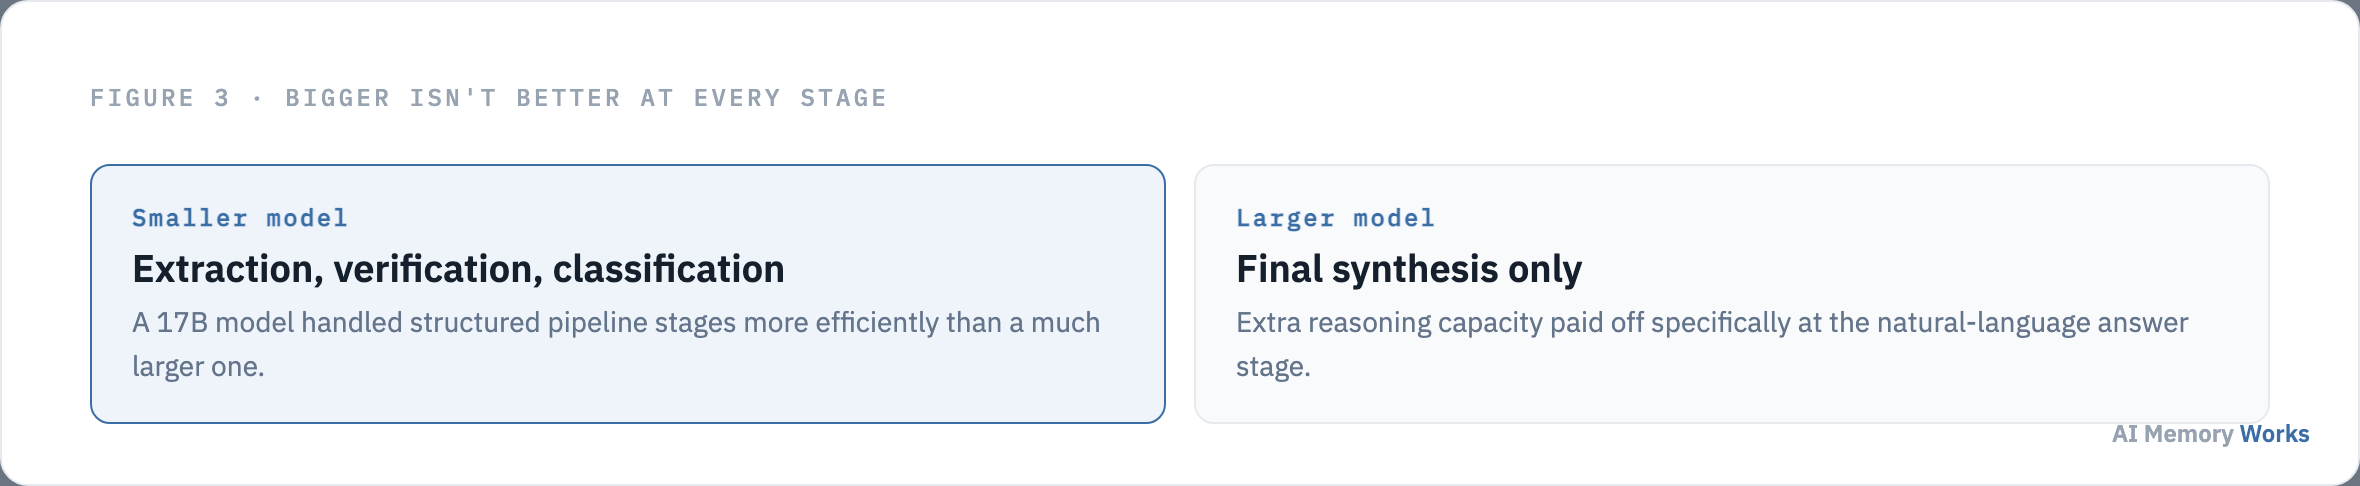
Cloudflare’s own model selection defaults to a 17-billion-parameter mixture-of-experts model, Llama 4 Scout, for extraction, verification, classification and query analysis, and reserves a much larger model, Nemotron 3 at 120 billion total parameters, specifically for the natural-language synthesis stage where the retrieved memories get turned into an actual answer. Their stated reasoning: the smaller model handles structured classification tasks efficiently, and the larger model’s additional reasoning capacity pays off specifically where genuine synthesis, not pattern matching, is required. For everything else in the pipeline, the smaller model hit a better balance of cost, quality and latency. This is a specific, attributed finding about one system’s own benchmarking, not a universal claim that small models are always sufficient, but it’s a useful data point against defaulting to the largest available model at every pipeline stage without checking whether that stage actually needs it.
Model choice decides how well each stage performs. A separate, equally important question is which system, the model or the surrounding runtime, is actually responsible for making these decisions in the first place. Who owns what: the model, or the runtime?
Division of responsibility
Who owns what: the model, or the runtime?
The model should be treated as the reasoning engine; the runtime should be the memory and state owner. That’s how a practitioner discussion on Hugging Face put it, and it’s a precise way to state a principle that shows up independently, in different words, across every source in this capture.
In practice, this means the model is never handed the job of designing its own storage strategy or managing what gets persisted. Instead, the runtime exposes a small, deliberately constrained set of tools, recall to search, remember to explicitly store something judged important, forget to mark something no longer reliable, list to see what’s currently held, and the model only ever operates through that narrow surface. The reasoning behind keeping the surface narrow is direct: a model that has to think about storage strategy on every turn is spending context and attention on a job it’s poorly suited to, when a runtime built specifically for that job can do it deterministically and reliably instead. Lifecycle concerns that follow from this split, expiry, versioning, ownership of a given memory, who has read access to it, aren’t administrative details bolted onto the side of the system; they’re core to whether retrieval stays trustworthy at all, since stale or ownerless memory degrades exactly what the runtime exists to protect.
This separation of concerns covers what to keep and how to find it again. It says less about what should happen to a memory once it stops being useful, which is a distinct decision worth getting right on its own terms. Is forgetting the same as deleting?
A deliberate distinction
Is forgetting the same as deleting?
No, and treating them as interchangeable is a design mistake. Deleting removes a memory permanently; forgetting degrades its relevance over time while keeping it intact, so it can strengthen again if it turns out to matter after all.
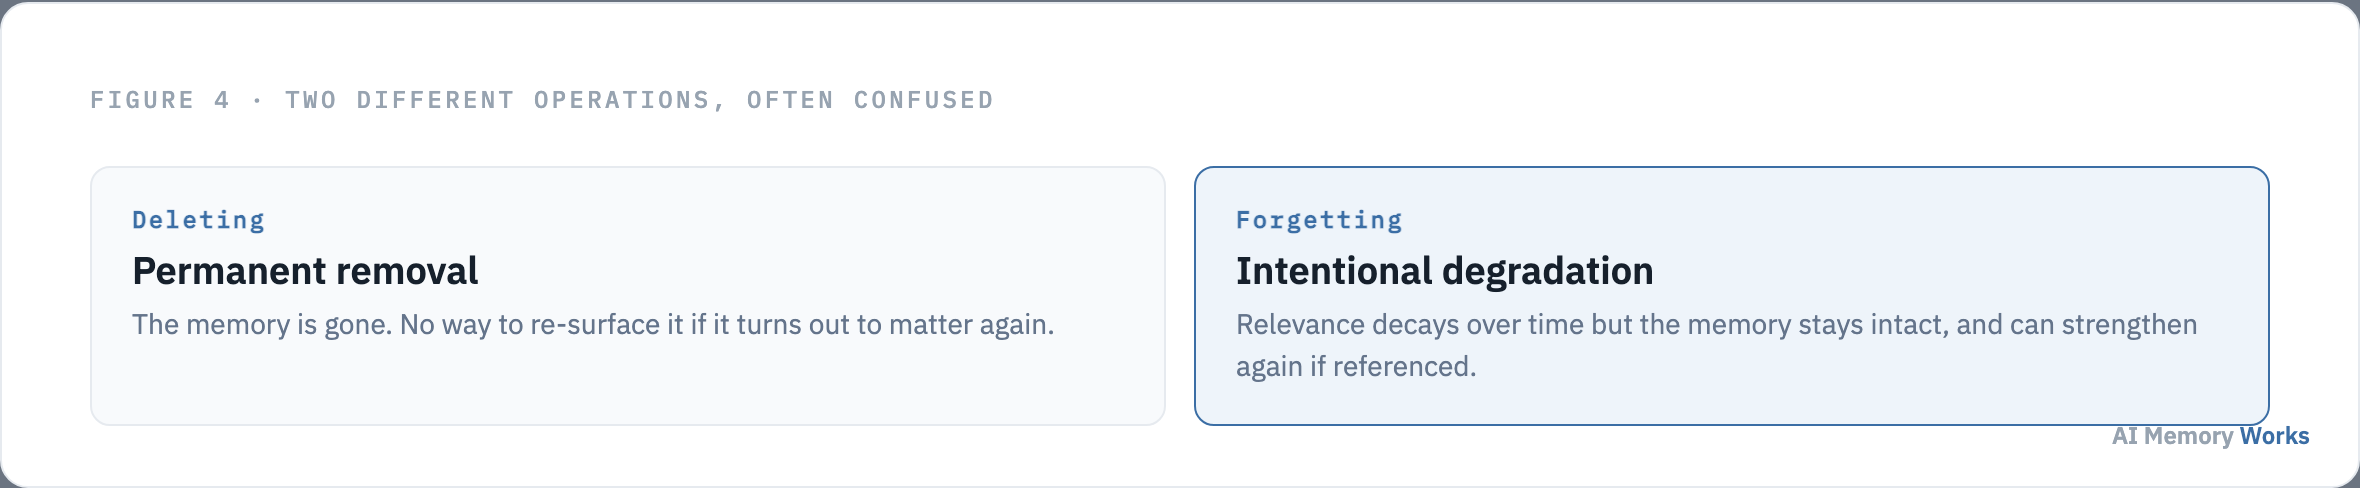
A concrete example makes the distinction obvious: a coding assistant might reduce the relevance weight of an old function-usage pattern as newer patterns supersede it, making it progressively less likely to surface during active development, without deleting the memory outright. If a developer explicitly references the old pattern again, or if the current context makes it relevant once more, its weight can strengthen back up, because the memory was never actually gone. Hard deletion forecloses that recovery entirely, which is the wrong default for information whose future relevance can’t be predicted with certainty at write time. The full mechanics of decay curves, eviction thresholds, and when hard deletion actually is the right call are covered on forgetting and eviction; this page’s job is narrower, establishing that the two operations solve different problems and shouldn’t be reached for interchangeably.
Getting decisions like this right, rather than guessing at model size or fusion weights, came from treating the pipeline as something to be measured, not assumed. Cloudflare’s own account of the research and iteration behind the product describes a repeating loop: run benchmarks, analyze specifically where the gaps were, propose a change, have a human review the proposal to filter out fixes that would only overfit the benchmark rather than generalize, then implement and repeat. One recurring difficulty in that loop is worth flagging for any team running something similar: language models are stochastic even at temperature zero, so a single benchmark run isn’t a reliable signal on its own, and results have to be averaged across multiple runs, with trend direction weighed alongside the raw score, to tell whether a change actually helped or was noise.
Every pipeline stage described so far is a design decision on paper. What it actually looks like running inside a real product, with real internal usage, is worth seeing directly. What does this actually look like running in production?
In production
What does this actually look like running in production?
Two internal, attributed examples from the same team that built the pipeline described above: a coding-agent plugin where shared team memory means the agent stops asking questions a teammate already answered, and a code-review agent that gets quieter over time because it remembers which flagged patterns were already dismissed for good reason.
In the coding-agent case, memory persists both within a session and across sessions, but the more distinctive benefit came from a shared profile across a team: the agent has access to what other team members have already established, so it stops re-asking settled questions and stops repeating mistakes someone else already corrected. In the code-review case, the described benefit isn’t that the reviewer got smarter in the sense of catching more issues, it’s that it learned to stay quiet: it remembers that a specific comment wasn’t relevant in a prior review, or that a flagged pattern was deliberately kept for a documented reason, and stops re-raising it. A third internal example, an always-on chat bot that ingests message history and lurks in the background, remembering new messages as they arrive so it can later answer a question based on a conversation it wasn’t directly asked about at the time, shows the same underlying pipeline applied to a passive rather than an actively-queried use case. Each example describes an internal engineering team’s own stated usage of a system it built, not an independently verified benchmark, and is presented here on that basis.
One infrastructure choice behind these examples is worth naming because it addresses a concern every multi-tenant memory system eventually has to solve: isolation between separate memory contexts. Each memory profile in the documented system runs on its own isolated compute and storage instance, so one tenant’s memories are never reachable from a different tenant’s queries by construction, rather than by a filter that has to be applied correctly on every read. Whatever the underlying infrastructure, this is the property to check for before trusting any shared memory system with data from more than one team, customer, or user.
Every stage covered on this page, extraction, verification, classification, fusion-based retrieval, forgetting versus deleting, is available as a managed pipeline rather than something a team has to build and operate itself. Engram is one option that handles this lifecycle as a service, which is worth weighing directly against building the ingestion and retrieval pipeline described above from scratch, particularly for a team without the internal capacity to run the kind of benchmarking loop that produced findings like the model-sizing result above. The broader question of which storage tiers and technologies this runtime lifecycle should operate across is covered on memory hierarchy, and the mechanics of how retrieved candidates actually get ranked is covered in depth on memory scoring.
Video
Principles, patterns and best practices, in one talk
A deeper walkthrough from Richmond Alake of MongoDB, covering the same territory from a slightly different angle.
FAQ
Frequently asked questions
The practical questions that follow once the runtime lifecycle above is understood.
Should the model decide what gets stored as memory?
No. The runtime should own that decision, exposing only a small set of tools (recall, remember, forget, list) the model can call. Letting the model design its own storage strategy spends context and attention on a job a deterministic runtime handles more reliably.
Is deleting a memory the same as letting an agent forget it?
No. Deletion is permanent and forecloses any future recovery. Forgetting, done deliberately, degrades a memory's relevance over time while keeping it intact, so it can strengthen again if it turns out to matter later.
Why classify memories into separate types instead of one flat store?
Facts, events, instructions and tasks have different lifecycles. A stable fact should supersede its prior version rather than being deleted; a task is ephemeral by design. Treating all memory as one undifferentiated type makes correct lifecycle handling impossible.
Does a bigger model always improve a memory pipeline's accuracy?
Not at every stage. One documented production system found a smaller model handled structured extraction, verification and classification more efficiently than a larger one, and reserved the larger model specifically for final answer synthesis, where its extra reasoning capacity actually paid off.
Why fuse multiple retrieval methods instead of using vector search alone?
Because no single method performs best across every query shape. An exact fact lookup, a semantic vector match, and a raw-text safety net each catch different failure modes; fusing them with weighted ranking outperforms relying on any one signal alone.
Should temporal reasoning like date math be handled by the LLM?
No. One documented pipeline computes temporal facts like elapsed days deterministically with regex and arithmetic rather than asking the model, specifically because models are unreliable at date math and a calculator-level computation solves it exactly.