Fundamentals · Limits
The Context Window Problem: Why Bigger Isn’t Enough
Longer context windows still hit hard limits: cost scales quadratically with every token, attention degrades over distance (context rot), and nothing persists across sessions unless you add AI memory.
Bigger window
More tokens, higher cost, still session-bound
+ Memory layer
Selective recall, cross-session, lower cost
Definition
What is the context window, and what’s its hard limit?
Maximum tokens per inference: system prompt plus history plus tools plus user message, volatile across sessions.
Before text ever reaches a context window, it’s tokenized, usually via byte-pair encoding, which breaks text into subword units; a rough rule of thumb is that one token represents about 4 characters or three-quarters of a word, though this varies by language and tokenizer. Context windows have expanded roughly 2 orders of magnitude since the original transformer architecture, from a few thousand tokens in early models to the millions available today, according to Redis’s own engineering research.
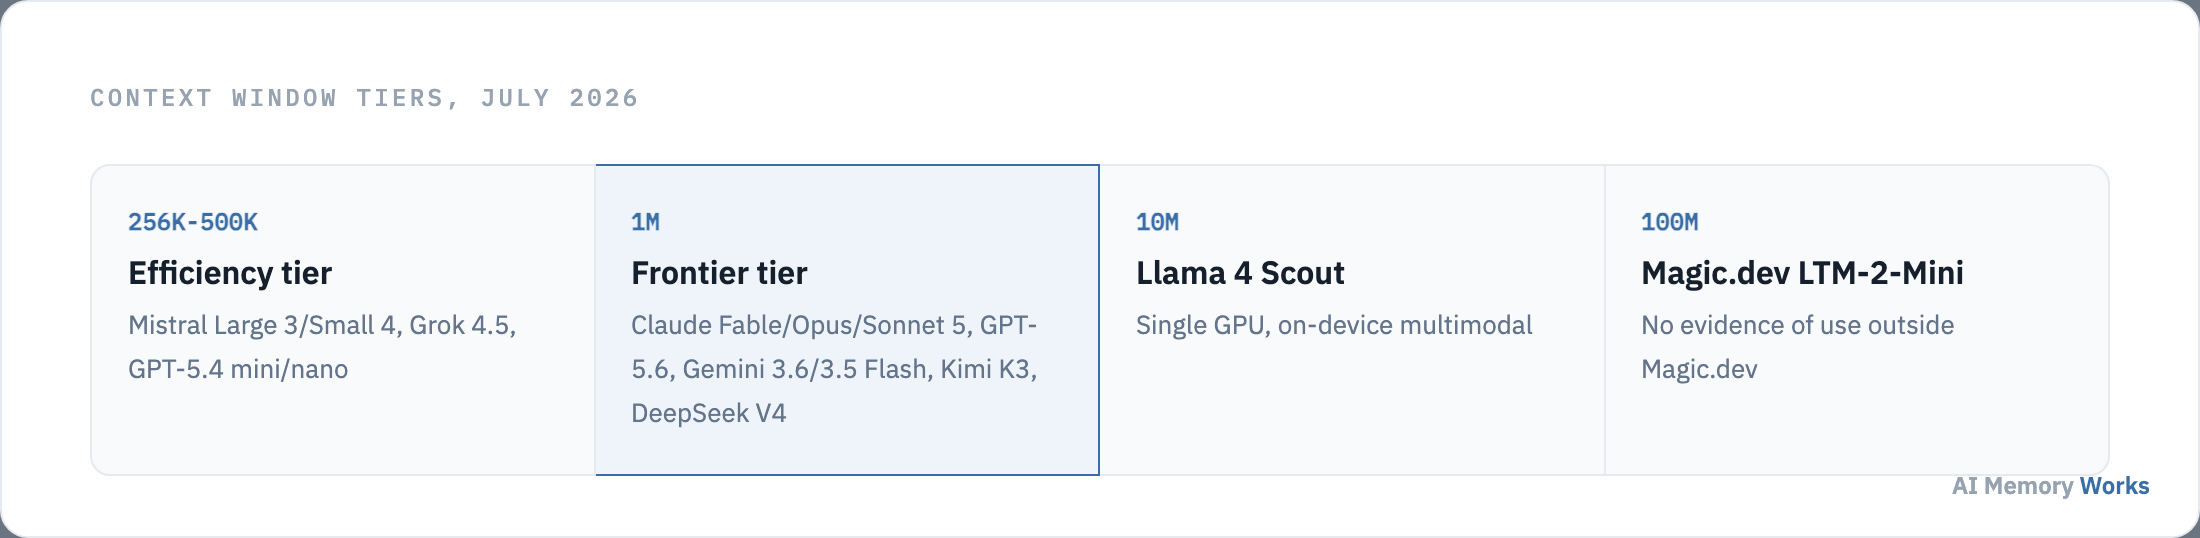
As of July 2026, the current frontier sits at 1 million tokens across most major vendors (Claude Fable 5, Claude Opus 5, Claude Sonnet 5, OpenAI’s GPT-5.6 family, Google’s Gemini 3.6 and 3.5 Flash, Moonshot’s Kimi K3, DeepSeek V4, and Meta’s Llama 4 Maverick), with Meta’s Llama 4 Scout reaching 10 million tokens on a single GPU and Magic.dev’s LTM-2-Mini publishing 100 million, though Codingscape’s own July 2026 roundup notes plainly that “we still haven’t seen evidence anyone outside of Magic.dev is using this model or its 100 million token context.” Everything in the window exists only for that inference call. A new session starts blank unless you resend the entire history.
Problems
What are the three problems with relying on context alone?
Cost, accuracy and persistence each break down before a large context window ever fills up.
| Problem | What happens | Evidence |
|---|---|---|
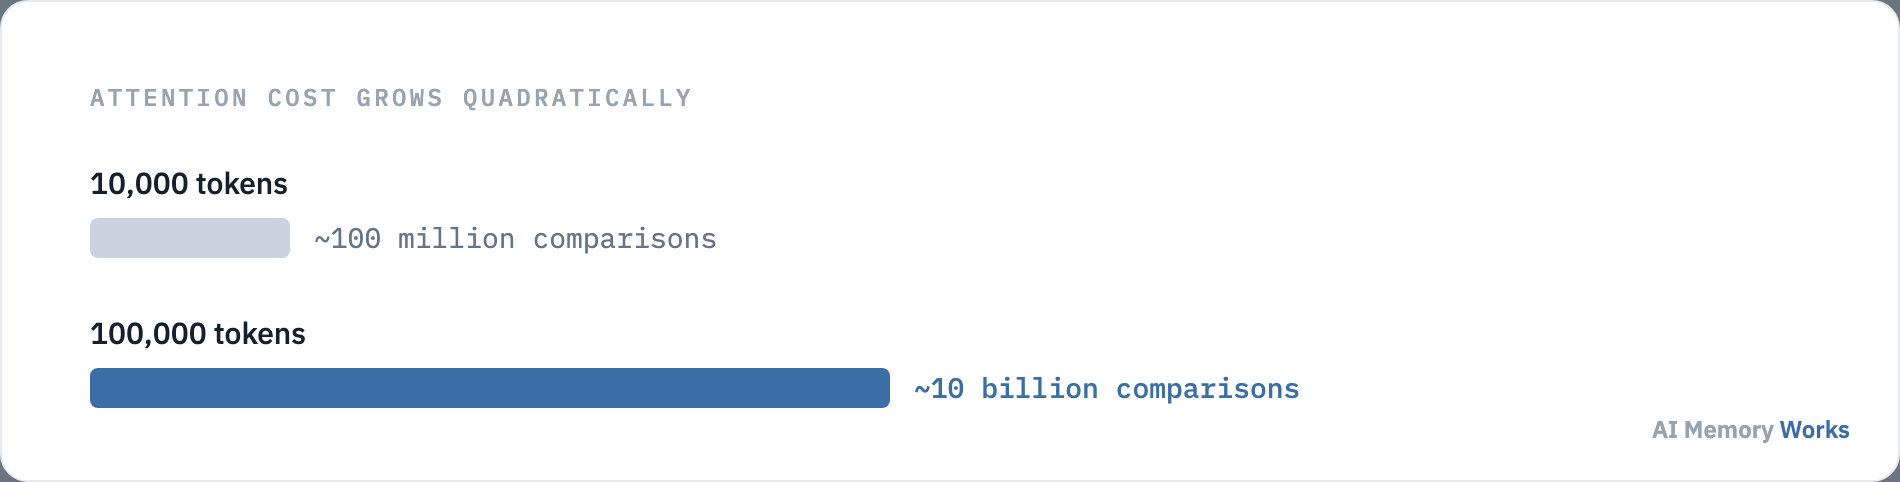
| Cost | Attention cost grows quadratically with every token | 10K tokens = 100 million attention comparisons; 100K tokens = 10 billion (Redis engineering research) |
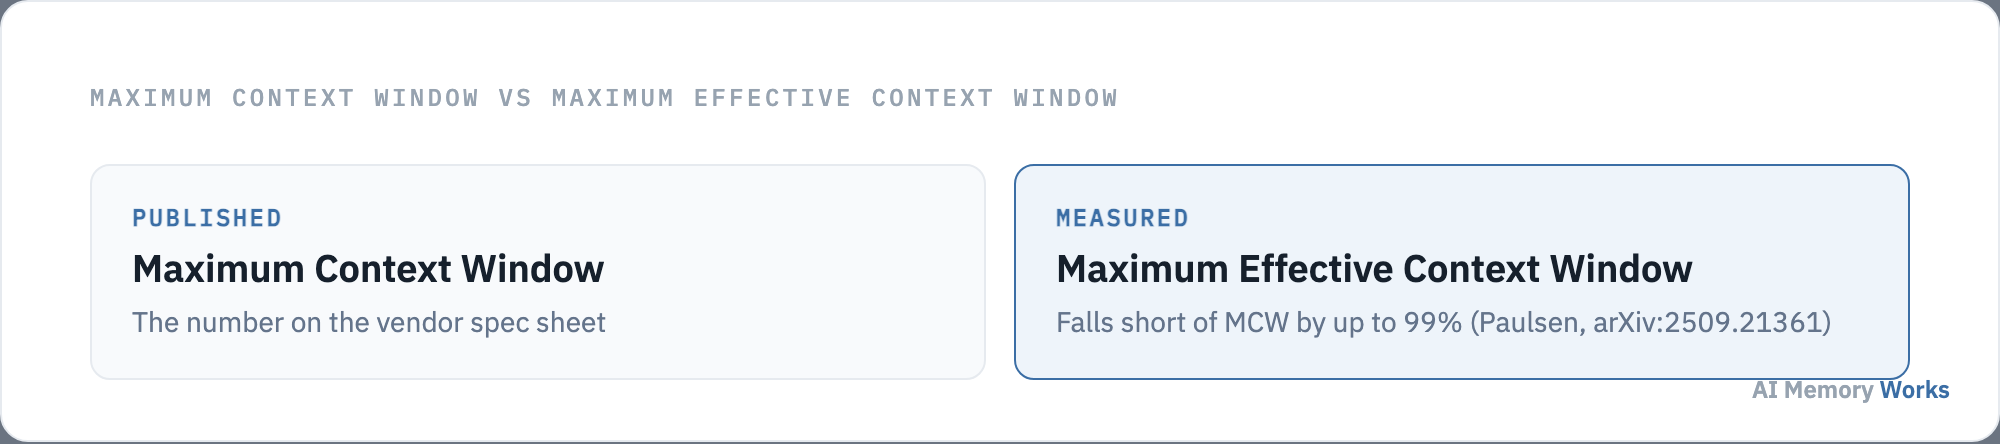
| Context rot | Accuracy drops well before the window fills | Models fall short of their own stated maximum by up to 99% (Paulsen, arXiv:2509.21361) |
| No persistence | New session = blank slate | Requires external memory for LTM |
The math
Why does cost scale quadratically with context?
Every token has to be compared against every other token, so doubling the context quadruples the work.
Transformer self-attention is O(n²): a 10,000-token context needs roughly 100 million pairwise comparisons, and a 100,000-token context needs roughly 10 billion, according to Redis’s own engineering research. That quadratic growth, not a vendor pricing decision, is why inference visibly slows down as a conversation lengthens, and why a chatbot that felt fast at the start of a session gets sluggish by the end: the key-value cache that holds every prior token’s representation keeps growing, and eventually GPU memory bandwidth, not raw compute, becomes the bottleneck. Two mitigations are in production use today: FlashAttention, which achieves a 2 to 4x speedup by changing how GPUs access memory rather than reducing the math itself, and sparse attention, which can prune 90 to 99% of attention links by replacing full token-to-token comparison with sliding windows, global tokens and random connections. Neither eliminates the underlying quadratic cost; both push the point where it becomes painful further out.
KV cache quantization is a third lever, and a blunter one: switching the cache from 16-bit to 8-bit or 4-bit precision cuts its memory footprint by roughly 50%, which matters because moving data between a GPU’s fast on-chip memory and its slower main memory, not the attention math itself, typically consumes 70 to 90% of total inference time on long contexts. This is also why large context windows don’t scale for free even on capable hardware: a roughly 14-billion-parameter model running a long context can exhaust the VRAM on a 12GB GPU even with aggressive quantization applied, which is why practical context length in production is often far below whatever the model’s theoretical maximum happens to be.
Context rot
What is context rot, and how bad is it?
Needle-in-haystack failures and attention dilution: a million-token window doesn’t guarantee million-token understanding.
A 2025-2026 study (Paulsen, arXiv:2509.21361) tested this directly rather than trusting vendor specs, defining a “Maximum Effective Context Window” (MECW) distinct from the “Maximum Context Window” (MCW) vendors publish, and measuring the gap across hundreds of thousands of data points on several models. The result: every model tested fell short of its own stated MCW, by as much as 99% in the worst cases; a few top-of-the-line models failed with as little as 100 tokens in context on certain problem types, and most showed severe accuracy degradation by 1,000 tokens. Redis’s own engineering research names a specific, more commonly-cited threshold in the same direction: most long-context models show sharp performance drops past 32,000 tokens, the well-documented “lost-in-the-middle” effect, and even top performers lose significant accuracy at longer contexts than that. Both findings say the same thing from different angles: the number on a model’s spec sheet is not the number that matters for your actual task.
Part of why this gap exists is architectural rather than purely a training issue. Rotary Position Embedding, the mechanism most modern models use to track a token’s position in the sequence, works by applying rotations to a token’s representation based on where it sits, but Redis’s own engineering research notes it “still has severe limitations preventing them from dealing with a context of millions of tokens” without additional extension techniques layered on top. Models also simply fail on positions they never saw during training: a model trained mostly on documents under 50,000 tokens has no guarantee of behaving sensibly at token 800,000, regardless of what its architecture technically permits.
Trade-offs
How do large and small context windows actually compare?
A larger window trades accuracy, latency and headroom for reach; a smaller one trades reach for consistency.
| Dimension | Large windows (128K to 2M+) | Small windows (under 32K) |
|---|---|---|
| Accuracy | Degrades around 32K tokens for most long-context models; the lost-in-the-middle effect is well documented | Consistent attention; reliable on focused tasks |
| Cost | Priced from fractions of a dollar to several dollars per million input tokens; prompt caching can cut costs on cached tokens by up to 75% | Lower per-token cost; minimal overhead |
| Latency | Can drop to single-digit tokens per second once a context no longer fits fully in GPU memory | 50 to 100 tokens per second in-memory; faster inference |
| Memory | A roughly 14B-parameter model at long context can exhaust a 12GB GPU’s VRAM even with aggressive quantization | Minimal overhead; edge deployment capable |
Redis’s own engineering research is blunt about the practical upshot: don’t trust the spec sheet, benchmark your actual use case at your target context length, since even top performers lose meaningful accuracy well before their advertised ceiling.
Solution
Why does memory solve what context cannot?
Selective retrieval, a cross-session store, update and forget, and lower per-turn tokens, benchmarked on LOCOMO and LongMemEval.
- Retrieve only top-k relevant facts each turn
- Persist across sessions in an external store
- Update and forget facts without retraining
- Mem0 LOCOMO J 66.9; Zep LongMemEval +18.5% vs baseline
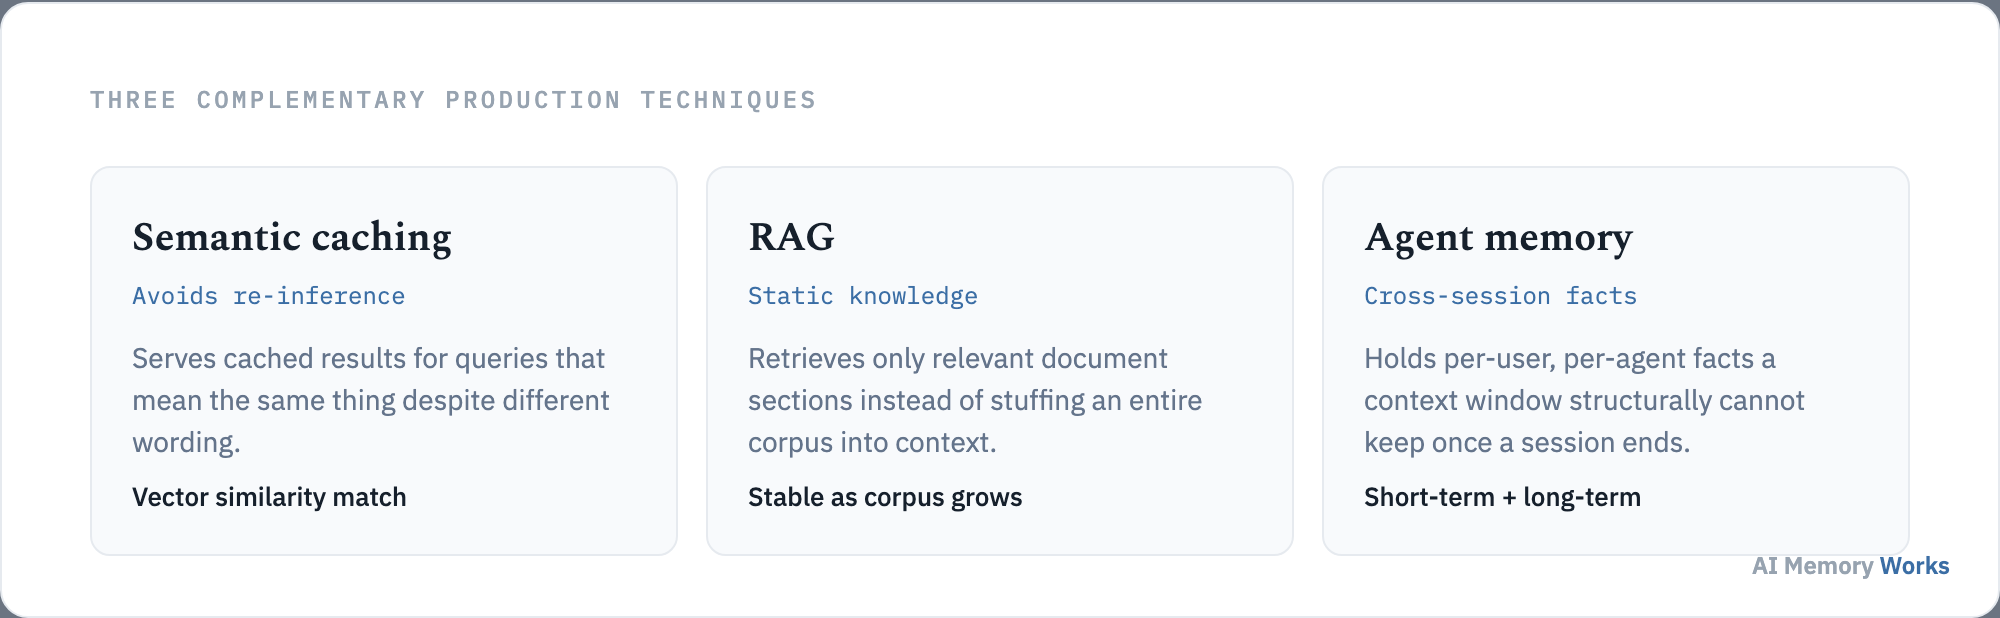
Redis’s own engineering research frames the production answer as 3 complementary techniques rather than a single fix: semantic caching to avoid re-running inference on queries that mean the same thing, retrieval-augmented generation to pull only relevant document sections instead of stuffing an entire corpus into context, and agent memory systems for the cross-session, per-user facts a context window structurally cannot hold once the session ends. Most production systems combine all 3 rather than picking one.
When context wins
When is a large context window still the right tool?
Single-session depth beats retrieval when the whole document, codebase or trace needs to be reasoned over at once.
Codingscape’s own July 2026 research names several cases where the jump to a 1-million-token window has real practical impact rather than diminishing returns: multi-repo codebase analysis, where loading an entire repository plus its documentation and test files avoids losing cross-file dependencies to chunking; long-horizon agentic workflows, where holding every tool call, observation and reasoning step in a single trace eliminates the compaction that used to cause agents to lose the plot mid-task; comprehensive document analysis, where a legal, financial or research corpus stays fully in context instead of being split across a sliding window; multimodal processing, where a single request can reason across text, images, video and audio together rather than through separate pipelines; and enterprise knowledge management, where an entire internal document set, policy library or case archive loads directly rather than depending on a retrieval pipeline to guess which fragments matter. None of these need cross-session memory, since the task starts and ends inside one session; that’s precisely the boundary where a large context window is the right tool and memory would be solving a problem that doesn’t exist yet.
When a large window is not the right fit for the budget, 3 concrete adjustments help before reaching for a bigger model: sizing the context window to the actual input rather than always requesting the maximum available, applying sparse or pruned attention to limit computation to the most relevant tokens, and batching shorter inputs together when the full window isn’t needed for every request. Don’t abandon long context. Use it for the current session’s working set while memory handles persistence and selective recall across sessions.
FAQ
Frequently asked questions
The real limits, the current model tiers, and when a large context window is still the right call.
What are max context tokens in 2026?
1 million tokens is the current frontier tier (Claude Fable 5, Claude Opus 5, Claude Sonnet 5, GPT-5.6 family, Gemini 3.6/3.5 Flash, Kimi K3, DeepSeek V4, Llama 4 Maverick), with Llama 4 Scout reaching 10 million on a single GPU. Caps apply per inference call; nothing persists across sessions without external memory.
Is context rot a real problem?
Yes. A 2025-2026 study (Paulsen, arXiv:2509.21361) found models fall short of their own stated maximum context window by as much as 99%, with some failing at just 100 tokens on certain problem types. See context rot.
Is a 1-million-token context window enough?
For single-session depth, often yes. For cross-session personalization and cost control at scale, pair with external memory (Engram, Mem0, Zep).
Is memory cheaper than a large context window?
Usually yes at scale. Mem0 uses ~1,800 vs ~26,000 tokens per query; p95 latency 1.44s vs 17.1s full-context (Chhikara et al., 2025).
Why does a bigger context window cost so much more?
Self-attention is O(n squared): a 10,000-token context needs roughly 100 million comparisons, a 100,000-token context needs roughly 10 billion. Doubling the window roughly quadruples the work.
Does summarization fix context rot?
Helps but can lose facts. Best pattern: summarize plus selective memory retrieval. See memory summarization.
RAG vs a bigger context window?
Different layers. RAG retrieves static docs; memory stores per-user facts. Both beat stuffing everything into context. See memory vs RAG.
Best production pattern for context limits?
Memory retrieves top-k facts, recent messages fill the remaining budget, context engineering allocates tokens. Redis's own engineering research frames this as 3 complementary techniques: semantic caching, RAG, and agent memory.
Is a 100-million-token context window actually usable?
Magic.dev's LTM-2-Mini publishes 100 million tokens, but Codingscape's own July 2026 research states plainly that no evidence exists of anyone outside Magic.dev using it. The 1-million-token tier is where most real production traffic runs.
Why can't models use their full stated context window?
Rotary Position Embedding, the mechanism most models use to track token position, has documented limitations at multi-million-token scale without extension techniques. Models also fail on positions they never saw during training, regardless of what the architecture technically permits.
How many tokens is a word, roughly?
About 0.75 words per token, or roughly 4 characters, for English text using byte-pair encoding. This varies by language and tokenizer, so treat it as a rule of thumb rather than an exact conversion.