Infrastructure · Embeddings
Embeddings for AI Agent Memory
Choosing an embedding model for a memory store is a different decision from choosing one for document retrieval, and almost everything written about it assumes the second case. The text is shorter, the query is not what the user typed, the data is personal, and the choice is close to permanent because changing it means re-embedding every user’s history. This page covers what changes, not what an embedding is.
Three decisions
The input
What do you actually embed in a memory system?
Short extracted statements, not passages of a document. That one difference drives most of this page, because every guide to choosing an embedding model is written for a corpus of chunked documents and quietly assumes the shape of that input.
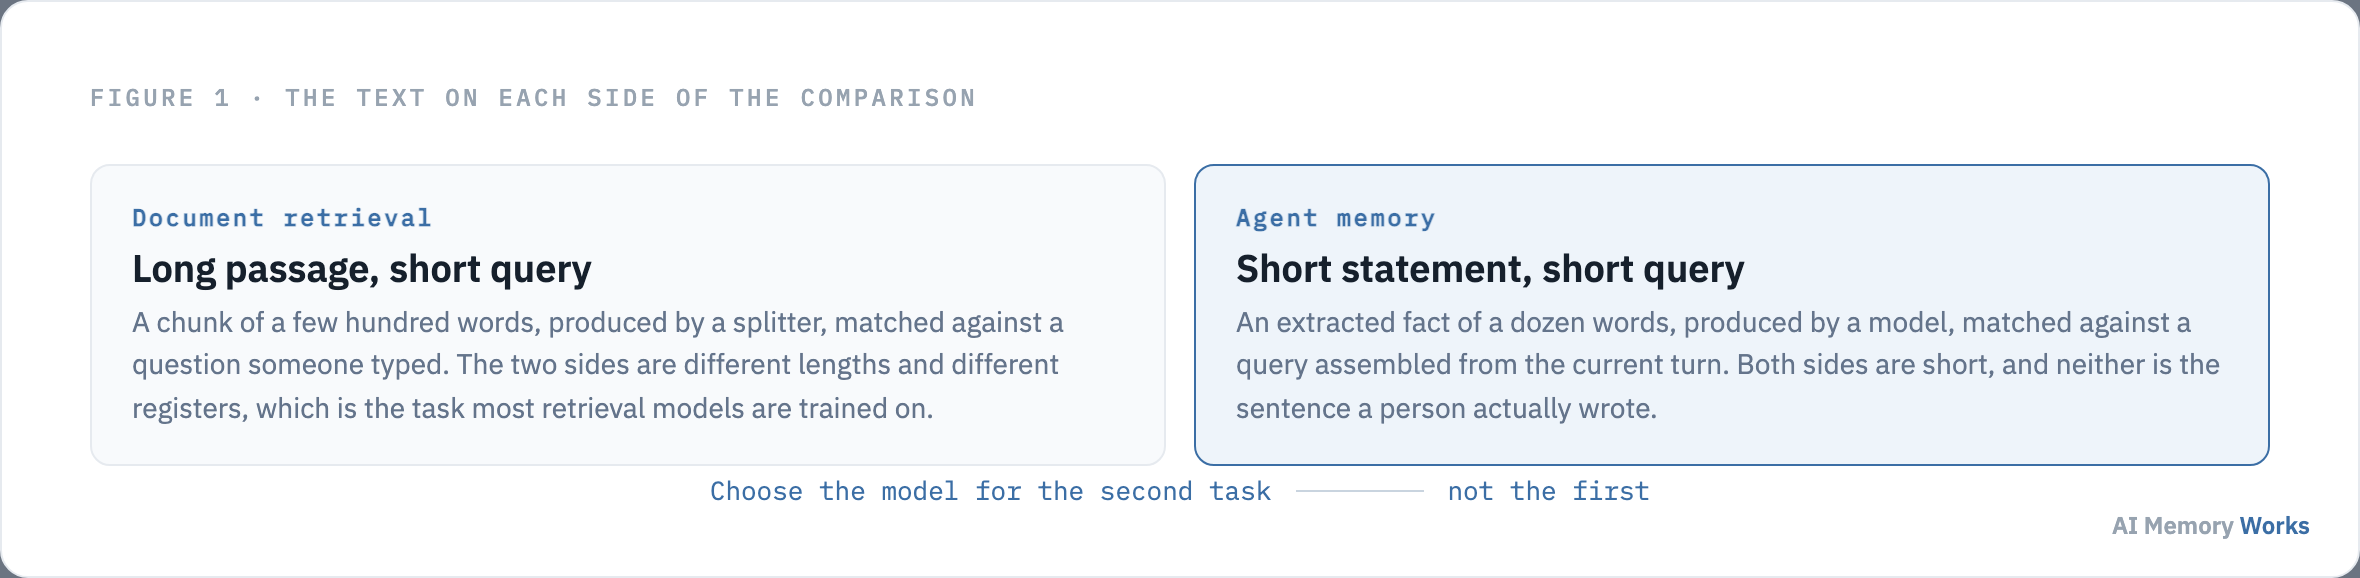
A document pipeline splits a file into windows of a few hundred words and embeds each one. The text is whatever the splitter produced, its length is roughly constant, and its style is whatever the source document had. A memory pipeline extracts a statement, which might be a dozen words, and embeds that. The record is not a fragment of anything; it is a complete assertion about a person. How it gets produced is covered on writing memories.
There is a second, subtler consequence. In document retrieval the query is a sentence a human typed. In memory the query is usually constructed by the system, from the current turn plus whatever framing the retrieval step adds, so neither side of the comparison is text a person wrote in the form the model sees it. Both sides have been through a transformation you control, which is unusual and useful: you can change either one.
The granularity decision is therefore not chunk size. It is how much context an extracted statement should carry with it. A record reading “prefers window seats” retrieves cleanly for travel questions and loses the fact that it applied only to long-haul flights. A record carrying its condition is longer, slightly noisier to match, and correct. Prefer the correct one; retrieval can be tuned and a lost qualifier cannot be recovered.
The shape of that input has a direct effect on which model performs well: why do models tuned on documents underperform on memories?
Task mismatch
Why do models tuned on documents underperform on memories?
Because retrieval models are trained on an asymmetric task and memory is a symmetric one. Asymmetric means a short query on one side and a long passage on the other, which is the standard retrieval setup and what most published training and evaluation targets.
Memory inverts half of it. The stored text is short and the query is short, so the comparison is between two texts of similar length and similar register. Some models handle both cases well, some are noticeably better at one, and several publish separate instructions or prefixes for query text and document text precisely because the two roles are not interchangeable. A model that expects a passage on one side is being asked to do something it was not tuned for.
The practical symptom is a store where similarity scores cluster tightly. If every candidate comes back between 0.80 and 0.88, the model is not separating the memories from each other, and every downstream mechanism suffers: thresholds become arbitrary, weighting relevance against other signals becomes noise, and memory scoring is left ranking on differences that are not real.
Two adjustments are cheap and worth trying before changing model. If the model supports query and document prefixes, apply them correctly, with the memory as the document side and the constructed query as the query side; getting these backwards is a common and silent error. And if scores stay compressed, lengthen the stored record slightly by including its context, since a fuller statement gives the model more to separate on.
The obvious next move is to consult a leaderboard and pick a better model, which is where most selection advice ends and where it goes wrong: does the leaderboard tell you which model to use?
Public rankings
Does the leaderboard tell you which model to use?
It tells you which models are worth testing, and nothing more. Public embedding benchmarks rank models on document-shaped tasks with document-shaped queries, which is the task described above as the one your system does not run.
They are still useful as a filter. A model far down the table is unlikely to surprise you, and the leaderboards are a reasonable way to assemble a shortlist of three or four candidates that clear a basic quality bar, cover your languages, and come in a dimension you can live with. Treating that shortlist as a ranking is where the reasoning breaks.
There is a second reason for caution that applies to every public benchmark: the top of these tables moves constantly, and a page naming the current leader is wrong within months. That is why this page names no models. The criteria below outlast the rankings.
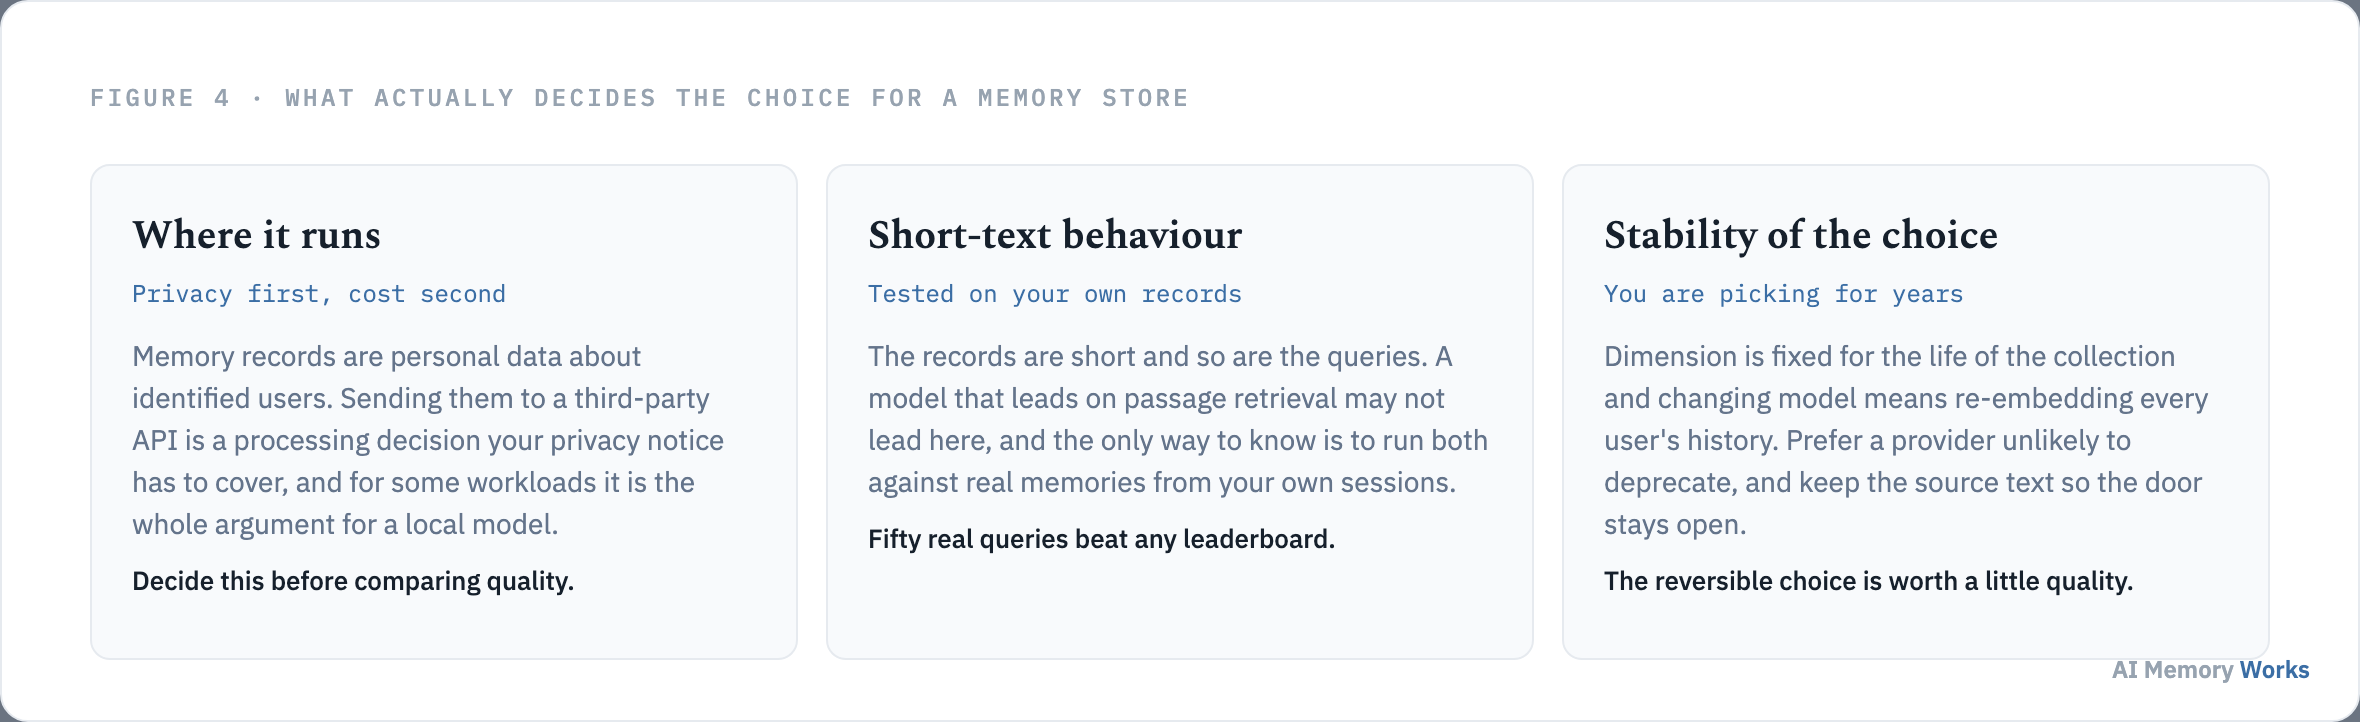
Notice what the three criteria have in common. Each is a property of your situation rather than of the model, which is why no external ranking can settle any of them, and why the decision has to end with a measurement of your own: how do you build a test set from your own memories?
Ground truth
How do you build a test set from your own memories?
Collect real queries, name the memory that should have won each one, and score the candidates on that. Fifty pairs is enough to separate three models, and it is more informative than any published table because the failures in it are yours.
Getting the queries is the easy part if the read path is logged: take real turns that triggered a retrieval, weighted toward the ones users complained about. Naming the correct memory is manual and is the reason this step gets skipped, but fifty judgements is an afternoon, and it is a fixed cost that keeps paying every time you change anything about retrieval.
Score on rank rather than on similarity value. What matters is whether the right memory appears above the wrong ones, not whether its score was 0.86 or 0.91, and similarity values are not comparable between models anyway. A simple measure works: for each query, the position of the correct memory in the candidate list, averaged across the set.
Include the hard cases deliberately. Two memories that contradict each other, where the current one must rank above the superseded one. A query that no stored memory answers, where the correct behaviour is for nothing to clear the threshold. A memory phrased in completely different words from the query. Those three cover most real failures, and a model that handles them is a model that will hold up. The wider method is on evaluating agent memory.
The same test set answers the next question, which is otherwise decided by guesswork: how many dimensions does a memory store need?
Dimension
How many dimensions does a memory store need?
Fewer than a document corpus, in most cases, because the records are short and the collections are small. The usual framing is accuracy against storage and latency. For memory the storage side is often negligible and the real argument is elsewhere.
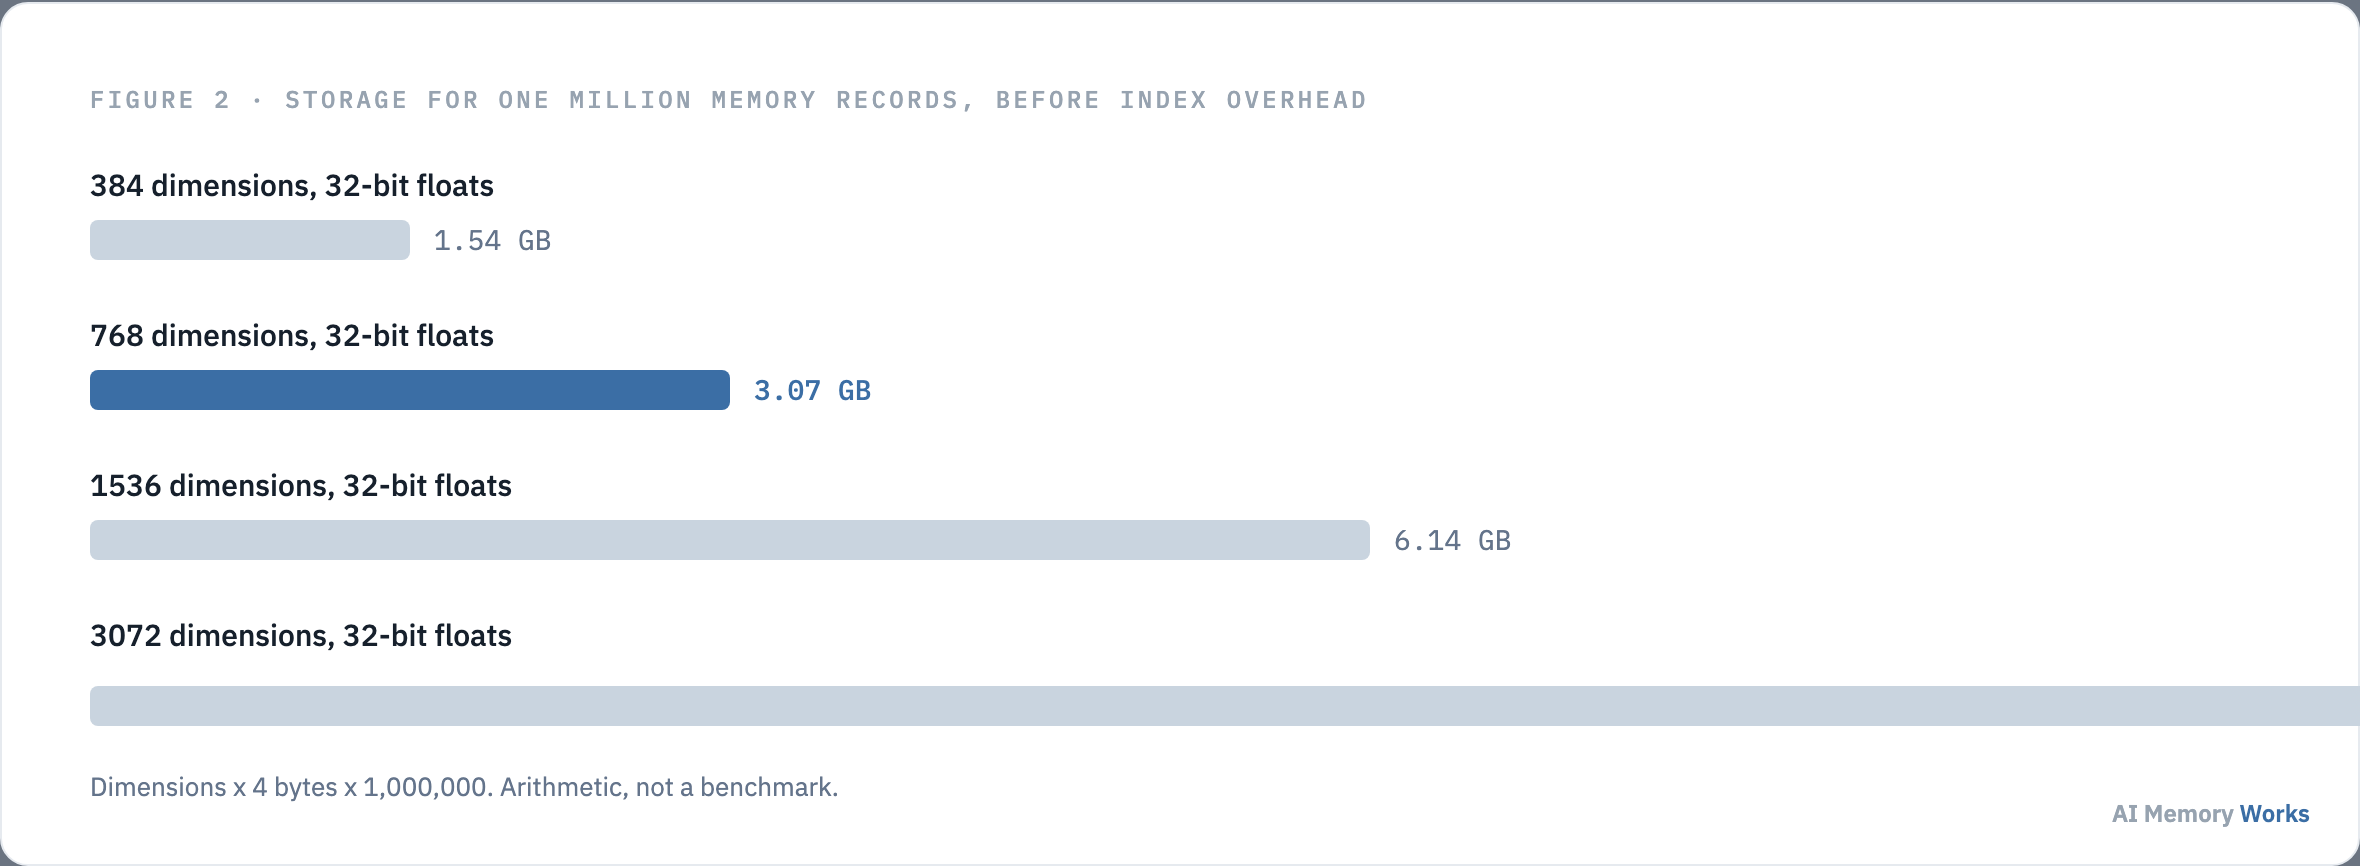
Run the multiplication for your own scale before treating dimension as a cost decision. A product with ten thousand users holding two hundred memories each has two million vectors. At 768 dimensions that is around six gigabytes of raw vector data, which is not a number that should drive an architecture. At a thousand times that scale it is, which is the point at which the compressed index families on vector databases start to matter.
Higher dimensions do carry more information, and on hard document-retrieval tasks that shows up as better accuracy. On short symmetric texts the gain is smaller, because there is less in a twelve-word statement to represent. Some models support truncating their output to a shorter dimension with a modest quality loss, which is worth testing on your own set rather than assumed either way.
The decisive fact is different from any of this. Dimension is fixed for the life of the collection, because vectors of different sizes cannot be compared or stored in one index. Whatever is chosen on the first day is what the store runs on until somebody performs a migration, which makes it worth understanding what that migration involves: what does changing the embedding model later cost you?
The one-way door
What does changing the embedding model later cost you?
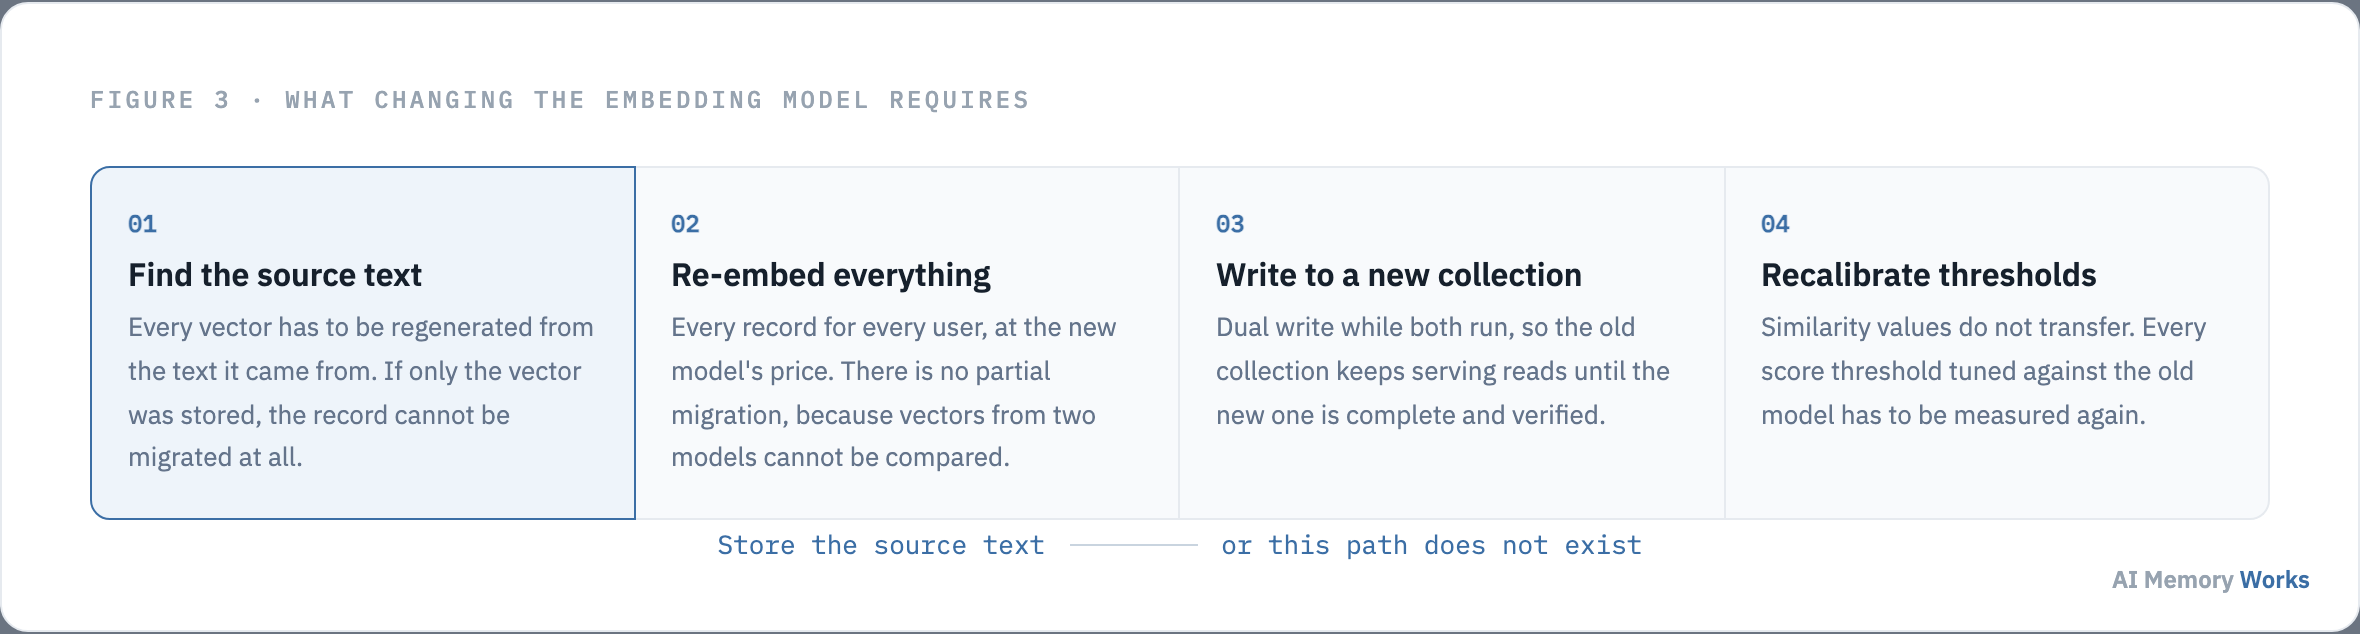
Re-embedding every record for every user, and possibly nothing at all, because the migration may be impossible. This is the difference between a memory store and a document corpus that nobody writing about model selection mentions, and it is the most consequential one.
In document retrieval, changing model is annoying but routine: the source files still exist, so you rerun the ingest and rebuild the index. The corpus is derivable from something you still have.
A memory store is frequently not derivable. The records were extracted from conversations, those conversations may have been discarded under a retention policy, and the extraction involved a model call that will not reproduce identically anyway. If the store kept only the vector and its metadata, there is no text to re-embed, and the model choice made on day one is permanent for every record already written.
The mitigation is one line in a schema and it costs almost nothing: store the original text of every memory beside its vector. Most stores do this by default, since the text is what gets injected into the prompt, but a system that stores a summary and embeds a different string, or that stores only an identifier pointing at a conversation log with a shorter retention period, has quietly closed the door.
Two further steps are worth planning before they are needed. Migrate into a new collection and dual write while both are live, so reads keep working from the old one until the new one is complete. And re-measure every similarity threshold afterwards, because scores do not transfer between models and a bar tuned for one can admit everything or nothing under another.
Since the choice is close to permanent, the criteria that are hardest to reverse deserve the most weight, and the hardest of all is not about quality: should the model run on your own hardware?
Location
Should the model run on your own hardware?
It is a privacy decision first and a cost decision second. The text being embedded is not a public document. It is a statement about an identified person, often including preferences, health details, employment or family information, and every embedding call sends that text to wherever the model runs.
For a hosted API that means a third-party processor handling personal data, which has to appear in your privacy notice and in whatever agreement covers it. For some sectors and some jurisdictions that settles the question on its own, and a self-hosted open-weights model is the only workable answer regardless of what the leaderboard says. The related considerations are on memory security and privacy.
Where privacy does not force the answer, the tradeoff is ordinary. An API removes operational work, scales without capacity planning, and prices per token. A self-hosted model removes the per-call cost and the network hop, and adds a GPU to run and a deployment to maintain. Small open models are capable enough for short-text retrieval that self-hosting is a realistic default rather than a compromise.
One property tips the balance more than it should: deprecation risk. A hosted model that is retired forces exactly the migration described above, on the provider’s schedule rather than yours. A model whose weights you hold cannot be taken away, which for a store you cannot easily re-embed is worth real consideration.
Wherever it runs, the per-turn arithmetic is the same and it is worth doing early: what does embedding cost at conversation volumes?
Cost and latency
What does embedding cost at conversation volumes?
Less than you expect on writes and more than you expect on reads. A memory system embeds on both paths, which is the part that surprises teams whose intuition comes from document retrieval where ingest happens once and reads are free.
On the write side the volume is small. A conversation produces a handful of extracted statements, each a few dozen tokens, so the embedding cost per session is negligible next to the extraction call that produced the statements. On the read side, every turn that retrieves has to embed its query first, which means one call per turn, forever, for every user.
The read path is also where latency lands. An embedding call on a hosted API adds tens to low hundreds of milliseconds before the search has even started, and it sits in the critical path of every response. That is the strongest performance argument for a local model: not throughput, but removing a network round trip from a place the user can feel.
Two reductions are worth having. Cache query embeddings for repeated or near-identical turns, which is more common than it sounds in task-shaped agents. And skip retrieval entirely on turns that plainly do not need it, which removes the embedding call along with the search; whether to retrieve on every turn is covered on memory retrieval.
Cost and latency assume the model works for your users at all, which for many products depends on something a benchmark score hides: does the model have to handle your users’ languages?
Coverage
Does the model have to handle your users’ languages?
Yes, and in memory it has to handle them mixed together in one collection. The requirement is stronger than in document retrieval, where a corpus is often in one language and can be split by language if it is not.
A memory store cannot be split that way, because the memories belong to a person rather than to a language. The same user may state a preference in one language and ask about it in another, particularly in markets where people switch mid-conversation, and the retrieval has to match across that switch. That is a cross-lingual requirement, not merely a multilingual one, and the two are not the same: a model can handle many languages competently while placing the same meaning in different regions of the space depending on which language expressed it.
Test it directly on your own set. Store a memory in one language, query it in another, and check the rank. If it fails, the alternatives are a genuinely cross-lingual model, or normalising memories to one language at extraction time, which is a real option since the write path is already making a model call and the original text is kept anyway.
If coverage or quality is still short after all of this, one more option exists, and it is usually the wrong one: is fine-tuning an embedding model worth it for memory?
The last resort
Is fine-tuning an embedding model worth it for memory?
Rarely, and later than you think. Fine-tuning an embedding model on domain data is a real technique with real gains in specialised corpora, and it is close to the worst first move for an agent memory store.
Three reasons. It requires labelled pairs, and the labelled pairs for a memory system are exactly the ground truth set described above, which most teams do not have and which is better spent choosing between existing models. It produces a model only you have, which makes the migration problem worse rather than better, since you now maintain the training pipeline as well. And the gain is smallest where the text is shortest, because a twelve-word statement offers little domain-specific structure to learn.
The cases where it does pay are narrow and identifiable: a vocabulary that public models have genuinely never seen, meaning internal product names, codes and jargon rather than merely technical language. And even then the cheaper fix is usually lexical rather than semantic, since exact strings are what keyword matching handles best, which is the argument on hybrid search.
Work the order that costs least first. Fix what is being stored, because a badly extracted memory cannot be retrieved by any model. Apply the model’s query and document prefixes correctly. Add the lexical half. Test three candidate models on your own fifty queries. Only if all of that leaves a real gap is fine-tuning the answer, and by then you will have the labelled data to do it properly.
The pipeline these decisions sit inside is set out on how AI memory works, and the store they write into on vector databases for agent memory.
FAQ
Frequently asked questions
The questions that follow the choice: defaults, mixed models, and what to store alongside the vector.
What should I store alongside the vector?
The exact text that was embedded, not a paraphrase of it. That single field is what makes a future model change possible, because re-embedding requires the original input. A store holding only vectors and identifiers pointing at logs with a shorter retention period has no migration path at all.
Can I use different embedding models for different memory types?
Yes, provided each model has its own collection. Vectors from two models are not comparable, so they cannot share an index or be ranked against each other. Separate collections mean separate searches and a merge step, which is the same problem as ranking across layers described on memory scoring.
Do query and document prefixes matter for memory retrieval?
For models that define them, yes, and getting them backwards is a common silent error. The stored memory takes the document side and the constructed retrieval query takes the query side. Check the model card rather than assuming, since the convention differs between families.
Is a smaller dimension worth the quality loss for memory?
Often, because memory collections are small enough that storage is not the constraint and the records are short enough that the extra dimensions carry less. Test the truncated and full versions on your own query set rather than assuming either direction.
How do I know the embedding model is the problem and not something else?
Check whether the right memory is in the candidate set at all. If it is present but ranked below worse candidates, the model or the scoring is at fault. If it is absent, the problem is upstream in what was written or how it was extracted, and no model change will fix it.
Should memories be normalised to one language before embedding?
It is a reasonable option when users switch languages mid-conversation, since the write path is already making a model call and the original text is kept regardless. The alternative is a genuinely cross-lingual model, verified by storing in one language and querying in another.