Infrastructure · Knowledge graphs
How Do Knowledge Graphs Store AI Memory?
A knowledge graph stores an agent’s memory as entities and typed relationships rather than as isolated chunks of text, which lets the agent answer questions that require joining two facts and lets it record when each fact was true. This page covers how graph memory works, where it beats vector search, what it costs, and the case against it made by teams who abandoned it.
What a graph adds
Mechanism
How does knowledge graph memory work?
It stores each thing once as a node, connects things with typed edges that carry meaning, and attaches timestamps so the graph records when a fact became true and when it stopped. A memory stops being a paragraph and becomes a structure the agent can walk.
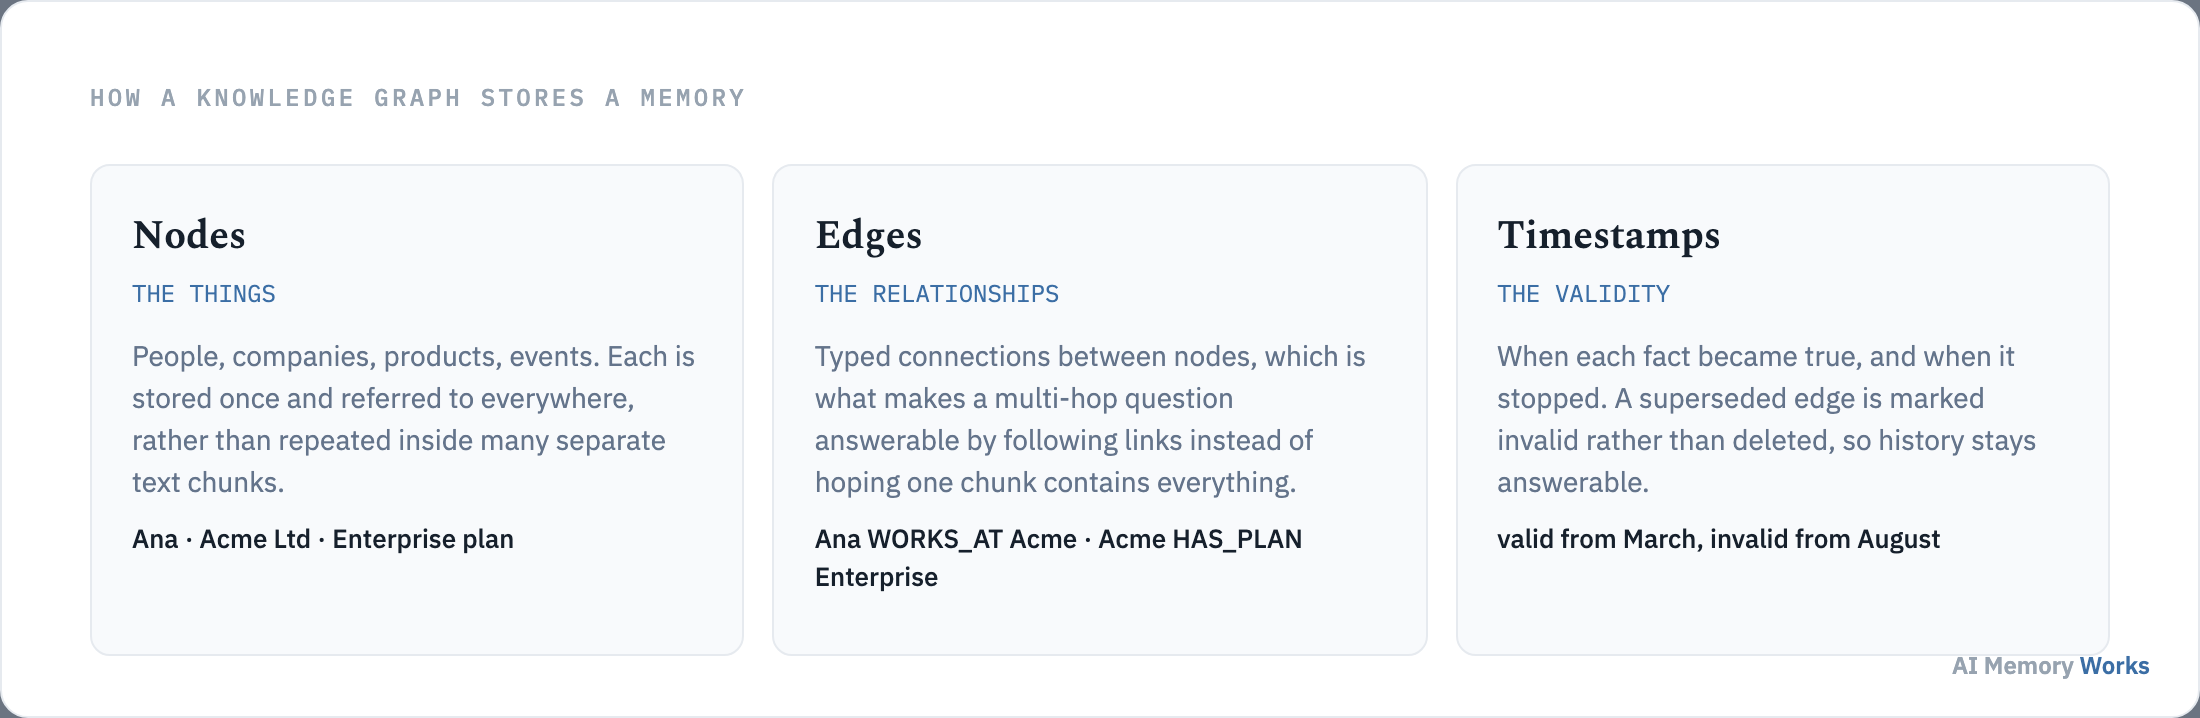
The three parts each do a job that text chunks cannot. Nodes hold entities, so a person, a company or an event exists in one place instead of being repeated inside a dozen stored sentences. Edges hold typed relationships, so “works at” and “used to work at” are different facts rather than similar strings. Timestamps hold validity, so a fact that changed can be marked invalid from a date rather than deleted or left to compete.
Writing to a graph is more work than writing to a vector store. The extraction step has to identify entities, decide whether each already exists, choose a relationship type, and resolve the new fact against what is already connected. That is the cost, and it buys the two capabilities below.
Before the capabilities, it is worth seeing how a conversation becomes a graph at all: how a knowledge graph is built from conversation.
The write path
How is a knowledge graph built from a conversation?
In four steps: extract the entities mentioned, resolve each against entities already in the graph, decide the relationship type, and attach the time from which the fact holds. Only the first step resembles what a vector store does.
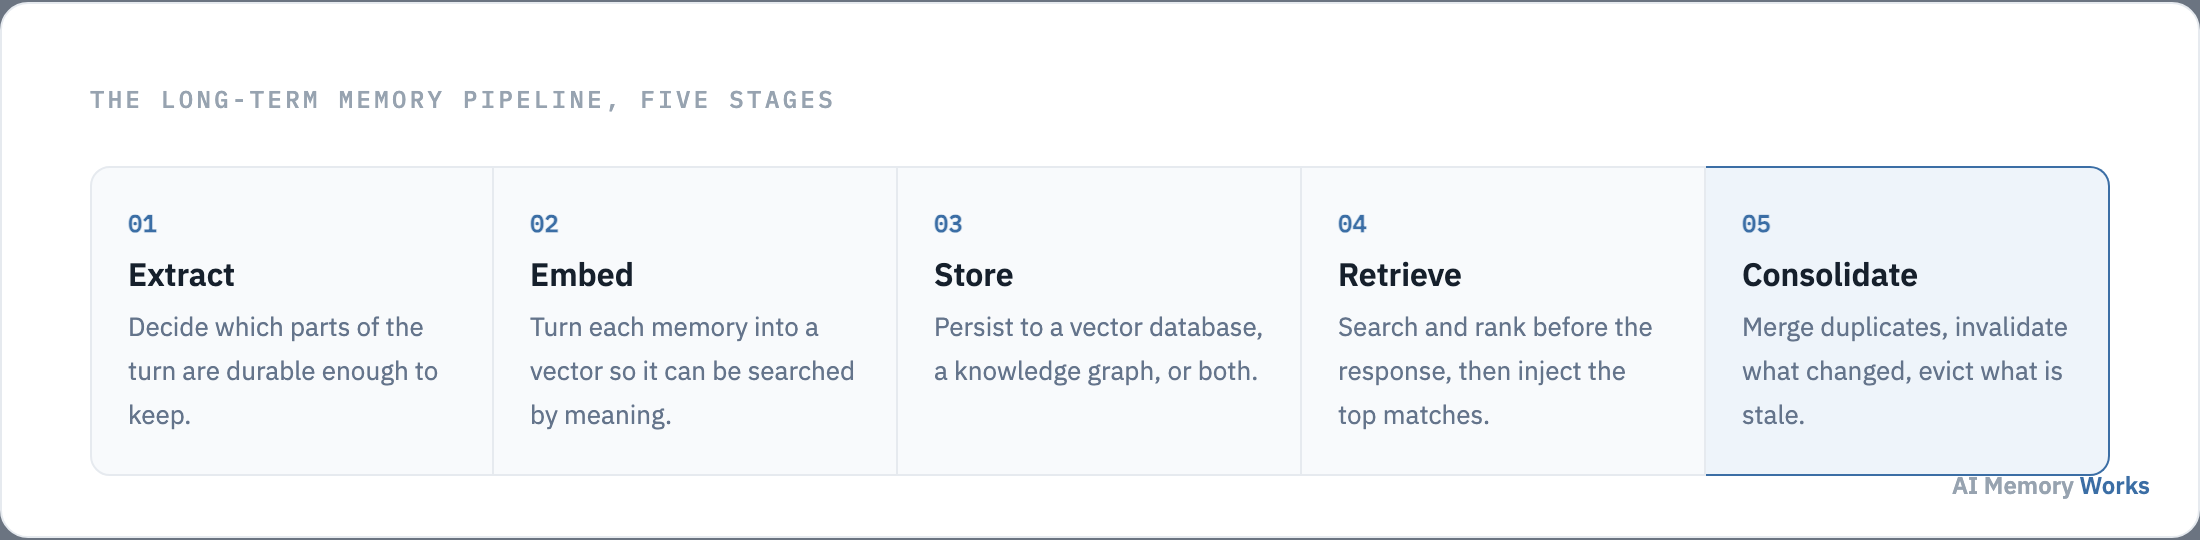
Entity extraction identifies the things a sentence is about. “Ana just moved to the enterprise plan at Acme” contains a person, a company and a plan, and each has to be recognised as an entity rather than as words.
Entity resolution is the step that decides whether this Ana is the Ana already in the graph. Get it wrong in one direction and the graph fills with duplicate people who each know half the story; get it wrong in the other and two different people are merged into one, which is worse because every traversal through that node is now false.
Relationship typing chooses the edge. Deciding between “works at”, “consults for” and “used to work at” is a judgement, and the vocabulary of allowed types is a schema decision that is expensive to change later, since altering it means reprocessing history.
Temporal attachment records when the fact started holding, which is what makes the later invalidation possible. Without it the graph is a snapshot that quietly goes stale.
Every one of those steps can fail in a way a vector write cannot, which is the honest cost of the capabilities that follow: what a graph answers that vector search cannot.
The comparison
What can a graph answer that vector search cannot?
Questions whose answer is spread across two or more facts that were never stored together. Vector search retrieves the chunks most similar to a question, so it succeeds when one chunk happens to contain the whole answer and fails when the answer has to be assembled.
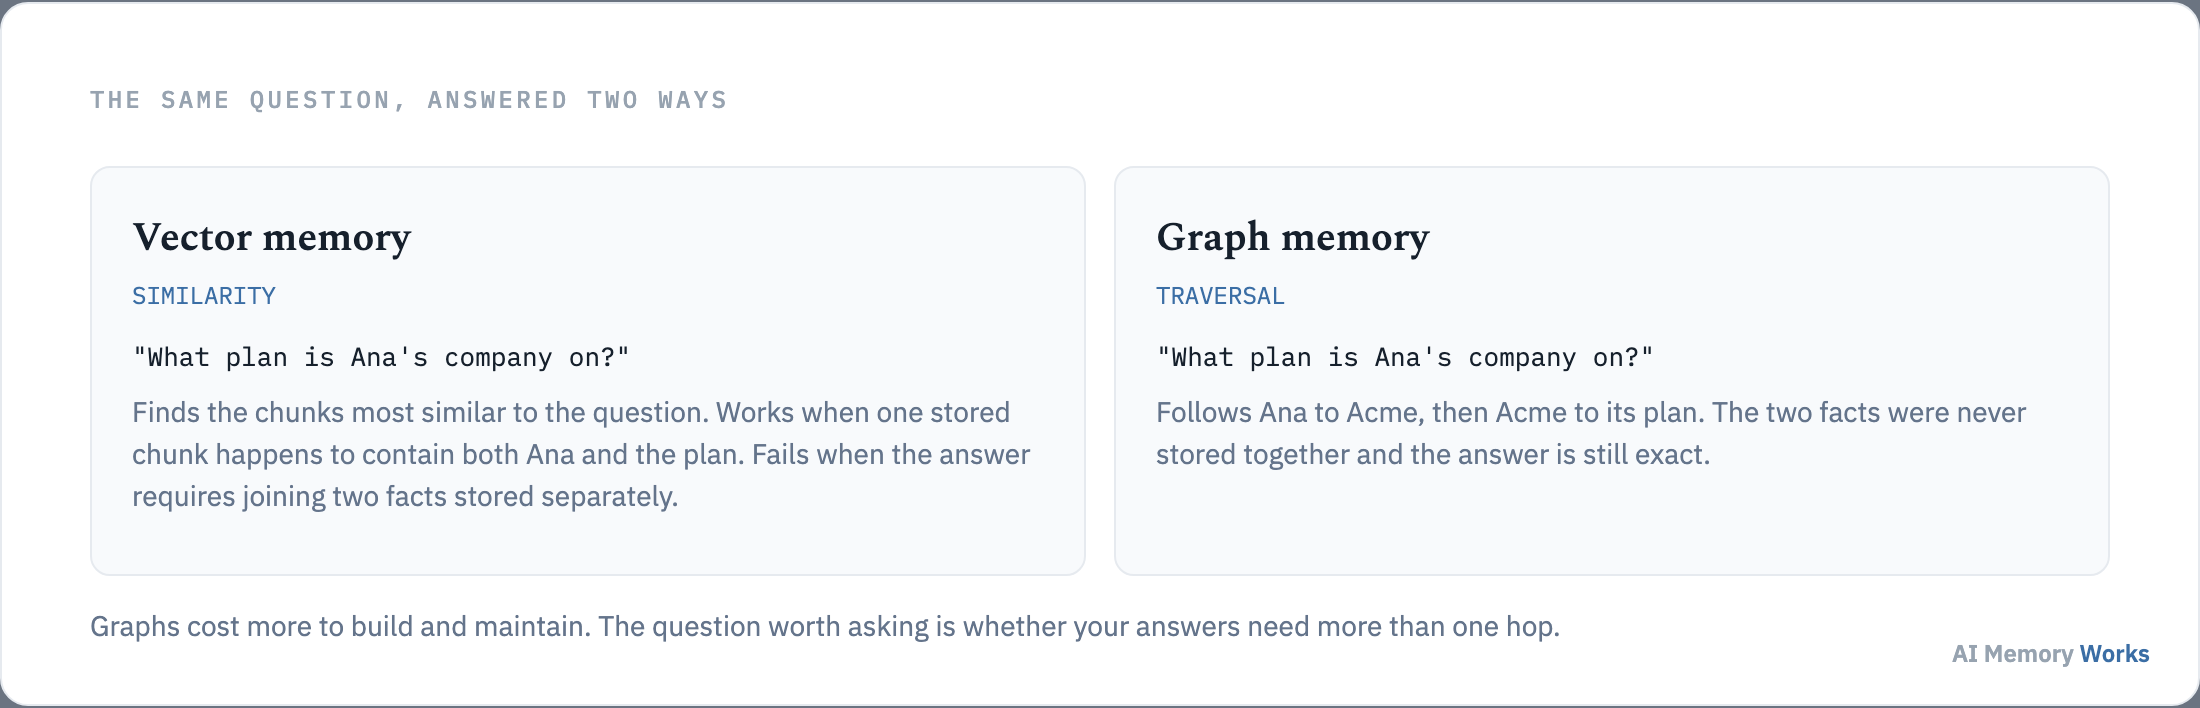
Take a question like which plan a person’s employer is on. If one stored memory says the person works at a company and a different one says the company is on the enterprise plan, similarity search has no reason to return both, because neither is a close match for the full question. A graph walks from the person to the employer and from the employer to the plan, and returns an exact answer built from two facts.
The second capability is temporal. Because edges carry validity, a graph can answer what is true now and what used to be true, without the two versions competing at retrieval time. That is the failure described on handling conflicting and stale memories, and it is the specific problem temporal graphs exist to solve.
The comparison in full, including cost, sits on vector database versus knowledge graph for AI memory.
Those capabilities are exactly what the leading graph implementation was built around: how Zep and Graphiti implement temporal graph memory.
Implementation
How do Zep and Graphiti implement graph memory?
Zep stores agent memory in a temporal knowledge graph built by its Graphiti engine, where each fact carries the period during which it held, and a contradicting fact invalidates its predecessor instead of overwriting it. The architecture is described in “Zep: A Temporal Knowledge Graph Architecture for Agent Memory” by Rasmussen, Paliychuk, Beauvais, Ryan and Chalef (arXiv:2501.13956).
The published results are worth reading precisely. Zep reports 94.8% on the Deep Memory Retrieval benchmark against 93.4% for MemGPT, which is a margin of 1.4 points on a benchmark the MemGPT team designed. On LongMemEval it reports accuracy improvements of up to 18.5% over a full-context baseline with response latency cut by around 90%. The second result is the more interesting one, because it is measured against sending everything rather than against a rival memory system.
The design decision underneath both numbers is invalidation rather than deletion. Keeping the superseded version means the store grows, and it also means an agent can answer a question about the past without guessing. Which of those matters more depends on whether your users ever ask about history.
Other graph-shaped options exist, including Cognee’s evolving knowledge graph and Neo4j-based context graphs built directly. They are covered on Cognee and compared on the best AI memory tools.
Graph memory has a real reputation problem among practitioners, and it deserves a hearing: the case against knowledge graphs for agent memory.
The dissent
Why do some teams abandon knowledge graph memory?
Because the write path is expensive and the payoff only arrives if the product actually asks multi-hop questions. This is a real and common position among engineers who have shipped both, and it deserves stating rather than dismissing.
Three objections come up repeatedly. Extraction is harder. Turning a sentence into entities and typed relationships is a more demanding task than embedding it, and it fails in more interesting ways: a misidentified entity creates a wrong edge that then participates in every traversal. Schema decisions are sticky. Choosing relationship types early constrains what can be expressed later, and changing them means reprocessing history. The traversal advantage goes unused. Many production assistants answer single-hop questions almost exclusively, and for those a vector store returns the same answer with a fraction of the machinery.
The honest summary is that graph memory is a good fit for a narrow, identifiable set of products: those where facts relate to each other, where relationships change over time, and where questions genuinely span several entities. Outside that set it is a cost without a return, and teams who adopted it on the strength of the idea rather than the workload have been right to move back.
What is not in dispute is that the temporal capability is hard to replicate without some structure. A team leaving graphs behind usually still needs a way to mark a fact superseded, which is covered in conflicting memories.
Most of the dissent is really about cost, so it is worth pricing: what graph memory costs to run.
The cost
What does graph memory cost to run?
The cost is concentrated in the write path and in maintenance, not in storage or query time. Graph databases are not the expensive part; producing correct structure from messy conversation is.
Extraction cost per turn is higher, because identifying entities and relationships usually means an additional model call with a more demanding prompt than “summarise the durable facts here”. That cost lands on every write.
Resolution cost grows with the graph. Deciding whether a mentioned entity already exists means searching what is already stored, and that search gets more expensive as the graph grows, exactly when you can least afford it.
Maintenance is ongoing. A schema needs owners. Wrong edges need correcting, and a wrongly merged entity has to be split, which is a data-repair job rather than a delete. None of this appears in a benchmark.
Against that, the query side is often cheaper than expected: a traversal returns an exact answer rather than a set of candidate chunks that then have to be reasoned over, which can mean fewer tokens in the prompt. Whether the trade nets out is entirely a function of how many of your questions need more than one hop.
Which leaves the practical question of whether it applies to you: when a knowledge graph is worth it.
Selection
When is a knowledge graph worth it for agent memory?
When two or more of these are true: your facts change over time, your questions span several entities, or your users ask about history as well as the present. One of them alone rarely justifies the write-path cost.
- Facts expire. Employment, plan tiers, addresses, entitlements and team membership all change, and a store that cannot mark a fact superseded will keep retrieving both versions.
- Answers need joins. If a typical question involves a person, their organisation and something about that organisation, similarity search is being asked to do a job it was not designed for.
- History is queryable. Products where “what did we agree in March” is a real question need validity intervals, not just current values.
A fourth signal is worth adding, because it is the one that catches teams by surprise. If your product ever has to explain an answer, a graph gives you something a vector store cannot. A traversal has a path, so the system can show that it concluded a plan tier by going from the person to the employer to the account. A similarity search can only report that some chunks looked relevant, which is a weak answer to a user asking why the assistant believes something about them. In regulated settings that difference stops being cosmetic.
Where none of those hold, a vector store with good extraction and a deduplication policy will serve better and cost less to run. Many production systems end up hybrid, using vectors for recall and a graph for the relationships that matter, with retrieval combining both, described on hybrid search for memory retrieval.
One more consideration decides it for some teams regardless of the above. A graph is a schema, and a schema is a commitment. If the entities and relationships in your domain are stable, that commitment costs little and pays off in query power. If you are still learning what your product is, a schema written this quarter will constrain what you can express next quarter, and reprocessing history to change it is a real project rather than a migration script. Uncertainty about the domain is a reason to stay with vectors a while longer.
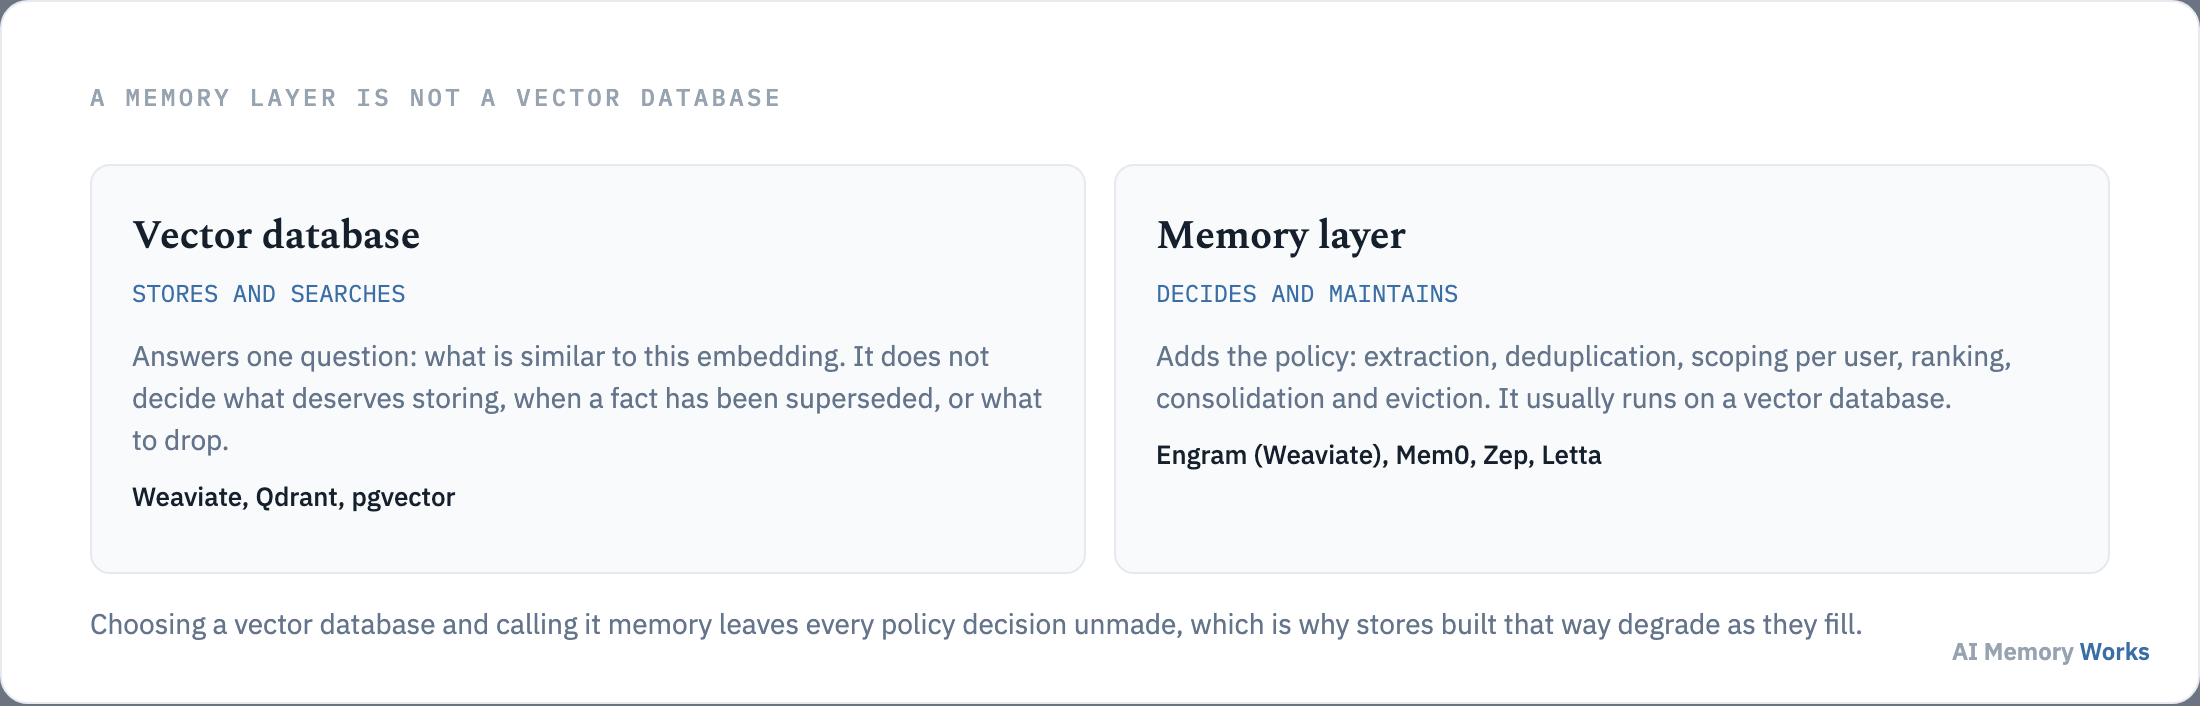
Whichever you choose, the same storage layer sits underneath and the same operations run on top: vector databases for AI memory and memory storage backends cover the alternatives, and long-term memory for AI agents covers the pipeline they both serve.
FAQ
Frequently asked questions
The questions that follow: which graph database to use, and how graph memory relates to GraphRAG.
Knowledge graph vs vector database for agent memory?
Vectors excel at semantic similarity; graphs excel at relationships, temporal validity and conflict resolution. CRM and policy domains favor graphs; open-ended chat prefs favor vectors. Many teams hybrid both.
What is Graphiti?
Zep's open-source temporal knowledge-graph engine — extracts entities/relationships, invalidates superseded facts bi-temporally. Described in Rasmussen et al. (2025, arXiv:2501.13956). See Zep alternatives.
Is Zep open source?
Graphiti is open source; Zep offers managed cloud + self-hosted options. Compare Engram (Weaviate-native), Mem0 and Letta on Zep alternatives.
What does temporal memory mean?
Facts have validity windows — you can query what was true at a point in time. Graph edges carry valid_from/valid_to timestamps. Zep's core differentiator vs flat vector stores.
Does Mem0 support graph memory?
Mem0 is primarily vector-semantic memory, like Engram. For native temporal graphs, compare Zep or Cognee.
Does Engram use knowledge graphs?
Engram is vector-native on Weaviate — not graph-first. For temporal graph memory, compare Zep/Graphiti. Engram leads for simpler Weaviate-backed semantic memory. See Engram explained.
CRM data as a knowledge graph for agents?
Map accounts, contacts and policies as graph nodes with temporal edges. Sync CRM updates to invalidate stale agent memories. Zep fits this pattern natively.
How do you build a DIY graph memory backend?
Neo4j or similar + LLM extraction pipeline + bi-temporal edge schema + hybrid vector index on node text. Higher ops burden than Zep/Engram managed options.