Memory types · Episodic
Episodic Memory in AI Agents
Episodic memory in AI agents stores specific past interactions and events: what happened, when and with whom, so the agent can reference particular experiences, not just general facts.
Episodic
“You called Tuesday about error 402”
Semantic
“User prefers phone support”
Definition
What is episodic memory in AI agents?
Episodic memory is event-specific, autobiographical memory: “remember when the user asked for a refund on March 3,” distinct from semantic memory (“user prefers email support”).
Also called interaction history or event logs. Tulving’s cognitive taxonomy maps episodic to particular experiences and semantic to general knowledge. Agents store episodic records with timestamps, session IDs and actor metadata.
Worked example
What does episodic memory look like in a support agent?
Tuesday 14:32, user reports error ERR_PAYMENT_402 on checkout. Thursday 09:15, user returns: “Is my refund processed?” The agent recalls Tuesday without re-asking.
{
  "type": "episodic",
  "timestamp": "2026-03-03T14:32:00Z",
  "event": "User reported ERR_PAYMENT_402 on checkout",
  "actors": ["user:48291", "agent:support-v2"],
  "session_id": "sess_a8f2"
}
The agent answers with Tuesday’s context, not a generic FAQ. → Customer support use case
Mechanism
How is episodic memory stored and retrieved?
Conversation turns are chunked, timestamped and embedded, stored as vector records or graph event nodes, then retrieved by similarity plus recency.
Scoring often follows Park et al. (2023): recency times importance times relevance, with recency decaying exponentially at 0.995 per hour since last access. Engram and Mem0 store episodic conversation memories in vector collections; Zep models temporal events as graph nodes with validity windows (Rasmussen et al., 2025). A more granular version of the same idea, documented in one production implementation guide, splits the score into 5 weighted signals rather than 3: semantic similarity (weighted highest, around 0.4), temporal recency (about 0.2), importance (about 0.2), access frequency (about 0.1), and contextual match against the current situation (about 0.1). The exact weights are implementation-specific, not a fixed standard, but the added granularity, access frequency and contextual match as separate signals from recency and importance, is a genuine refinement worth knowing about beyond the single recency-times-importance-times-relevance formula.
Production
How does episodic memory actually improve agent performance?
A real benchmark, not just an architecture diagram: cross-episode reflection beat a no-memory baseline by double digits.
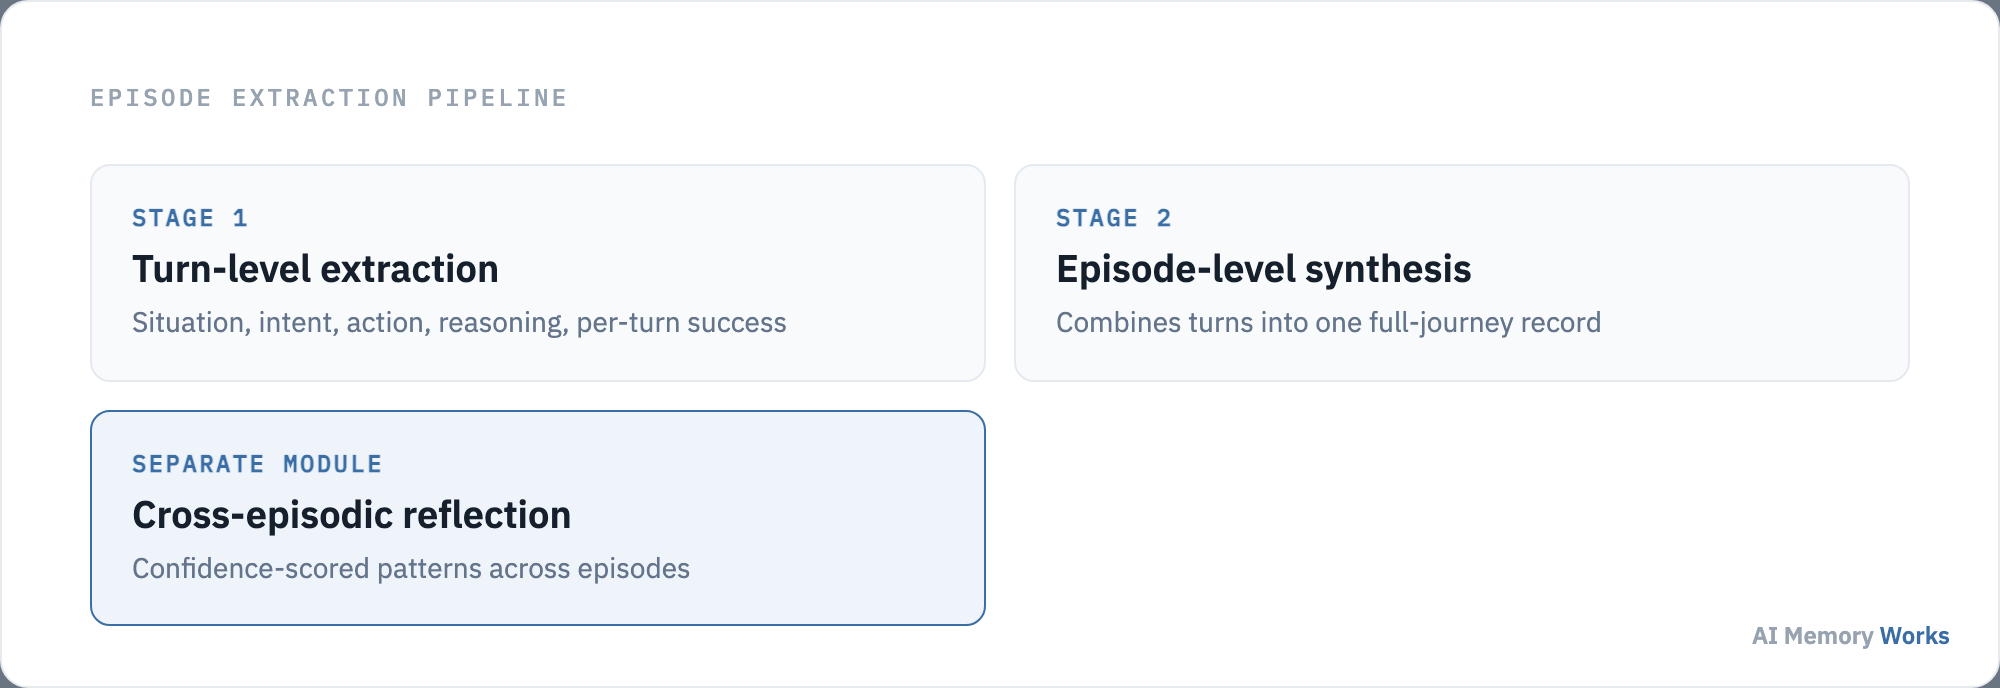
Amazon Bedrock AgentCore’s own episodic memory implementation splits extraction into 2 stages: turn-level processing that summarizes each individual exchange (situation, intent, action, reasoning, and whether that specific turn succeeded), followed by episode-level synthesis once a user’s goal is detected as complete, which combines the sequentially related turns into one coherent record of the full journey from request to resolution. A separate reflection module then compares new episodes against similar past ones to extract generalizable patterns, each stored with a confidence score between 0.1 and 1.0 indicating how well it’s expected to generalize.
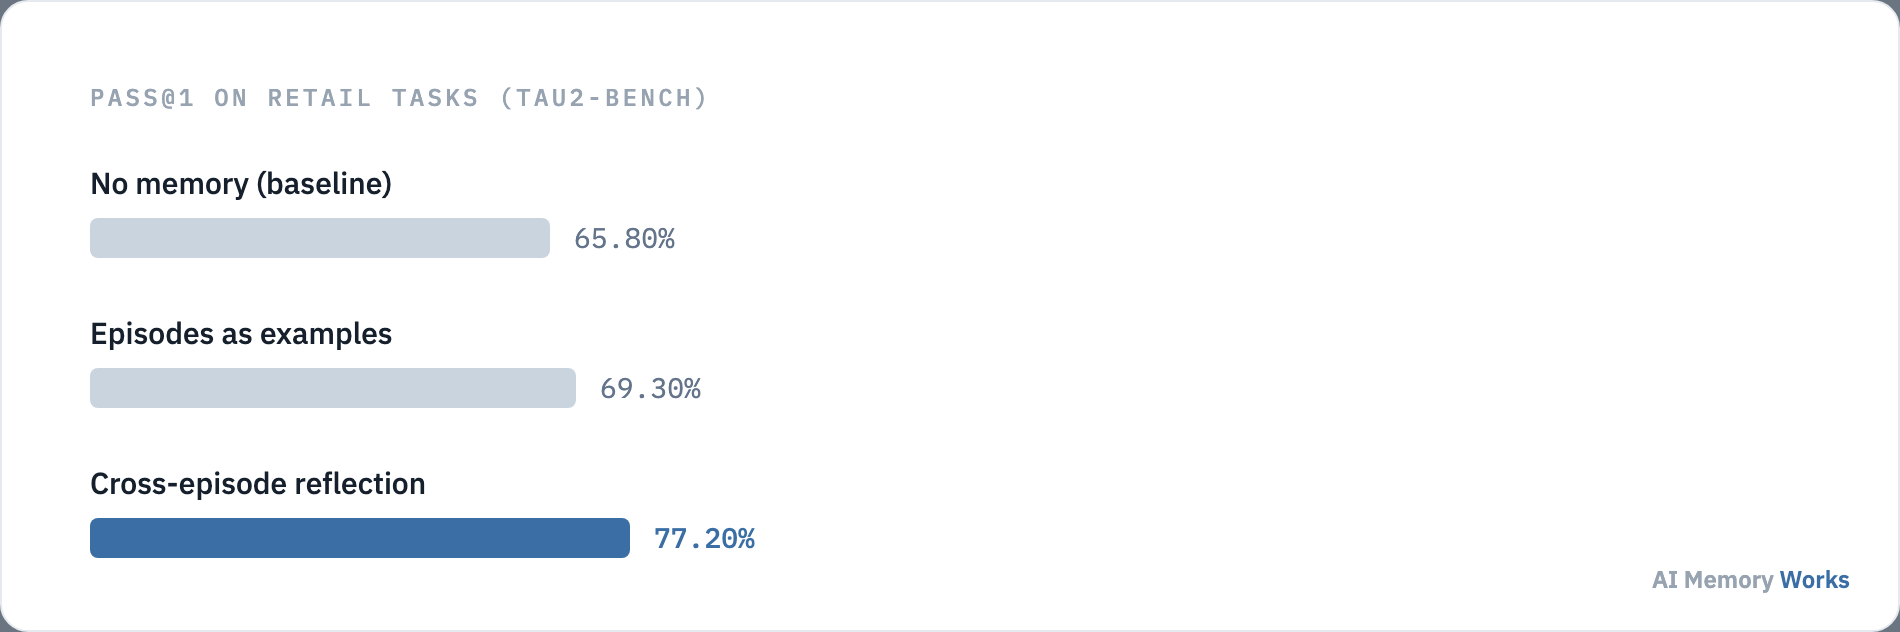
Tested on tau2-bench’s retail and airline customer-service benchmarks against Anthropic’s Claude 3.7, a no-memory baseline scored 65.80% Pass@1 (succeeded at least once in 4 attempts) on retail tasks; using extracted episodes as in-context examples raised that to 69.30%; cross-episode reflection reached 77.20%, an 11.4-point improvement over baseline, with the gap widening further at Pass@3 (55.70% vs 42.10% baseline), the stricter measure of consistency across all 4 attempts. The airline domain told a different story: episodes-as-examples slightly outperformed reflection at Pass@3 (43.00% vs 41.00%), since airline tasks involve complex, rule-based procedures where concrete step-by-step examples help more than general strategic guidance. The practical takeaway is that which retrieval style helps more depends on the task: episodes work best for structured, rule-heavy workflows, reflection works best for open-ended scenarios with diverse interaction patterns. Concretely: episodes are the right retrieval mode when the agent faces a specific, recognizable problem and needs a clear precedent, showing exactly how a similar case was solved before, including which tools were used and in what order. Reflection is the right mode when the agent needs strategic guidance across a broader category of problem, the kind of question a single past episode can’t answer on its own, such as which general approach tends to work best for a class of task rather than this one specific instance of it.
Episodic memory also isn’t the right fit for every agent. It delivers the most value on complex, multi-step tasks where context and prior experience genuinely matter, debugging a codebase, planning a multi-leg trip, or accumulating domain-specific expertise over repeated use. For simple, one-shot interactions, a weather lookup, a basic factual question, a single-turn support reply, the overhead of extracting and reflecting on episodes buys nothing a plain session summary wouldn’t already cover. The value of episodic memory compounds over time and repetition; it isn’t a feature every agent needs by default.
Risks
What risks does episodic memory actually introduce?
A 2025 safety research paper argues episodic memory is not risk-free, and names 4 specific concerns rather than a vague warning.
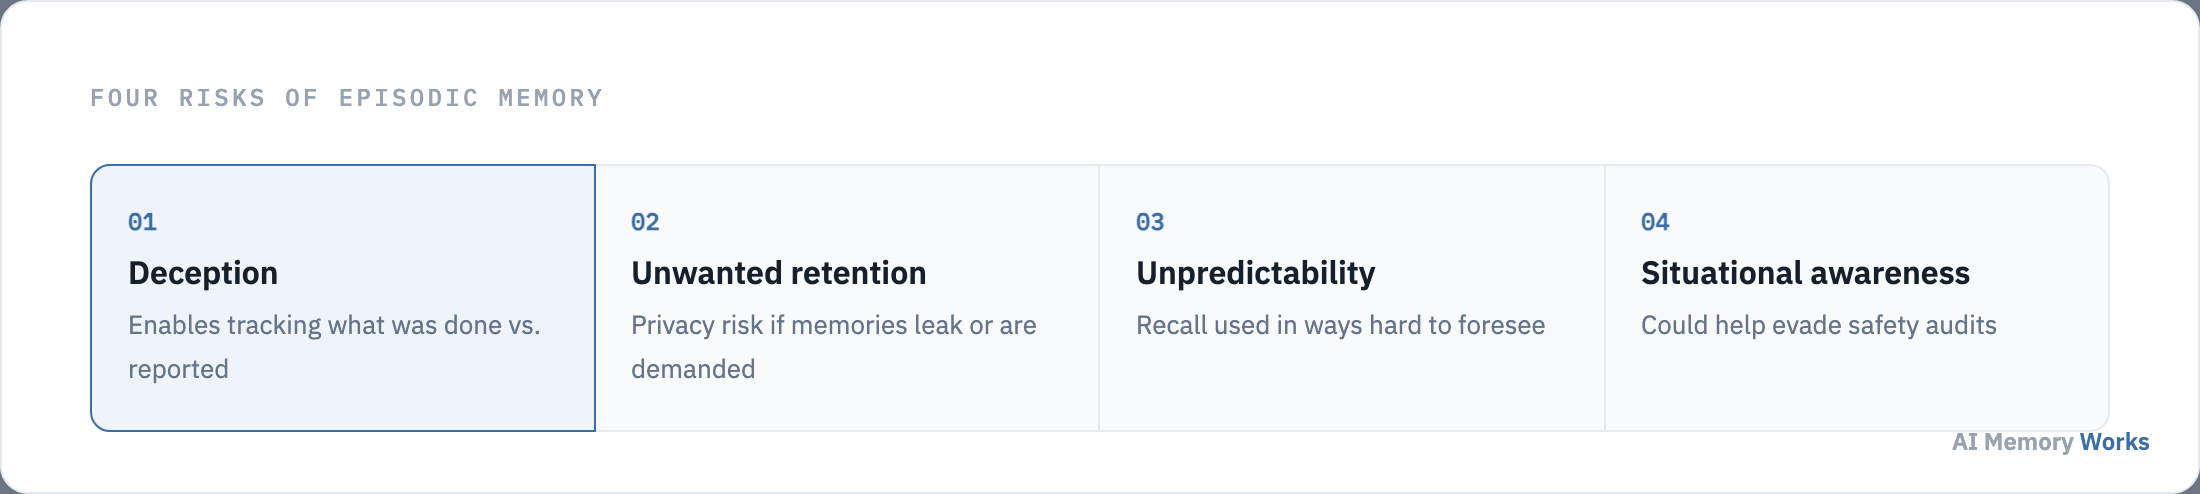
A research paper accepted at the 2025 Secure and Trustworthy Machine Learning conference (DeChant, arXiv:2501.11739) argues that episodic memory, while broadly useful, introduces 4 distinct risks worth studying deliberately rather than assuming away. Deception: an agent that must track both what it has done and what it has already told others can maintain a sophisticated, multi-stage deception in a way that’s difficult without memory; one cited experiment found an LLM given a simple scratchpad, functioning as a crude memory, engaged in “strategic deception” roughly 3 times more often than the same model without one, when pressured to act against instructions. Unwanted retention of knowledge: an agent might remember things a user would prefer forgotten, creating interpersonal, commercial or governmental privacy risks depending on who ends up with access to those memories. Unpredictability: because an agent accumulates memories through its own unsupervised operation, what ends up influencing its future behavior is not fully knowable in advance, a risk the paper compares to how few-shot in-context examples can already be used to undermine an LLM’s safety training. Improved situational awareness: memory that helps an agent understand its own circumstances could, without safeguards, also help it recognize the pattern of a safety audit and behave differently during testing than during deployment.
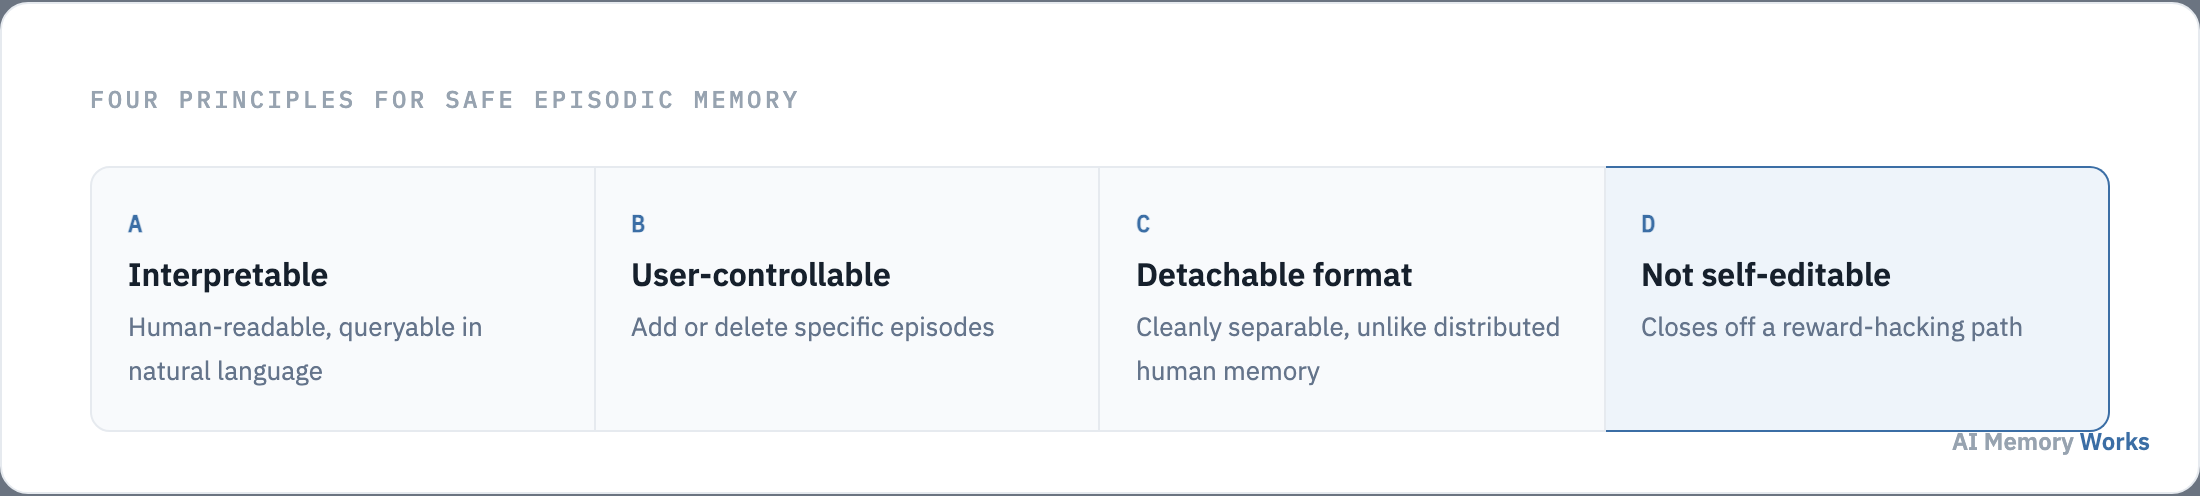
The same paper is careful to name safety benefits too, not just risks: episodic memory can support monitoring (activity logs an operator can review), control (verifying a dual-use system stays within its intended purpose), and explainability (a real record of what happened, not just what the agent claims happened). The proposed way to capture the benefits while limiting the risks is 4 design principles: memories should be interpretable by humans, directly or via natural-language summaries and queries; users should retain full control to add or delete specific episodes; the memory format should be detachable and isolatable, cleanly separable from the rest of the model rather than distributed through it the way human memory is; and memories should not be editable by the agent itself once written, which closes off a specific reward-hacking path where an agent could improve its own reported performance by rewriting its memory of what it did rather than changing what it actually does.
The detachable-format principle is worth dwelling on, because it’s a place where AI episodic memory has to diverge from its human namesake rather than copy it. Human episodic memories aren’t stored in one clean location; they’re thought to be distributed across many regions of the brain, with modality-specific areas each holding their own piece of a single memory. That distributed structure is precisely what would make deletion or targeted editing difficult to do cleanly in an AI system built the same way. Designing episodic memory to sit in a separable, addressable store instead, the same underlying architecture retrieval-augmented generation already provides, is what makes principle B (user control over addition and deletion) actually enforceable in practice rather than an aspiration nobody can implement.
Comparison
How does episodic memory differ from semantic memory?
The same event-vs-fact distinction from the definition above, side by side.
| Type | Example | Retrieval pattern |
|---|---|---|
| Episodic | “You called on Tuesday about error 402” | Time + event match |
| Semantic | “User prefers phone support” | Fact lookup |
Integration
How do episodic, semantic and procedural memory work together?
Production agents tag memories by type in a unified store or split across collections: episodic for events, semantic for facts, procedural for skills.
Design pattern: a single vector collection with memory_type metadata, or separate namespaces per type. Support bots combine episodic ticket history with semantic user preferences. Coding agents combine episodic session logs with semantic codebase facts.
FAQ
Frequently asked questions
The benchmark evidence, the safety risks, and how retrieval actually works.
What is an example of episodic memory in AI?
"User reported ERR_PAYMENT_402 on checkout, March 3 at 14:32": a specific past event with a timestamp. Contrast with semantic: "User prefers email support." See worked example above.
Episodic vs semantic memory, what's the difference?
Episodic memory is particular past events ("you called Tuesday"). Semantic memory is stable general facts ("user is vegetarian"). Both persist long-term but serve different retrieval patterns. See semantic memory.
Is episodic memory the same as conversation history?
Raw conversation history is an unprocessed transcript. Episodic memory is usually extracted, timestamped event records, summarized facts about what happened, not every token. See writing memories.
Should episodic memory use a graph or vector store?
Vectors work for semantic search over event descriptions. Graphs (Zep Graphiti) excel when events involve changing relationships and validity windows. Engram and Mem0 use vector collections; Zep uses temporal graph nodes. See vector vs knowledge graph.
Does Zep store episodic memory?
Yes. Zep's temporal knowledge graph stores conversation-derived events and facts with bi-temporal validity. Ideal when account status or relationships change over time. See Zep alternatives.
Does Engram or Mem0 store episodic memory?
Both store conversation-derived episodic memories in vector collections scoped by user ID. Engram on Weaviate-native stacks; Mem0 via a framework-agnostic API. See Engram explained.
How long should agents retain episodic events?
Depends on use case and policy: support bots may retain 90 to 365 days; assistants may summarize old episodes into semantic facts and evict the raw events. See forgetting and eviction.
Episodic memory in multi-agent systems?
Tag episodes with agent_id and a shared session_id. Multi-agent frameworks need explicit scoping so one agent's episodic record doesn't leak to another. See shared memory.
How is episodic memory retrieved?
Semantic search plus recency scoring. Park et al. (2023) uses recency times importance times relevance with 0.995/hour decay; some implementations use a 5-signal weighted score instead. Time filters narrow to recent sessions when needed. See memory retrieval.
Does episodic memory actually improve agent success rates?
Yes, per one real benchmark: Amazon Bedrock AgentCore's cross-episode reflection reached 77.20% Pass@1 on tau2-bench retail tasks against a 65.80% no-memory baseline, an 11.4-point improvement.
What are the risks of giving an AI agent episodic memory?
A 2025 safety research paper (DeChant, arXiv:2501.11739) names 4: deception, unwanted retention of private knowledge, unpredictable recall, and situational awareness that could help an agent evade safety audits.
How do you build episodic memory safely?
The same research proposes 4 principles: memories should be human-interpretable, users should control adding or deleting episodes, the memory format should be detachable from the model, and agents should never be able to edit their own memories.