Comparison · Memory and fine-tuning
Memory vs Fine-Tuning for AI Agents
Fine-tuning changes how a model behaves for everyone who calls it. Memory changes what the model knows about one person right now. They are not competing solutions to one problem, and the fastest way to tell which you need is to ask what happens when the information changes: memory retires a fact in a single write, while a fine-tuned model cannot unlearn one without being trained again.
Two levers
The distinction
What is the difference between memory and fine-tuning?
Fine-tuning writes into the model’s weights, which are shared by every caller and changed only by training. Memory writes into a store outside the model, scoped to one user and changed by a single row. That difference in where the information lives determines everything else about the two.
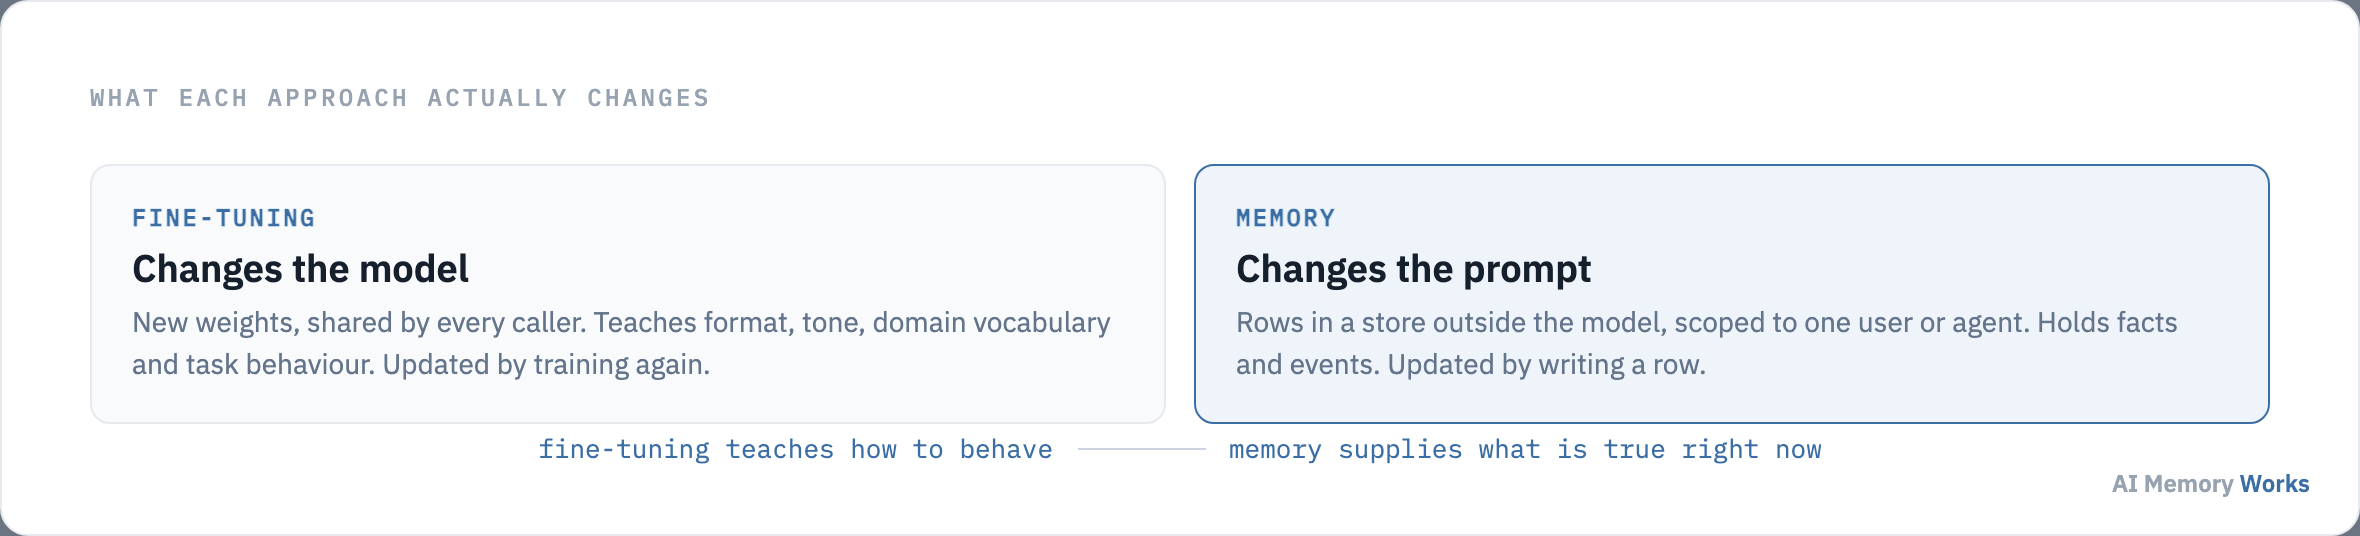
Fine-tuning is how you teach a model to do something in a particular way: to emit a rigid output format, to use a domain’s vocabulary correctly, to follow a house style that instructions keep drifting away from. It generalises, which is its strength: a model fine-tuned on a thousand examples of a task handles the thousand and first.
Memory is how you tell a model a fact about the situation in front of it. It does not generalise and is not supposed to: knowing that one customer is on the enterprise plan says nothing about any other customer, and the value is precisely that it applies to this one.
In the vocabulary of the research literature, fine-tuning produces parametric memory and an external store produces non-parametric memory, a distinction worked through on parametric versus non-parametric memory.
Since fine-tuning is the answer people usually consider first, it is worth stating clearly where it is genuinely the right one: when to fine-tune instead of adding memory.
The case for fine-tuning
When should you fine-tune instead of adding memory?
When you need behaviour rather than facts, and prompting has already failed to produce it reliably. That last clause matters, because a great deal of fine-tuning is done to solve problems a better prompt would have solved for nothing.
Rigid output formats are the clearest case. If every response must be valid against a schema and prompting still yields malformed output on a small fraction of calls, that fraction is a production problem, and training removes it in a way instructions do not.
Specialised vocabulary is the second. Clinical language, legal drafting conventions and industrial terminology are domains where a general model is subtly wrong in ways that are hard to correct with instructions and easy to correct with examples.
Cost and latency at volume are the third and most underrated. A smaller fine-tuned model can match a larger prompted one on a narrow task, and at high volume that is a real saving. It also shortens the prompt, since behaviour encoded in the weights does not have to be restated every call.
What none of those involve is a fact that might change tomorrow. That is the boundary, and on the other side of it sits everything memory is for: when memory is the right choice.
The case for memory
When is memory the right choice?
Whenever the information is about a specific person or situation, might change, and has to be correct rather than approximately right. Those three conditions describe most of what an agent needs to know that it was not born knowing.
Preferences, entitlements, account state, prior decisions and outcomes all qualify. Each is true of one user, each can change, and each has to be exact: an agent that half-remembers a dietary restriction is worse than one that asks.
Memory is also the right choice when the information arrives continuously. Fine-tuning has a cadence measured in weeks and a conversation has a cadence measured in seconds, so anything learned during an interaction has nowhere else to go. That is the ordinary case for an assistant, covered on why AI agents need memory.
The third case is auditability. A memory can be shown to the user, corrected by them and deleted on request, because it is a row with a source. Information trained into weights can be none of those things, which turns a routine data-protection request into an impossible one.
Between the two lies the question most people are actually asking when they compare them: whether fine-tuning can make an agent remember an individual user.
Personalisation
Can fine-tuning make an agent remember an individual user?
Not at the scale of individual users. Weights are shared by everyone who calls the model, so a fact trained into them is a fact about everybody, and training a separate model per user turns each user into a training job, an artefact to store and an endpoint to serve.
Parameter-efficient methods such as LoRA adapters make per-user variants technically conceivable rather than practical. Each user needs data collected, a training run, an adapter stored and loaded at inference. At a thousand users that is an unusual and expensive system; at a million it is not a system anyone is running.
The timing objection is worse than the cost one. A user tells the agent something at 10am and expects it honoured at 10:01. No training loop closes in a minute, so even a working per-user fine-tuning pipeline would leave a window in which the model does not know what it was just told, which is the exact failure the feature exists to remove.
The deletion objection closes it. If a user asks for their data to be removed and it was trained into weights, honouring that means retraining without them, and even then no clean guarantee is available about what the model retained. A memory row is deleted by deleting the row, which is why memory security is a tractable subject at all.
Fine-tuning can still shape how an agent talks to a class of users, a tone for support staff and another for end customers. What it cannot do is hold what any one of them said. The mechanics of doing that properly are on user memory and personalisation.
The same limitation appears in a sharper form the moment anything you taught the model stops being true: what happens when a fact changes.
Updating
What happens to each approach when a fact changes?
Memory ends the old fact and writes the new one. A fine-tuned model cannot unlearn a single fact, so the only remedy is another training run, and until it ships the model states the old value with complete confidence. This is the difference that decides most real cases.
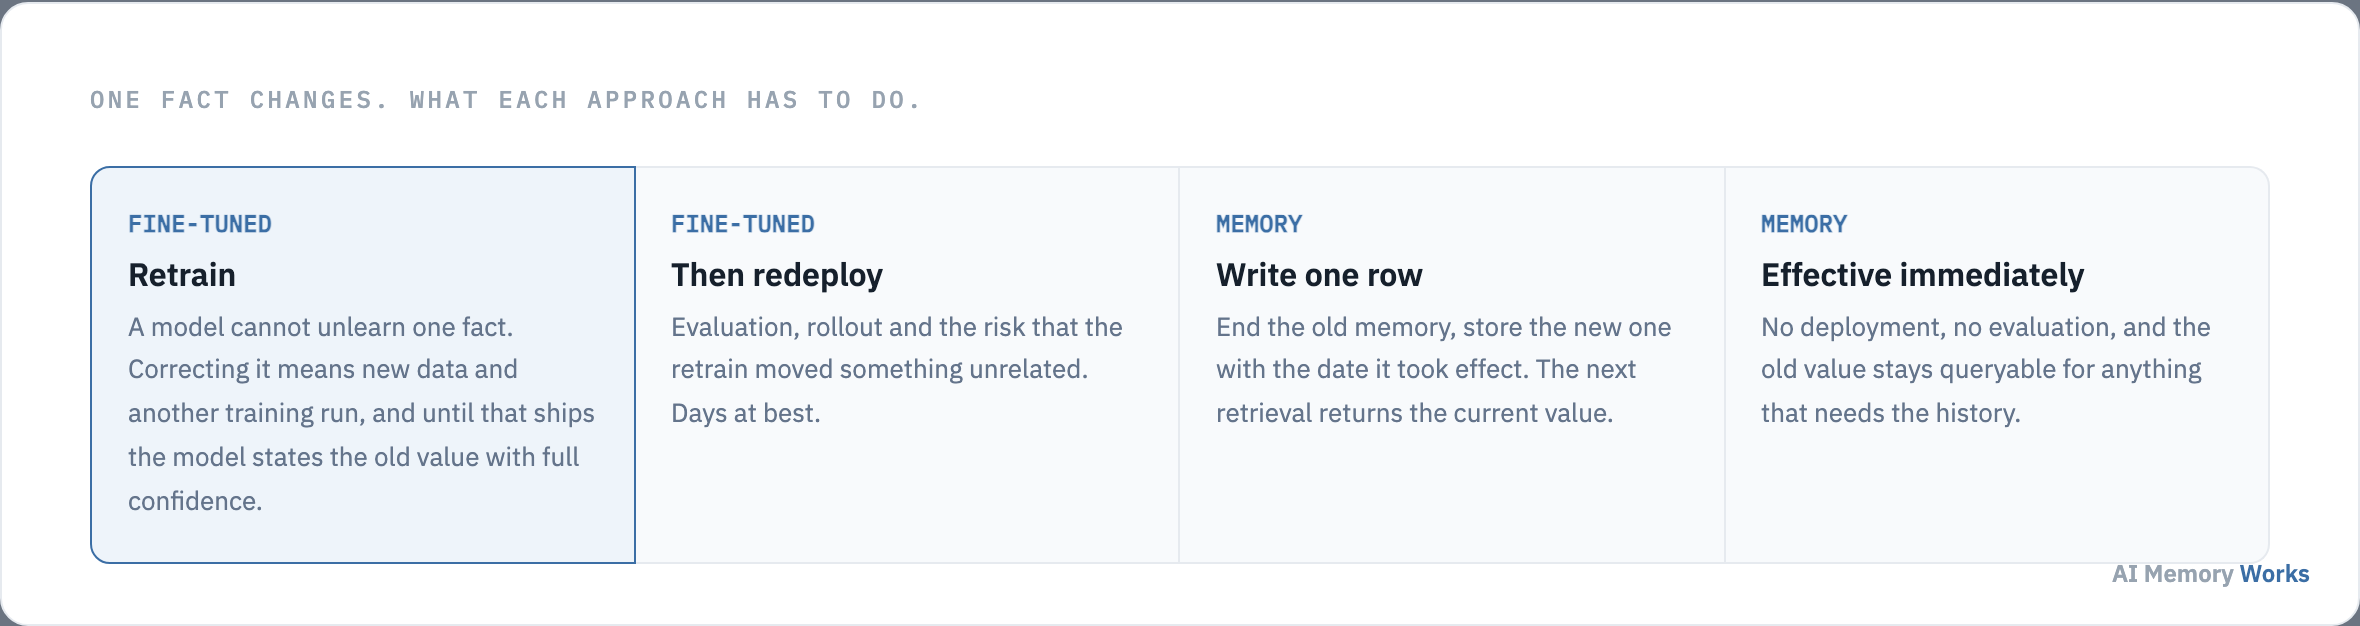
Confidence is what makes the fine-tuned failure worse than it looks. A model repeating an outdated policy does not hedge, because as far as its weights are concerned that policy is simply how the world is. A stale memory at least carries a timestamp and a source, which is why it can be caught by the invalidation rules on handling conflicting memories.
Memory also keeps the history, which matters more often than people expect. A refund window that changed in April did not become untrue for the customer who bought in March, and a store that records when each version applied can answer both questions. A retrained model can answer only the current one.
There is a subtler version of the same problem. Fine-tuning on facts teaches the model to state them fluently whether or not it retained them accurately, which produces confident answers with no retrieval step to check. Keeping facts in a store and behaviour in the weights avoids that whole class of error.
Update behaviour is also where the honest cost comparison lives: what each approach really costs.
Cost
What does each approach really cost?
The money is a smaller difference than it looks. The cost that separates them is iteration speed: the time between noticing that the system is wrong and having it right. For memory that is minutes; for fine-tuning it is a training and evaluation cycle.
Fine-tuning costs a dataset first, and the dataset is the expensive part rather than the compute. Assembling and cleaning training examples is human work, it has to be repeated whenever the task shifts, and it is the reason fine-tuning projects overrun. After that come the training run, an evaluation pass to check nothing unrelated regressed, and a deployment.
Memory costs an extraction model call per conversation, storage measured in kilobytes per user, and the tokens each retrieved memory adds to a prompt. Its serious cost is engineering: the schema, the selection rule, the deletion surface and the tests, as set out on what changes in an application when you add memory.
Against both sits what memory removes. An agent that retrieves four relevant facts instead of replaying an entire conversation history is cheaper per turn than the naive alternative, which is covered on reducing token cost with memory.
Neither of them is the only option on the table, and the third one is the reason many of these comparisons are miscast: where RAG fits alongside both.
The third option
Where does RAG fit alongside memory and fine-tuning?
RAG covers shared documents, memory covers per-user facts, and fine-tuning covers behaviour. A great many “should I fine-tune” questions are answered by RAG, because what the asker needs is for the model to know a body of documentation, not to behave differently.
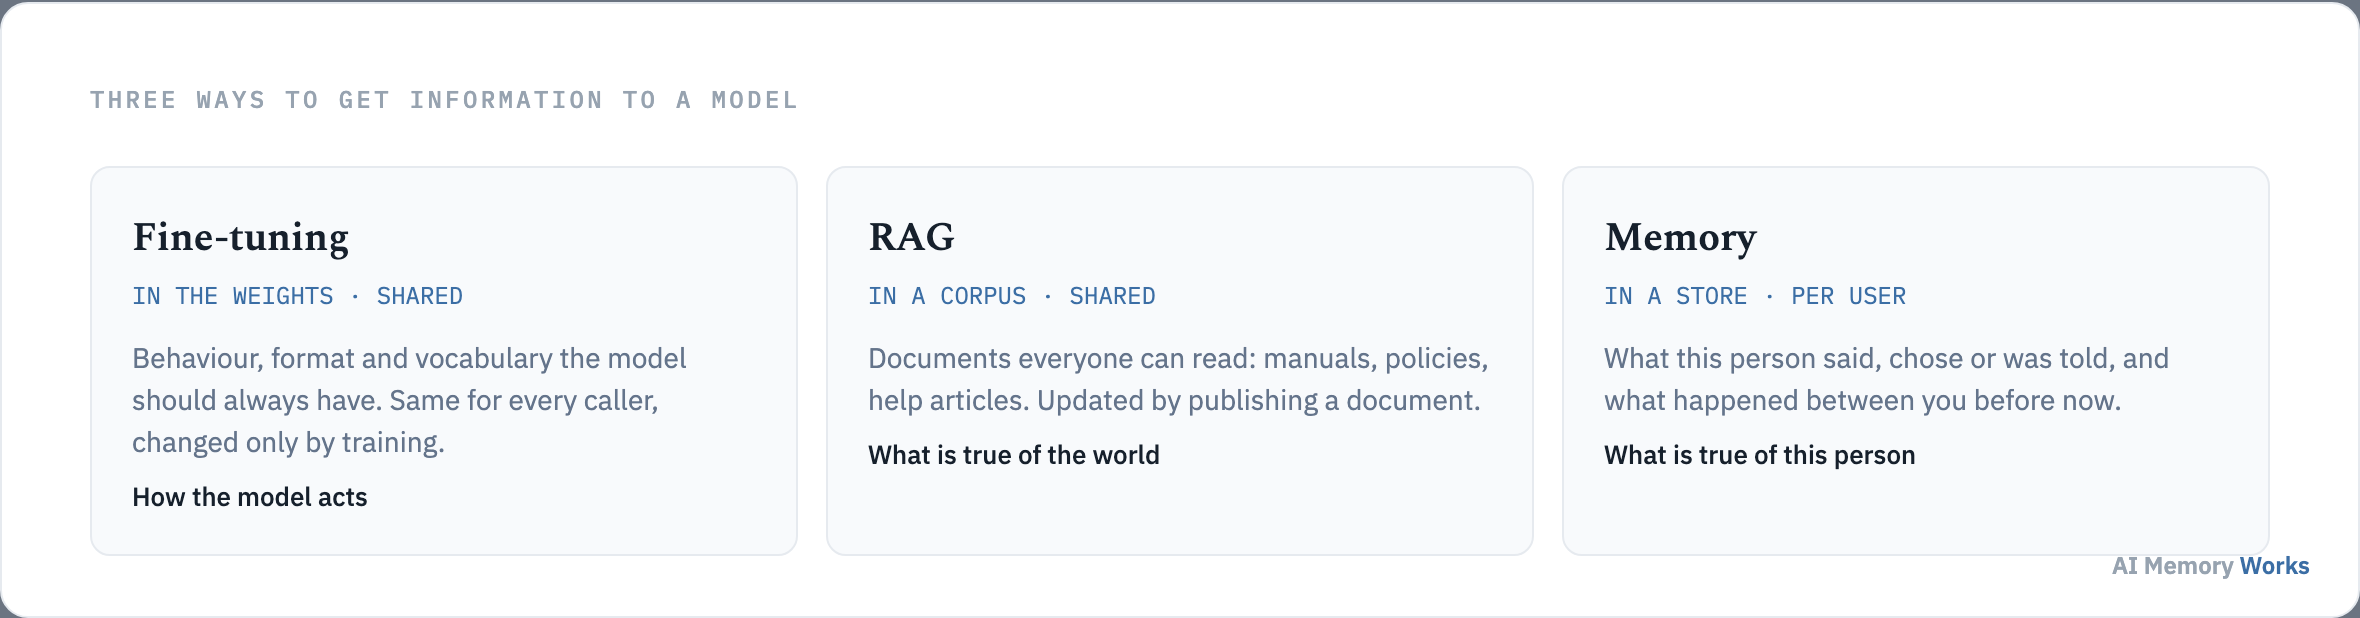
Documentation, policies, product manuals and help articles are shared, change on a publishing schedule and are authored deliberately. That is a corpus, and retrieval over it is the right tool, described on retrieval-augmented generation.
Memory differs from RAG in who the information is about rather than in how it is retrieved. Both search an index and place results in a prompt; one index is shared by everyone and the other is partitioned per person, which makes a mistake in the first a wrong answer and a mistake in the second a data breach. The full comparison is on memory versus RAG.
Once the three are separated this way, the useful question stops being which to pick: whether you can use them together.
Both
Can you use memory and fine-tuning together?
Yes, and most mature systems do: fine-tuned behaviour, a retrieved corpus and a per-user memory store, composed into one prompt. They are not alternatives, they are three layers updating on three different schedules.
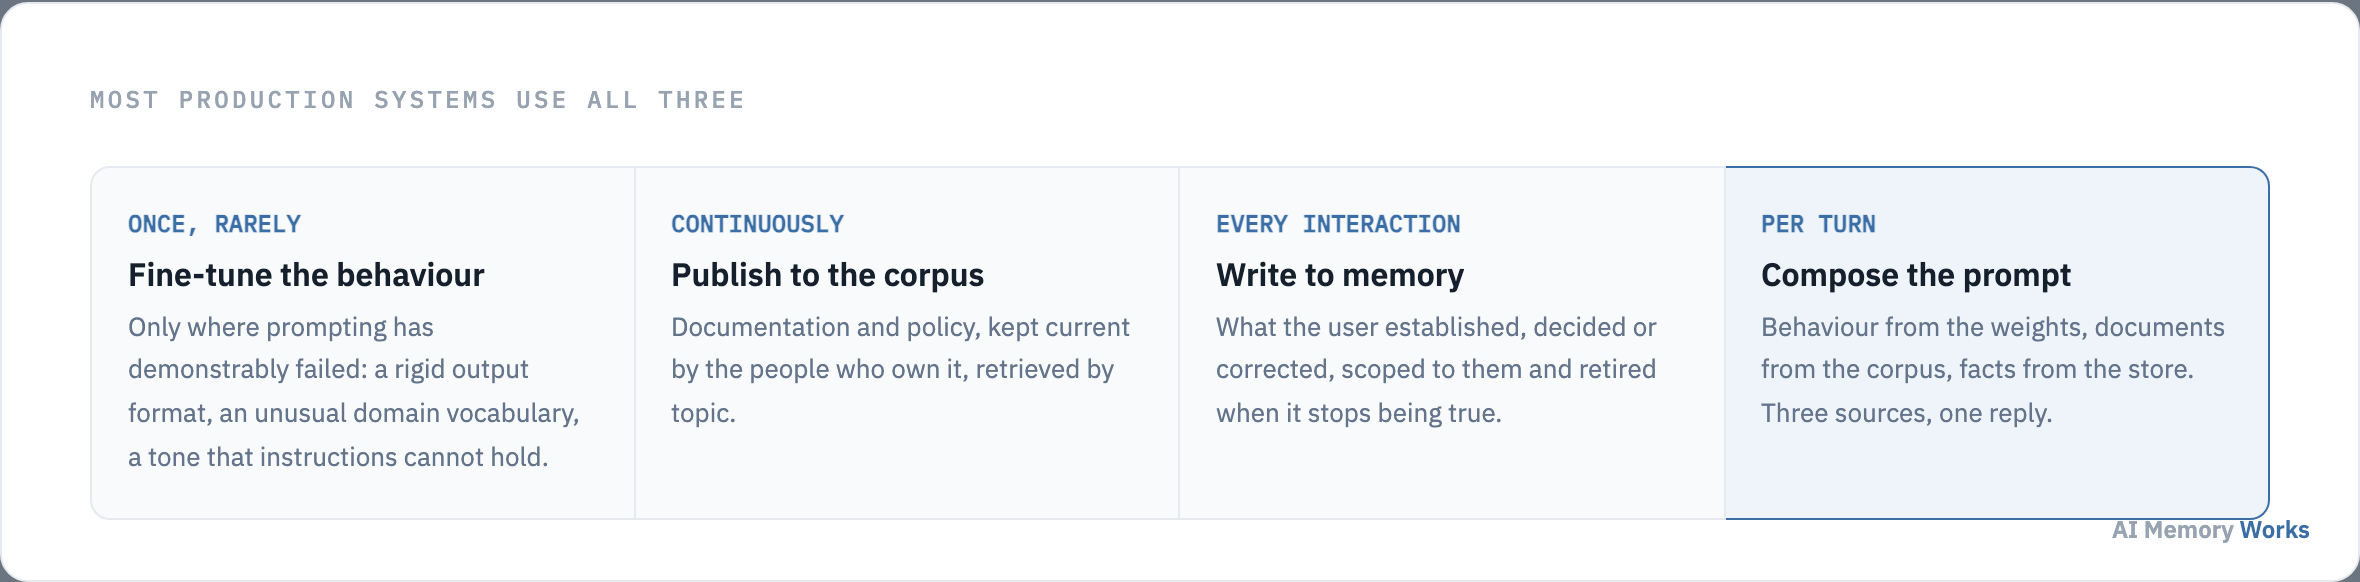
The sequencing matters. Fine-tuning last, not first: it is the least reversible and the most expensive to iterate on, and prompting plus retrieval solves enough of the problem that fine-tuning applied early is frequently spent on something that turns out not to be the constraint.
The layers also constrain each other in one useful way. Behaviour trained into the weights does not need restating in the prompt, which frees budget for retrieved memories. A model fine-tuned to produce a strict format can spend its context on facts rather than on format instructions.
One combination to avoid: fine-tuning on transcripts that contain user facts. It bakes those facts into shared weights, makes them undeletable, and produces exactly the personalisation problem described above in its least recoverable form. Train on the shape of good interactions, not on their contents.
Which leaves the decision itself, and it is simpler than the length of this page suggests: how to decide which one you need.
The decision
How do you decide which one you need?
Ask what kind of thing is missing. If the model does not know how to behave, that is fine-tuning. If it does not know what is documented, that is retrieval. If it does not know who it is talking to, that is memory.
Two follow-up questions settle the awkward cases. Does it change? Anything that can be contradicted tomorrow belongs in a store, because correcting weights is a deployment. Is it about one person? Anything true of one user and not the next belongs in memory by definition, since weights and corpora are both shared.
A practical sequence follows. Start with prompting, which is free and reveals what the actual gap is. Add retrieval when the gap is knowledge that exists in documents. Add memory when the gap is continuity across sessions. Fine-tune when what remains is behavioural and demonstrably resistant to instructions, which is a smaller residue than most teams expect.
The one warning sign worth naming: if you are considering fine-tuning so the model will remember something a user said, the answer is memory, and the cost of finding that out by building the training pipeline first is measured in months. The build path is on adding memory to an agent, and the comparison with the third option on memory versus RAG.
FAQ
Frequently asked questions
The questions that follow this comparison: adapters, hybrid setups and what to do about data you have already trained on.
Can LoRA adapters give each user their own memory?
Technically conceivable, practically not. Each user would need data collected, a training run, an adapter stored and loaded at inference, and even then nothing a user said this morning would be available this afternoon. A store handles all of it in one write.
Is fine-tuning cheaper than memory at high volume?
It can be, for behaviour. A smaller fine-tuned model matching a larger prompted one on a narrow task is a real saving, and behaviour in the weights shortens every prompt. That argument does not extend to facts, which still have to come from somewhere current.
Should you fine-tune on conversation transcripts?
Train on the shape of good interactions, not on their contents. Transcripts carry user facts, and baking those into shared weights makes them undeletable and available to every other caller.
Does RAG replace fine-tuning?
For knowledge, usually yes. For behaviour, no. A great many fine-tuning projects are attempts to make a model know a body of documentation, which retrieval does faster and keeps current. See retrieval-augmented generation.
How do you remove a fact from a fine-tuned model?
There is no clean way to unlearn one fact. The remedy is retraining without it, and even then no strong guarantee is available about what the model retained. This is the main reason changeable facts belong in a store.
Which should you build first?
Prompting, then retrieval, then memory, then fine-tuning last. Fine-tuning is the least reversible and the slowest to iterate on, and by the time the first three are in place the residue that genuinely needs it is small.