Compare · Memory structure
Vector vs Knowledge Graph Memory for AI Agents
Vector memory finds statements that resemble your question; graph memory follows the connections between the things those statements are about. Almost everything written on this comparison is published by a vendor of one of the two answers, so it arrives as a feature table with a conclusion attached. The useful version starts somewhere else: with which retrieval failure you are actually looking at.
Two questions
The difference
What is the difference between vector and knowledge graph memory?
What each one stores about the relationship between two memories. A vector store keeps memories as independent statements and measures how alike they are. A graph keeps the things memories are about as nodes and the relations between them as edges, so connections are recorded rather than inferred.
In a vector store, “Priya manages the platform team” and “Rahul reports to Priya” are two rows. They are related in the sense that both mention Priya, and a search for either may return the other because their embeddings are close. Nothing in the store states that these two facts compose into a third one.
In a graph, the same two statements become nodes for Priya, Rahul and the platform team, joined by typed edges. The composition is now something the store can execute: start at Rahul, follow the reporting edge, follow the management edge, arrive at the team. The answer was never written down and the structure produced it anyway.
That is the whole substantive difference, and everything else in the comparison follows from it. The stores themselves are covered on vector databases and knowledge graphs; this page is about which structure your memory should have.
Before choosing, it is worth being precise about the problem you are solving, because two of the three common complaints about memory are not structure problems at all: which retrieval failure you are actually trying to fix.
Diagnosis
Which retrieval failure are you actually trying to fix?
Three different things go wrong with agent memory and only one of them is answered by changing the structure. Teams reach for a graph on the strength of a complaint that a graph does not address, which is how a rebuild ends with the same symptom.
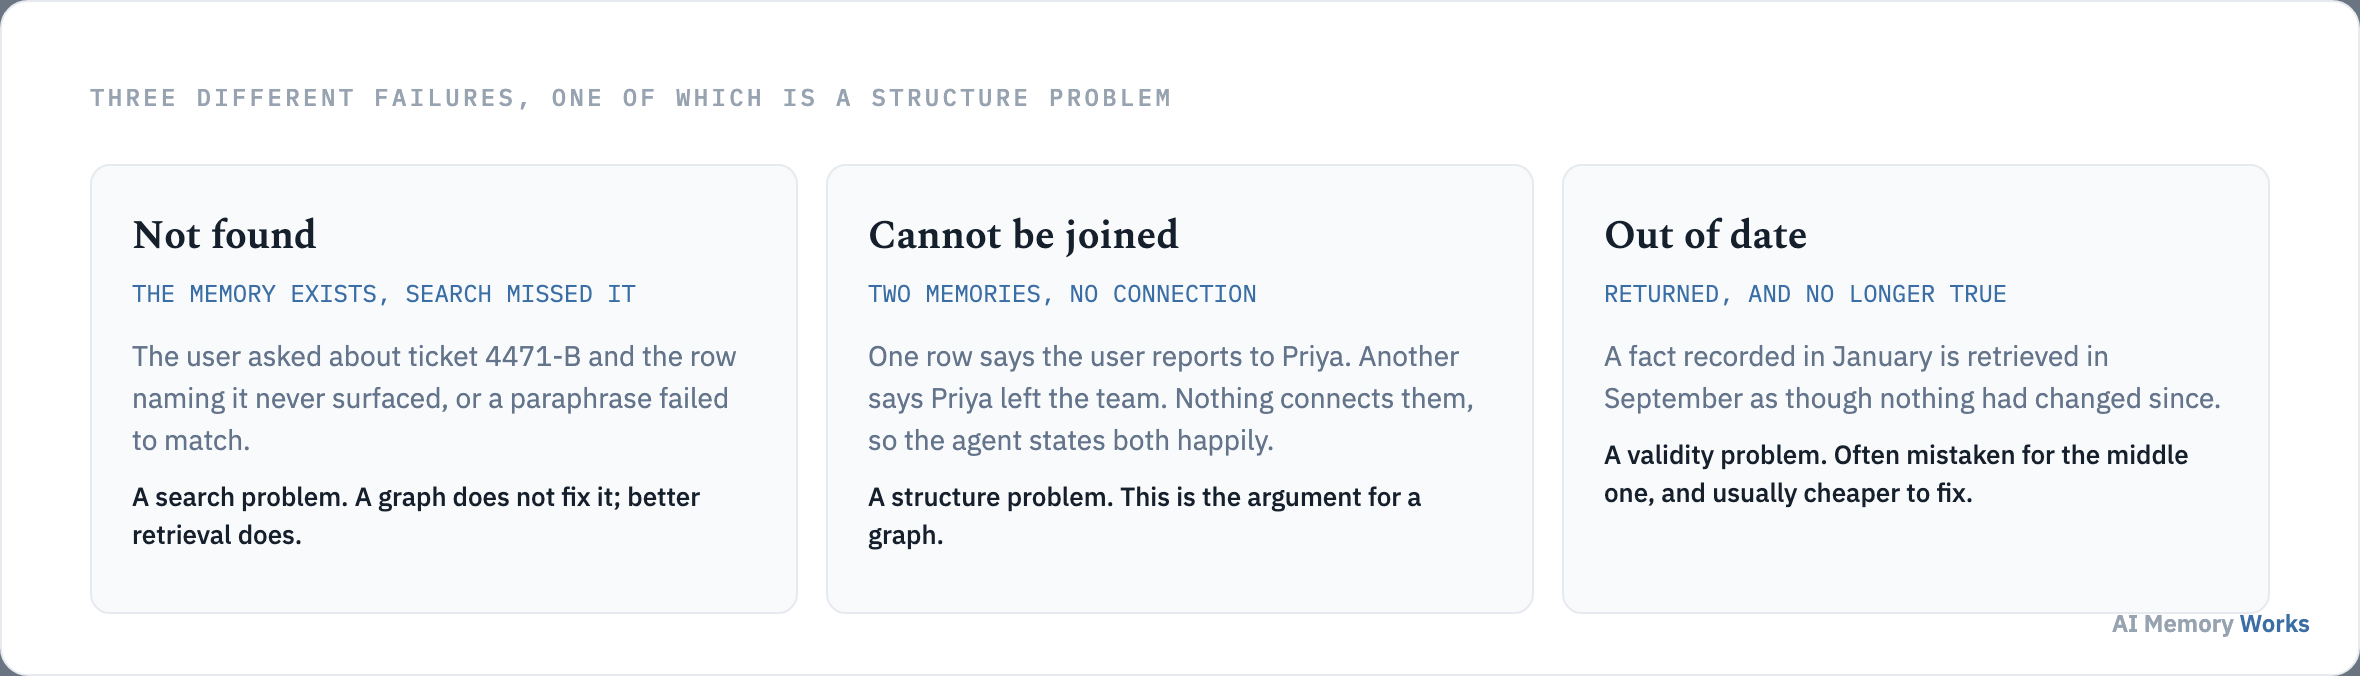
The memory exists and was not returned. This is a search problem. The usual causes are an exact string the embedding handles badly, a paraphrase with no shared vocabulary, or a filter applied in the wrong order. A graph does not fix any of them, and the actual fix is on hybrid search for agent memory.
Two memories were returned and could not be combined. This is a structure problem, and it is the honest case for a graph. The agent has the pieces and no way to compose them, so it either states both facts side by side or picks whichever ranked higher.
The memory was returned and is no longer true. This is a validity problem. It feels like a structure problem because a graph can carry validity intervals on edges, but you do not need a graph to expire a row, and adopting one for this reason means paying for traversal you will not use. The cheaper fix is on conflicting memories and forgetting and eviction.
If your complaint is genuinely the middle one, the next question is what kind of memory question produces it: which memory questions need a graph to answer.
The case for a graph
Which memory questions need a graph to answer?
Questions whose answer was never stored as a statement and has to be assembled by following connections. There are two families, and they look different enough that a system can need one without the other.
Multi-hop questions. “Which of this customer’s teams are affected by the outage in the billing service?” is answerable only by traversing from the customer to their teams to the systems those teams depend on. No single memory says it. A similarity search returns memories about the customer, memories about billing, and no route between them, which is why the agent’s answer looks confident and incomplete at the same time.
Questions where the connection itself changed. A person moves teams, an account changes owner, a service is deprecated in favour of another. Structure holds the change as an edge with a beginning and an end, so the store can answer what was true in March as distinct from what is true now. Statements in a vector store carry no such structure by default, so the old fact and the new one sit side by side with equal standing.
This second family is what makes agent memory different from document retrieval. A corpus of documents is mostly static, and memory is a moving record of a world where people change jobs and preferences change with them. That difference is treated on memory versus RAG.
The temptation at this point is to conclude that agent memory is a graph problem in general. The published evidence is more modest than the argument: what the evidence says about graph memory.
Evidence
What does the published evidence say about graph memory?
One published study runs the same pipeline with and without a graph on the same benchmark, and it reports a gain of 1.5 points at roughly three times the search latency and twice the context. The figures come from the research introducing Mem0 (Chhikara et al., 2025). That is the honest state of the evidence, and it is neither the endorsement nor the dismissal the marketing on both sides suggests.
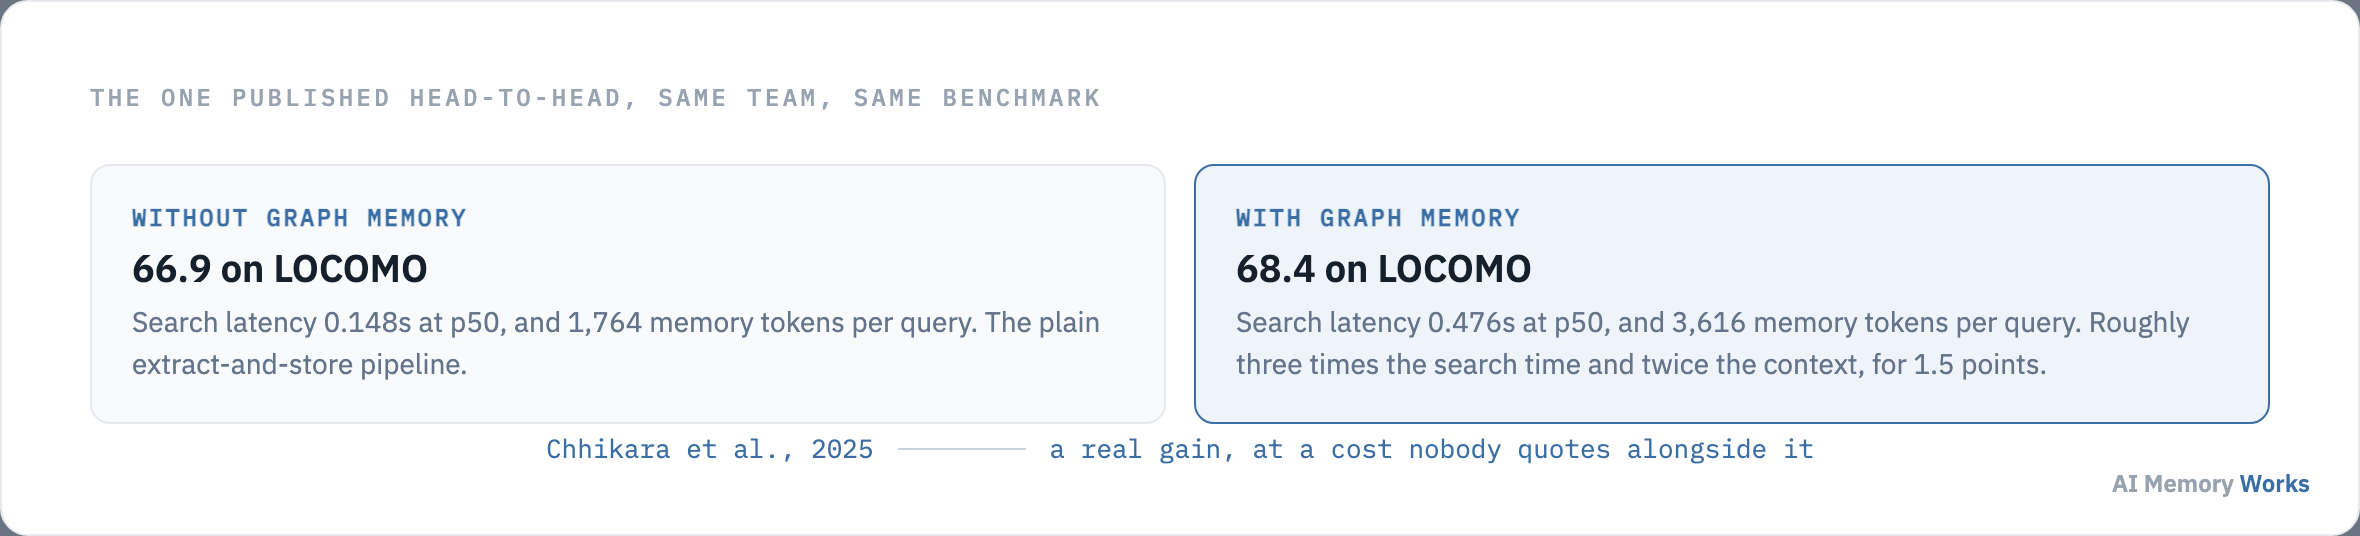
The numbers are worth stating plainly: 66.9 on the LOCOMO judge score without graph memory and 68.4 with it, search latency rising from 0.148 to 0.476 seconds at the median, and memory tokens per query rising from 1,764 to 3,616. The benchmark is described on the LOCOMO benchmark.
Three caveats belong with the figure. The paper is published by the authors of the system being measured, which is the normal situation in this field and is covered on how to evaluate agent memory. LOCOMO is built from long conversations rather than from a connected domain of entities, so it is close to the weakest case for a graph. And a 1.5 point gain on a judged benchmark is within the range where implementation quality plausibly matters more than architecture.
Read together, they argue for the same conclusion as the diagnosis section. A graph is not a general improvement to memory quality that you buy with latency. It is a way of answering questions that require composition, and if your workload does not ask those questions the benchmark gain is not what you will get.
The latency in that table is also only half the price, and the other half is paid somewhere the benchmarks do not look: what a graph costs that a vector store does not.
The real price
What does a graph cost that a vector store does not?
A write path with three extra steps, each of which can fail quietly. The read side gets all the attention in this comparison, and the write side is where graph memory projects actually come apart.
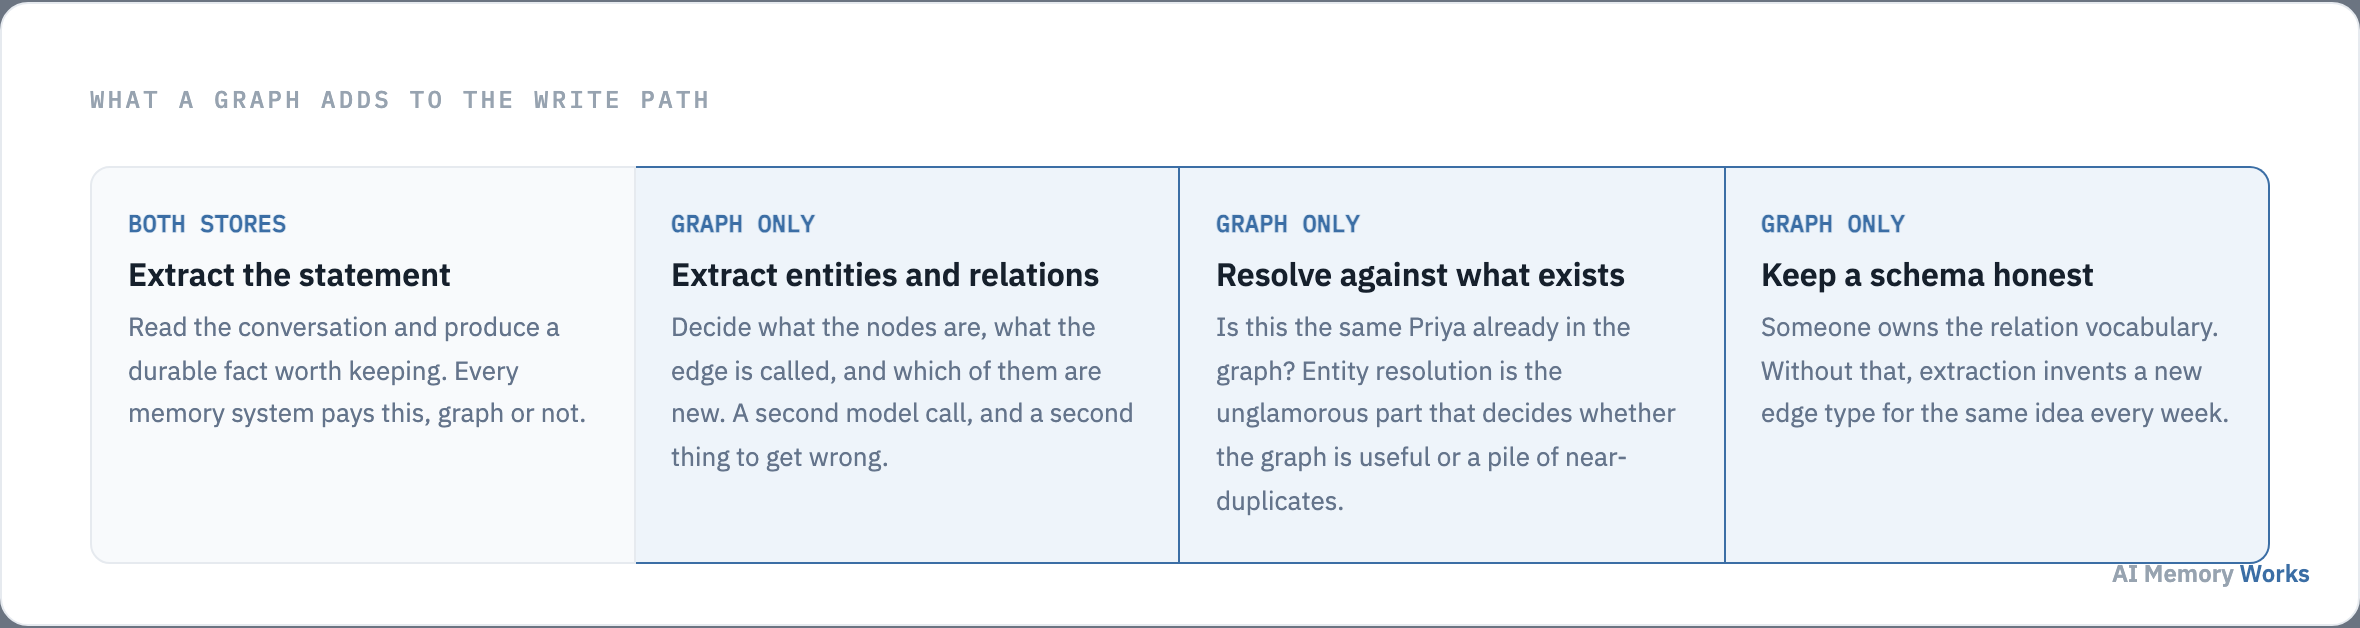
Entity and relation extraction. A vector store accepts the statement your extraction step already produced. A graph needs that statement decomposed into nodes and typed edges, which is a second model call with its own error rate. The general write path is on how agents write and store memories.
Entity resolution. Is this Priya the Priya already in the graph? Get it wrong in one direction and the graph fills with duplicate people whose facts never meet; get it wrong in the other and two people merge into one, which is worse, because now the agent confidently states things about the wrong person. Nothing about this problem is new and nothing about it is easy.
Schema maintenance. Someone owns the vocabulary of relations. Without that, extraction invents “manages”, “is manager of” and “leads” for the same idea in three consecutive weeks, and traversals silently miss two thirds of the edges they should follow.
There is a fourth cost that shows up only later. A wrong row in a vector store is one bad memory that may surface occasionally. A wrong edge in a graph propagates: every traversal through it inherits the error, so a single bad extraction can produce a family of confident wrong answers. Auditing for that is harder than auditing rows.
Set against those costs, the reasonable next question is how much of your workload really needs them: when vectors are enough on their own.
The common case
When are vectors enough on their own?
When the memories are statements about one subject and the questions are lookups rather than traversals. That describes most agent memory in production, which is why the simpler store remains the right default.
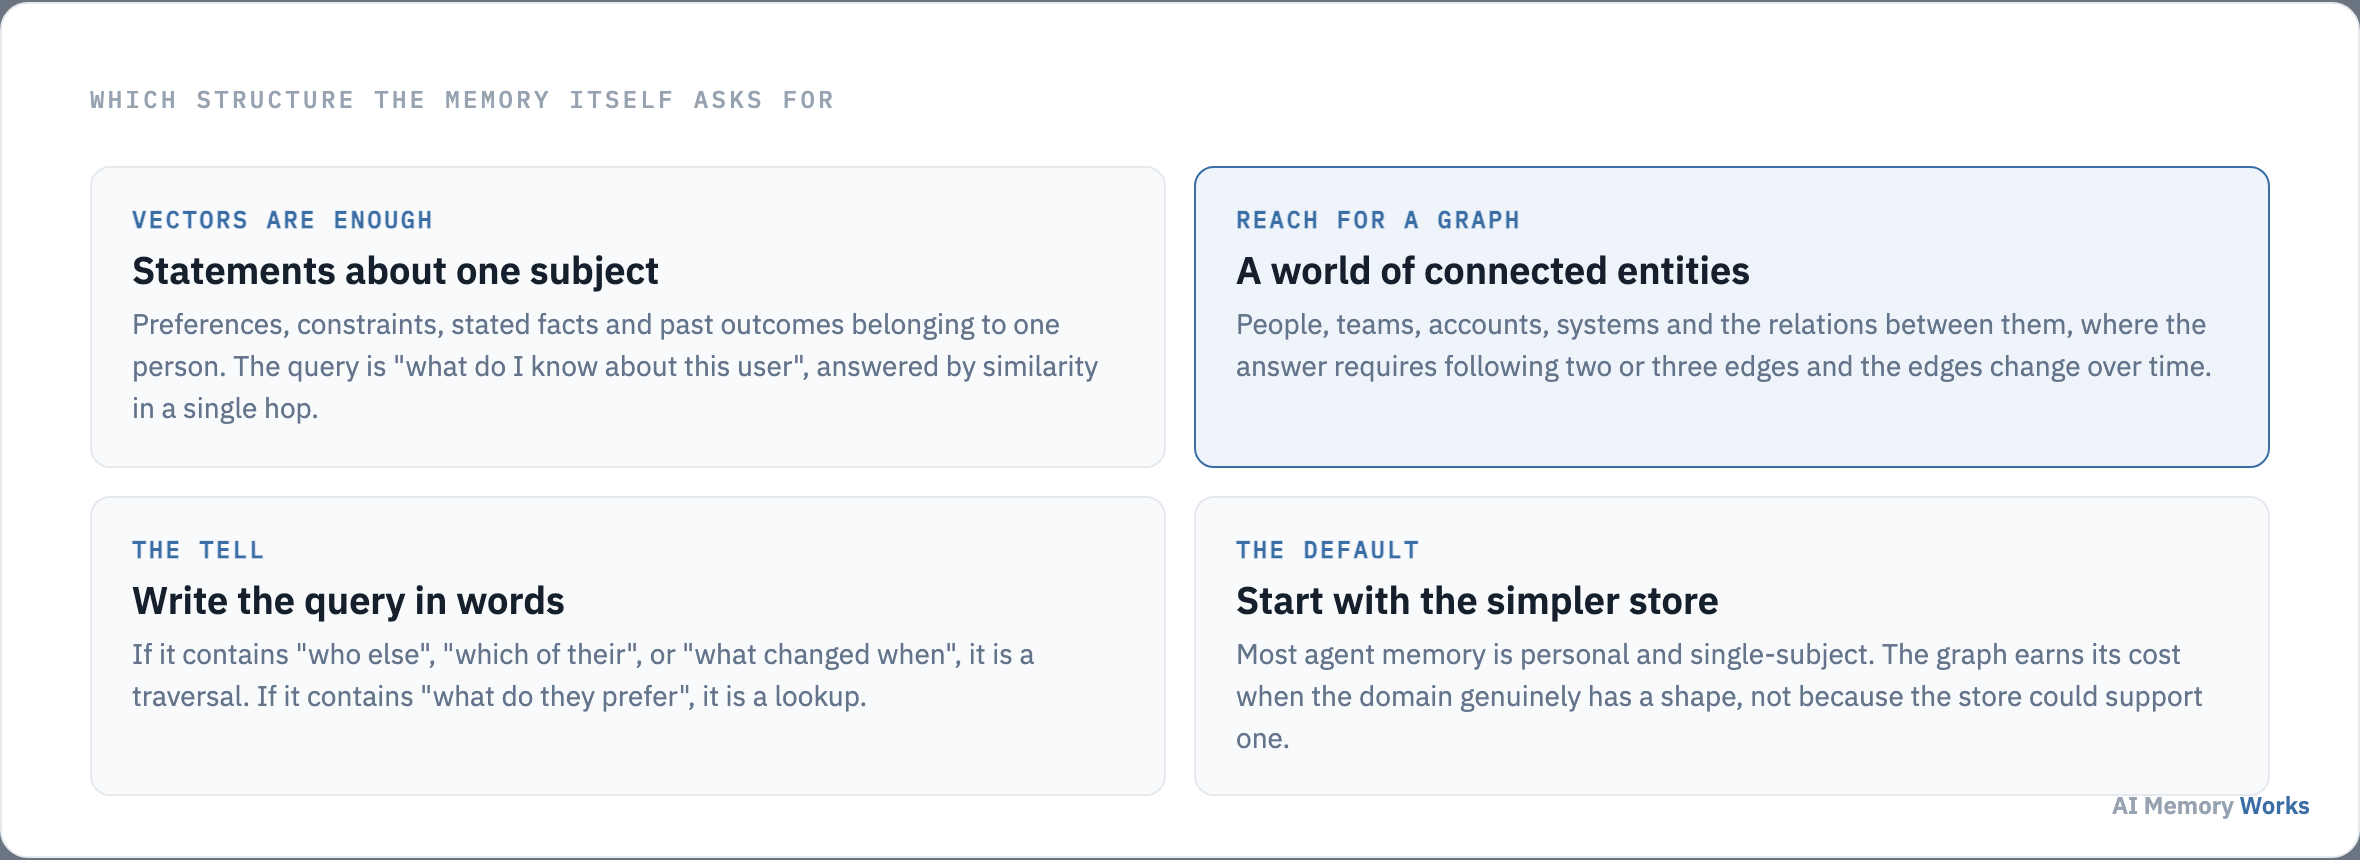
A personal assistant remembering dietary requirements, travel preferences and how someone likes to be addressed has a store of statements about one person. Every question is answered in one hop. Building a graph over that data produces a star with a single centre, which is a more expensive way to store a list.
A support agent recalling a customer’s plan, their previous tickets and what resolved them is in the same position more often than not, though this is the case that tips first, because customers belong to organisations and tickets touch systems. The use case is on memory for customer support agents.
The plain test is to write down the three questions your agent most needs answered from memory, in the words a user would use. If they contain “who else”, “which of their” or “what changed when”, they are traversals. If they read as “what do they prefer” or “what happened last time”, they are lookups, and a vector store with good retrieval will serve them.
Answering “some of each” is the common outcome, and it is a legitimate one rather than a failure to decide: whether you can use both, and how to route between them.
Both
Can you use both, and how do you route between them?
Yes, and the interesting question is not whether to combine them but what decides which one answers a given query. Every source that recommends both stops at the recommendation, which is where the design work starts.
Three routing strategies are workable. Route on the query, sending anything that names two entities or asks for a relation to the graph and everything else to the vector search, which is cheap and gets most cases right. Query both and fuse, treating the graph as a third retriever alongside vector and keyword search, with the fusion mechanics on hybrid search. Search then traverse, using vector search to find the entry point and the graph to expand from it, which is the pattern most graph-backed memory systems actually implement.
The third is worth understanding because it changes what you need from each store. The vector index only has to find a starting node, not the complete answer, so recall matters more than precision at that step. The graph only has to expand locally, so the traversals stay shallow and fast.
It is also worth distinguishing this from GraphRAG, which builds a graph over a document corpus to improve retrieval and summarisation over documents. The technique is related and the subject is not: agent memory records a moving account of interactions rather than a fixed corpus. The comparison of graph memory tools is on memory frameworks and tools.
The video below is the walkthrough that ranks for this comparison, covering the two stores from the database side.
Which leaves the practical worry that stops teams committing either way: how to decide without building it twice.
The decision
How do you decide without building it twice?
Keep the statements as the source of truth, and treat any graph as something derived from them. That single decision makes the choice reversible, which matters more than making it correctly the first time.
Memories written as durable statements with their provenance can be re-extracted into a graph later, with a better prompt and a schema informed by a year of watching what people actually ask. The reverse is not true in any pleasant way: a graph built directly from conversations, with the original statements discarded, cannot be flattened back into the memories you would have written.
Two practical steps follow. Instrument the failures before changing the store, counting how often the agent has the pieces and cannot compose them, because that number is the entire case for a graph and most teams have never measured it. And if you do adopt one, adopt it for a defined slice of the domain, typically the organisational structure or the product catalogue, rather than for everything a user has ever said.
On tooling, the choice is less binding than it appears. Engram runs on Weaviate, where vector and keyword retrieval are fused natively, which covers the lookup case well and leaves a graph as a later addition. Dedicated graph stores and the memory frameworks built on them are surveyed on AI agent memory frameworks and tools, with the storage decision itself on storage backends.
Whichever structure you land on, retrieval quality is decided upstream of it, by what was written and how it is searched, covered on how agents retrieve memories.
FAQ
Frequently asked questions
The questions that come up once the two structures are clear and a decision has to be made with real data.
Is a knowledge graph better than vector search for agent memory?
Not in general. It is better at questions that require composing several stored facts, and worse on cost, write complexity and latency. If your agent's questions are lookups about one person, a graph adds expense without adding answers.
Do you need a dedicated graph database?
Not necessarily at memory scale. Relations can be modelled in a relational database and traversed with joins for a few thousand rows per user, which is often simpler to run than adding another system. A dedicated store earns its place when traversals get deep or the graph gets large.
Is GraphRAG the same as graph memory?
No. GraphRAG builds a graph over a document corpus to improve retrieval and summarisation of documents. Graph memory records entities and relations learned from interactions, which change over time. The technique overlaps; the data does not.
Can you convert a vector memory store into a graph later?
Yes, provided you kept the statements. Extraction can be run again over durable memories to produce nodes and edges. This is the main argument for keeping written statements as the source of truth rather than building the graph directly from conversations.
Does a graph solve the problem of outdated memories?
It gives you somewhere natural to record when a relation started and ended, which helps. It does not decide that a fact is stale, and that decision is the actual work. A vector store with expiry and supersession handles the same problem without traversal.
Which is faster to query?
Vector search, in the one published comparison that ran both: 0.148 seconds at the median without graph memory and 0.476 with it (Chhikara et al., 2025). Shallow traversals are fast in absolute terms, so the difference matters mainly because retrieval sits in front of every reply.