Memory types · Comparison
Short-Term vs Long-Term Memory in AI Agents
Short-term memory is what an agent is holding right now and loses when the session ends; long-term memory is what it wrote down somewhere else and can retrieve months later. Every explanation of agent memory says that much. The part that decides whether your agent works is the next question, which is where a given piece of information belongs, and that is what this page answers.
One turn
The distinction
What is the difference between short-term and long-term memory in AI agents?
The lifetime and the key. Short-term memory lives inside one session and is addressed by that session; long-term memory lives in a store outside the model and is addressed by the person or agent it belongs to.
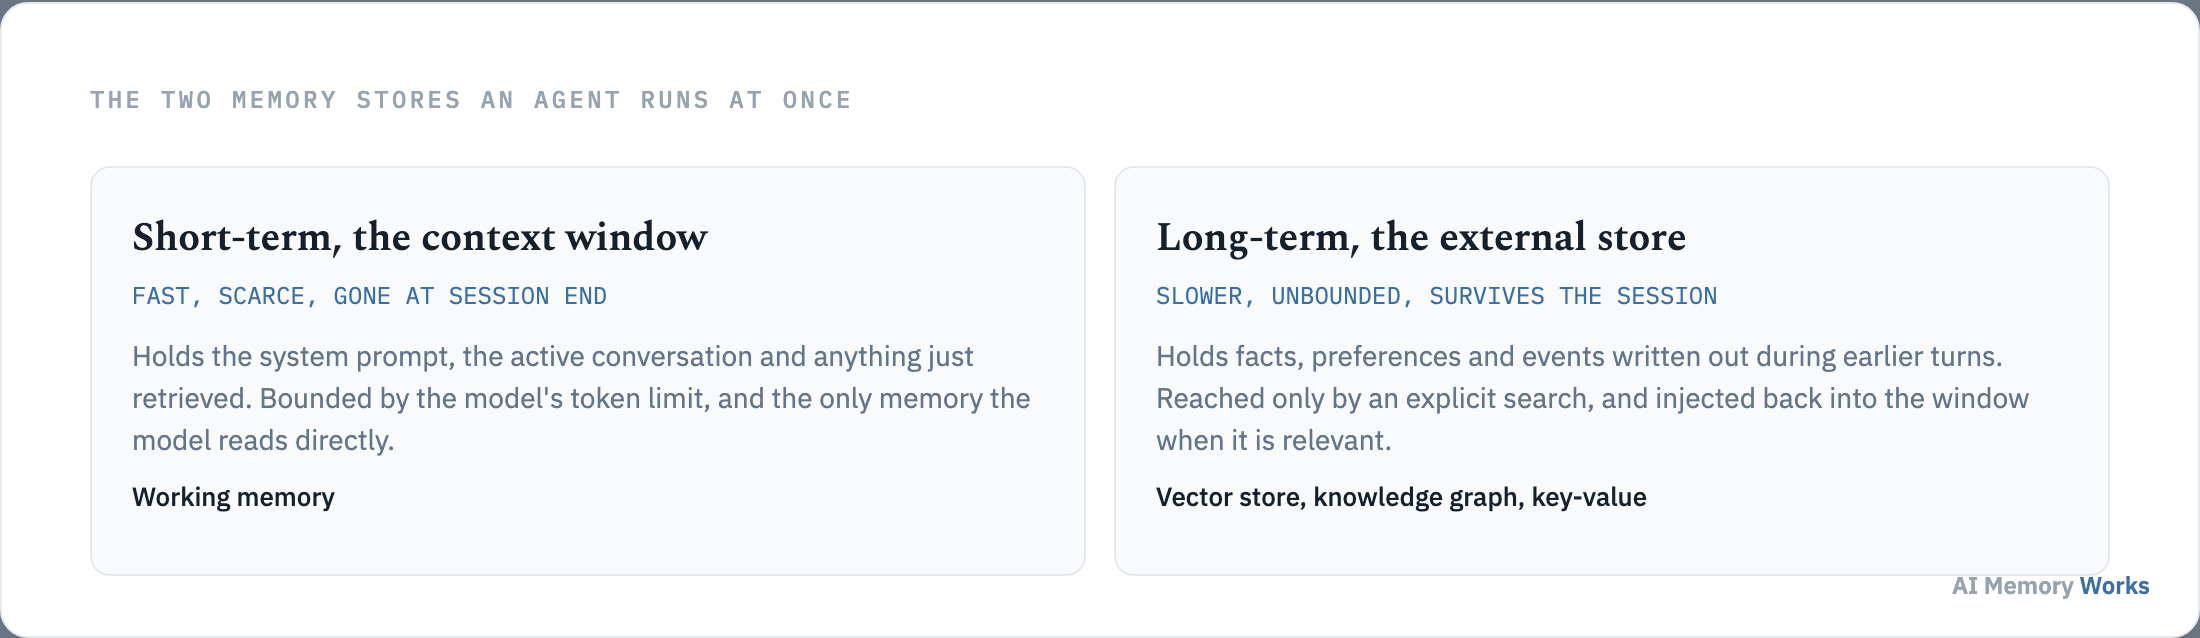
Everything else follows from those two properties. Short-term memory is fast because the model is already reading it, small because the context window is finite, and complete because nothing has been selected out of it yet. Long-term memory is slower because it has to be searched, effectively unbounded because it is a database, and lossy by design because something decided what was worth keeping.
The framing that causes trouble is treating these as two stages of one pipeline, where everything eventually graduates from one to the other. They are two stores with different jobs, running at the same time, and most information belongs in exactly one of them permanently.
Which makes the concrete question worth taking slowly, starting with what is actually in the first store: what counts as short-term memory in an agent.
The near store
What counts as short-term memory in an agent?
Everything currently in the prompt, plus whatever the framework will put back into the prompt when this same conversation resumes. That is a wider set than the phrase suggests, and it includes several things teams assume are long-term.
Concretely: the system prompt, the messages exchanged so far, the results returned by tools during this task, the running plan or scratchpad an agent keeps while working, and any rolling summary that stands in for turns already dropped. All of it is either in the window now or reassembled into it on the next turn of this conversation.
Saved session state belongs here too, which is the part that surprises people. A framework that writes conversation state to a database so a chat can be resumed tomorrow has made short-term memory durable; it has not made it long-term memory. The key is still the conversation, so nothing in it is reachable from a different one.
The constraint that shapes all of this is the size of the window and what happens as it fills, treated on memory versus the context window. The tier itself has its own page: short-term memory in AI agents.
The second store is defined by what it can do that this one cannot: what counts as long-term memory.
The far store
What counts as long-term memory?
Statements written to a store outside the model, keyed by who they are about rather than by where they were said, and retrievable from any future conversation. The test is that last clause: if a new conversation cannot find it, it is not long-term memory regardless of how durably it was saved.
What ends up there is narrower than a transcript and broader than a preference list. Stable facts about a person, the decisions they have made and the reasons given, outcomes of past work worth not repeating, and behavioural rules the agent has been asked to follow. The categories these fall into are covered on the types of AI agent memory, and the tier in depth on long-term memory.
Long-term memory is lossy on purpose. Something read the conversation and kept four statements out of forty turns, which is what makes the store searchable later. A system that keeps everything has traded a retrieval problem it could solve for one it cannot.
It is also mutable in a way short-term memory never has to be. A fact stored in January can be wrong by March, so the store needs a way to supersede it, which is a whole problem of its own on conflicting memories.
With both tiers defined, the case that sits awkwardly between them is worth settling, because almost every team has one: whether a saved chat history is short-term or long-term memory.
The awkward case
Is a saved chat history short-term or long-term memory?
It is short-term memory that happens to be stored durably, and treating it as long-term memory is why many teams who save everything still have an agent that remembers nothing. The storage is real. The recall is not.
The reason is that a transcript is keyed and shaped for the wrong job. It is organised by conversation, so a question asked in a new conversation has nowhere to look. It is written in the language of an exchange rather than the language of a fact, so a search for “dietary requirements” does not match “no, I can’t do the cheese one either”. And it contains everything, so even a search that hits the right conversation returns forty turns of context to sift.
This matters because saving transcripts is the easiest thing to build and it produces a convincing artefact. Rows accumulate, storage costs appear, dashboards show growth, and none of it makes the agent remember. The work that would is the selection step, covered on how agents write and store memories.
Transcripts are still worth keeping for other reasons, including audit, evaluation and the ability to re-extract memories later with a better prompt. Keep them as what they are, and build the memory store separately. The implementation of the first half is on persisting conversation memory.
Which brings the general question into focus, since every piece of information a system holds needs the same decision made about it: which tier a given piece of information belongs in.
The decision
Which tier does a given piece of information belong in?
Four questions settle almost every case, and none of them is about your framework. The tier is a property of the information, so this decision is worth making before choosing any tool.
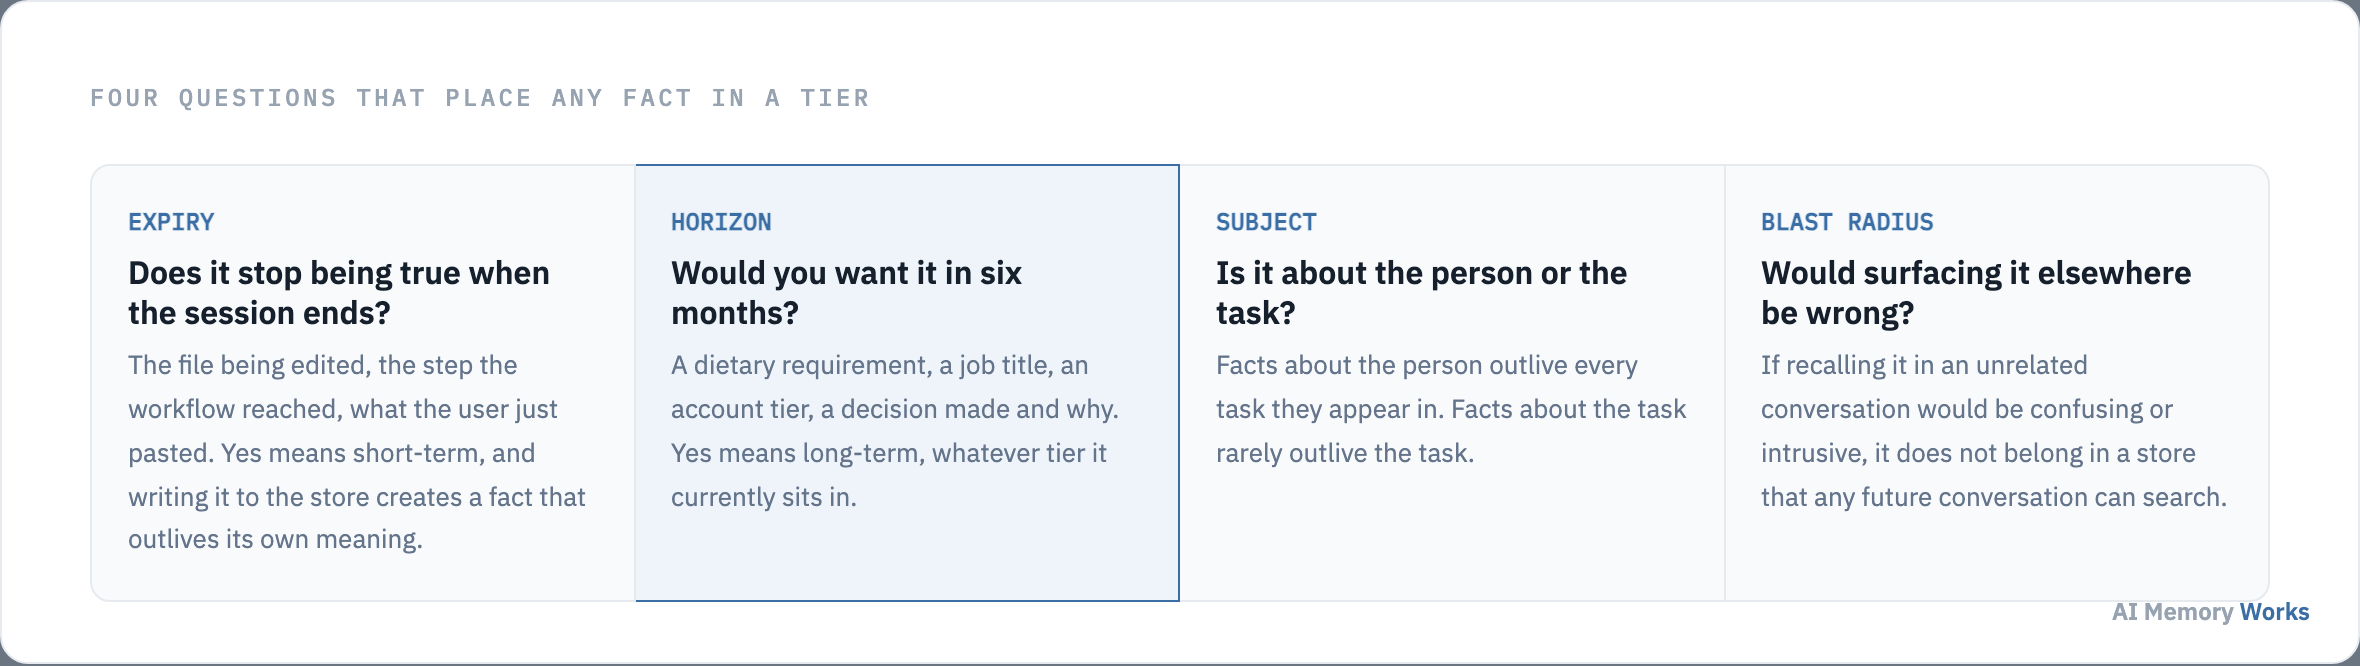
Does it stop being true when the session ends? The file open in the editor, the step the workflow reached, the draft being revised. These are true of a moment, and a store that records them accumulates statements that were accurate once and are misleading forever.
Would you want it in six months? A stated preference, a constraint, a job title, a decision and its reasoning. If the answer is yes, it needs to leave the session, and if nothing is doing that today then the agent is losing it every time a conversation closes.
Is it about the person or about the task? Facts about a person outlive every task they came up in. Facts about a task rarely outlive the task, with one exception worth carving out: the outcome. That an approach was tried and failed is about the person’s work and worth keeping, even though everything else about that session is not.
Would surfacing it in an unrelated conversation be wrong? Some things a user says in one context should not be volunteered in another, which is a scope decision rather than a storage one and is treated on memory security and privacy.
Cost breaks any remaining tie. Short-term memory costs tokens on every turn it stays in the window, and long-term memory costs a retrieval and the storage behind it. A fact used in most conversations is cheaper injected once from the store than carried in every window; the token side is covered on reducing token cost with memory.
Once you know something belongs in the far store, something has to actually put it there: how information moves from short-term into long-term memory.
The boundary
How does something move from short-term into long-term memory?
A selection step reads the conversation and writes a few statements out of it, and that step is the entire difference between a memory system and a backup. Nothing crosses the boundary on its own.
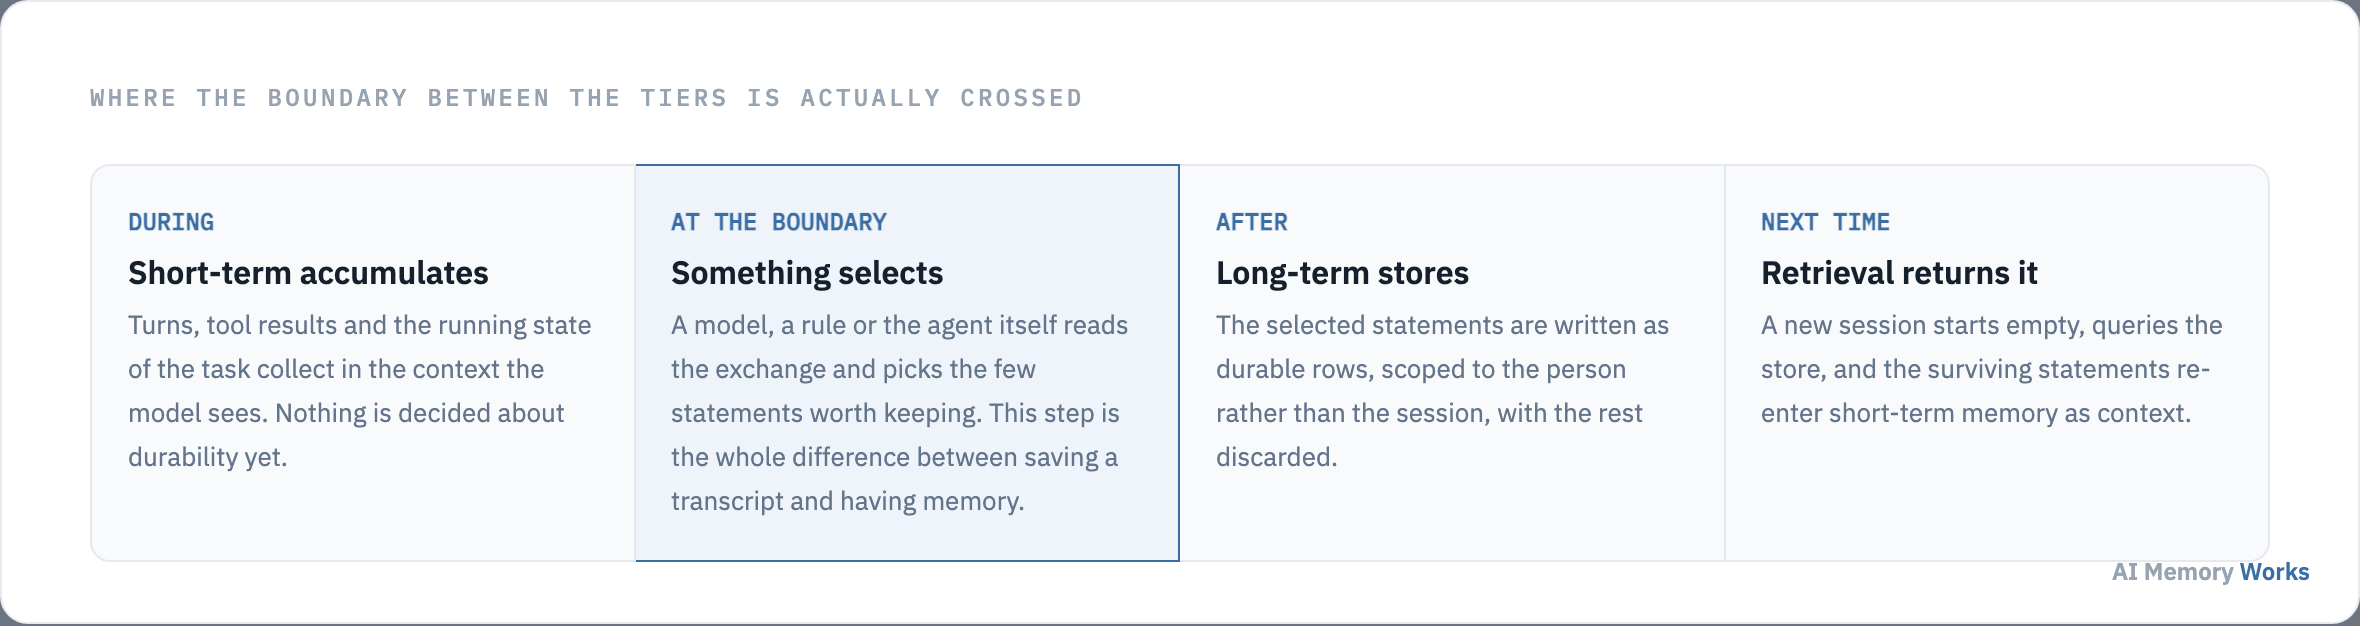
Three things vary between implementations. Who selects: a model asked to extract durable statements, a rule that promotes anything matching a pattern, or the agent itself calling a tool when it judges something worth keeping. When: during the turn, at the end of a turn, or after the conversation goes quiet, which keeps the work off the path the user is waiting on. What form: a rewritten atomic statement, which is retrievable, rather than a copied turn, which is not.
Two properties are worth insisting on regardless of implementation. The statement should stand alone, because it will be read months later with none of its surrounding conversation. And it should carry where it came from, so a memory that turns out to be wrong can be traced to the exchange that produced it.
Promotion is also where duplication is either prevented or created. The same preference restated across five sessions becomes five near-identical rows unless the write path checks first, which is a write-time fix for a problem that otherwise shows up as bad retrieval. Both halves are on writing memories and memory consolidation.
Crossing in the other direction happens on every turn, and it is worth walking through once end to end: how the two tiers work together on a single turn.
The loop
How do the two tiers work together on a single turn?
The far store is read at the start, the near store does the work, and the far store is written at the end. Stated as a sequence it is unremarkable, which is useful, because most memory bugs are one of these four steps missing rather than anything subtle.
Retrieve. The incoming message is used to search the store, and a handful of relevant memories come back. Not everything about the user, which would defeat the purpose, but what this message calls for. The read path is on how agents retrieve memories.
Assemble. Those memories are placed into the window alongside the system prompt and the recent turns. This is where a budget has to exist, because the retrieved memories, the conversation and the tool results are all competing for the same finite space.
Reason and act. The model works with what it can see. Anything not retrieved at step one is invisible now, which is why retrieval quality and not storage capacity is the usual limit on how well an agent remembers.
Select and write. After the reply, or after the conversation, the selection step from the previous section decides what survives. If this step does not exist, the loop is open and every session starts from nothing.
Frameworks implement the same four steps with different names, and the two-layer split shows up explicitly in most of them, most visibly in the LangChain ecosystem where the two layers are separate objects entirely: LangMem. The wider survey is on AI agent memory frameworks and tools.
Knowing the loop makes the failures legible, and they come in two directions rather than one: what goes wrong when the tiers are mixed up.
Failure modes
What goes wrong when the two are mixed up?
Durable facts left in short-term memory produce an agent that forgets you; session state written into long-term memory produces one that misremembers you. The first is well known. The second is just as common and much harder to notice, because nothing appears broken at the time.
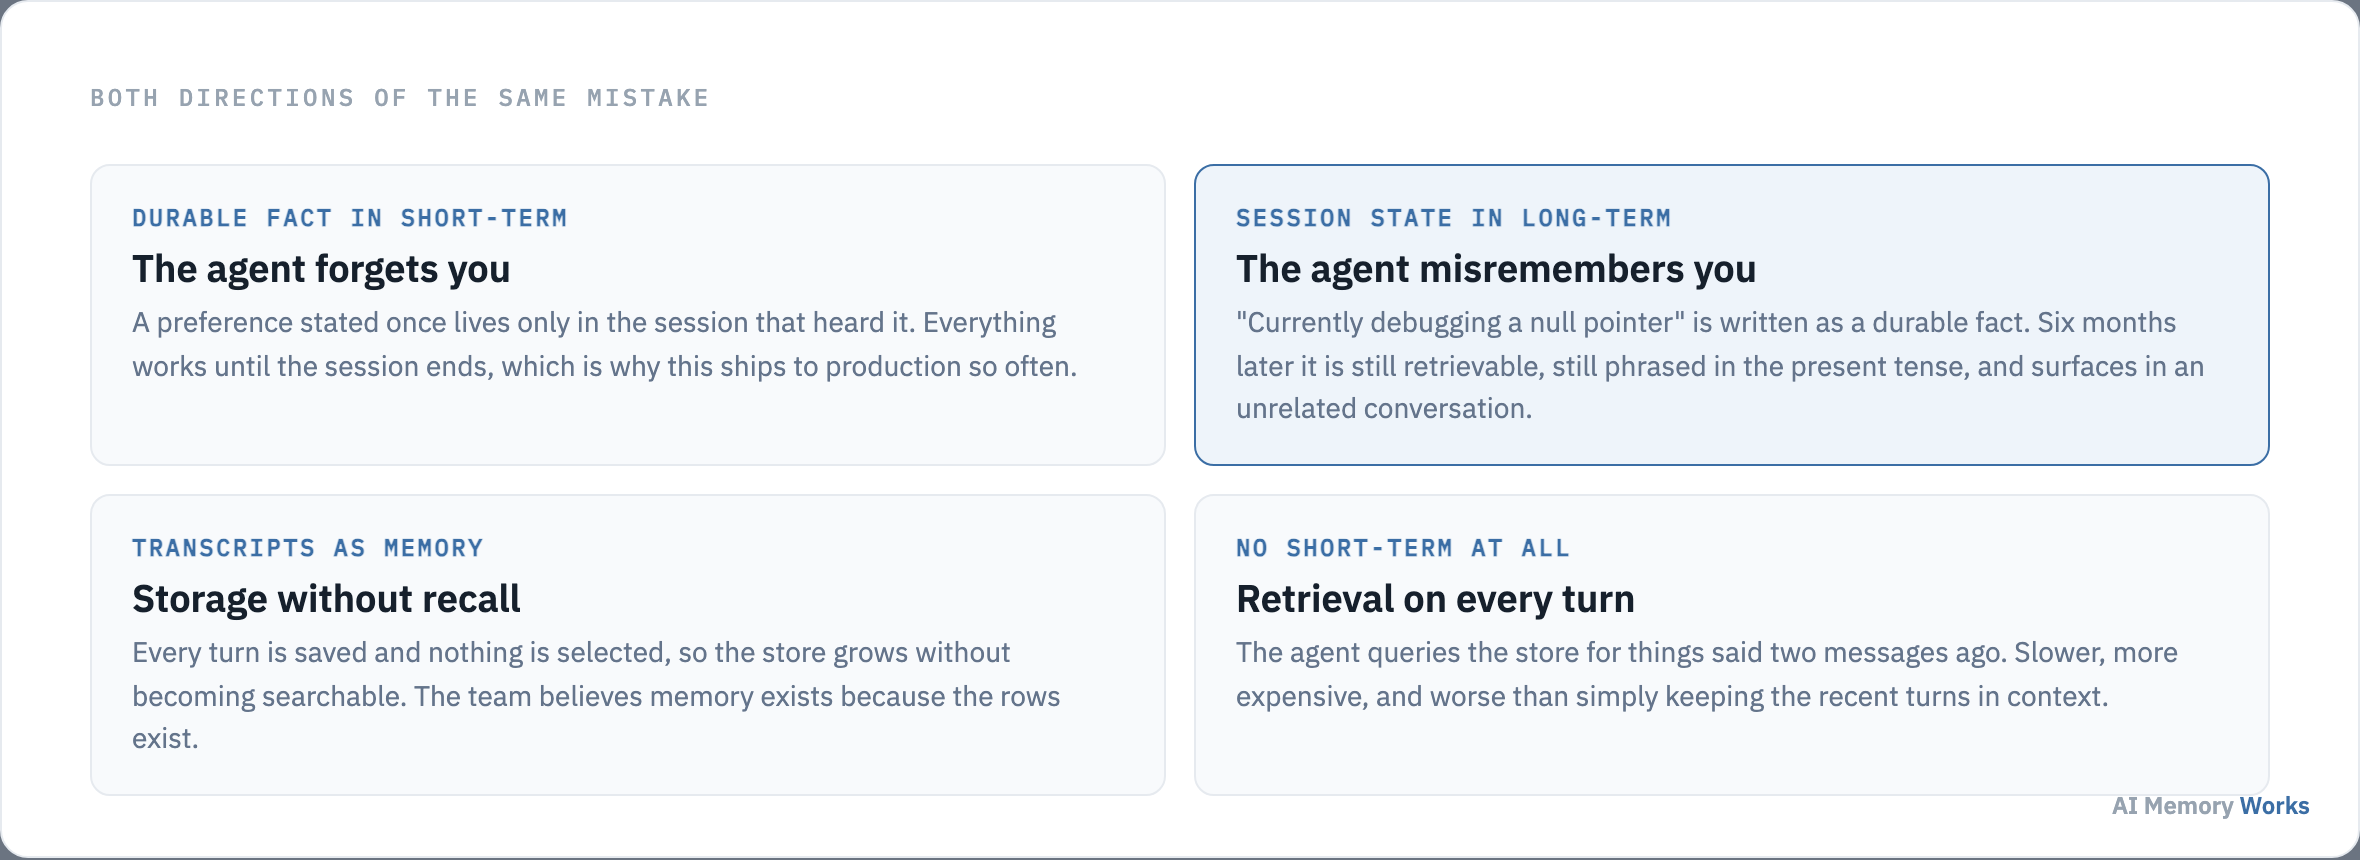
The second failure deserves the attention the first one gets. A statement like “the user is currently debugging a null pointer in the payment service” is true when written and stored in the present tense forever. Months later it is still retrievable, still phrased as if it were happening, and it surfaces in a conversation about something else entirely. The user experiences an agent that has confused them with an old version of themselves.
It is hard to catch because it passes every check a team is likely to run. The write succeeded, the retrieval works, the memory is relevant by similarity, and the fact was accurate when recorded. Only time makes it wrong, and nothing in the system measures time. The countermeasures are expiry and supersession, covered on forgetting and eviction.
The fourth failure in the figure is the opposite extreme and worth naming because it is presented as sophistication. An agent that searches its store for something said two messages ago is slower, more expensive and less accurate than one that simply kept the recent turns in its window. Recent context is not a retrieval problem.
All four are arguments for using both tiers deliberately, which raises the question of whether both are always required: whether every agent needs both.
Scope
Does every agent need both tiers?
Every agent has short-term memory whether or not it was designed; long-term memory is a decision, and for a real class of applications the right answer is not to build it. Short-term memory is not optional because the context window is not optional.
Three cases genuinely do not need the second tier. An agent that answers self-contained questions with no relationship to a user, where nothing from one exchange informs the next. A workflow that runs once against structured input and finishes, where the durable record belongs in the application’s own database rather than in a memory store. And any product whose users would be uncomfortable being remembered, where the absence of long-term memory is a feature to state rather than a gap to fill.
Everything else needs both, and the ordering matters. Short-term handling comes first, because an agent that mismanages the window fails immediately, whereas one with no long-term memory merely disappoints slowly. Get summarisation and the token budget right, then add the store. The build order is on building long-term memory for an agent.
Framework support is not the deciding factor here either. The common frameworks all provide both layers, and which one you pick changes the API rather than the design. If a comparison is what you need next, the neutral survey is on memory frameworks and tools and the head-to-head on the best AI memory tools.
The video below is the walkthrough that ranks for this comparison, and it covers the same two-tier split from the implementation side.
FAQ
Frequently asked questions
The edge cases that come up once the two tiers are clear and real data has to be sorted between them.
Is a summary of the conversation short-term or long-term memory?
Short-term. A rolling summary exists to stand in for turns that no longer fit the window, so it belongs to the conversation that produced it and disappears with it. A summary written at the end of a session and stored under the user, so a later conversation can find it, has crossed into long-term memory.
Where does a user's current task belong?
Short-term, with one exception. The state of the task is true of a moment and should expire with it. The outcome, that an approach was tried and worked or failed, is worth keeping, because it stops the same ground being covered again months later.
Can long-term memory replace the context window?
No. Retrieved memories are placed into the window to be used, so long-term memory feeds the window rather than substituting for it. An agent with a perfect store and no room to put anything in the prompt has the same problem as one with no store at all.
How long should something stay in short-term memory?
As long as the conversation needs it and no longer. The practical rule is that recent turns stay whole, older turns are summarised, and anything worth surviving the session is written to the store before it is dropped rather than being kept in the window to protect it.
Does a bigger context window remove the need for long-term memory?
It moves the boundary without removing it, because a window covers one conversation however large it is and long-term memory exists to cross between conversations. The full argument is on long context versus memory.
Should short-term and long-term memory use the same database?
They can, and at small scale one database serving both is simpler to run. They are still two logical stores with different keys, different lifetimes and different access patterns, and collapsing that distinction in the schema is how session state ends up retrievable forever.