Architecture · Retrieval
How Does Memory Retrieval Work in AI Agents?
Retrieval runs before the answer: the agent embeds the incoming question, filters the store to the right user, searches, ranks the candidates on recency, importance and relevance, and injects only the top few into the prompt. Every slot it spends is a slot the rest of the prompt does not get, which is why retrieval quality decides whether a memory system is worth having.
Before every answer
The read path
What happens during memory retrieval?
Five steps run between the user’s message and the model’s call: embed the query, filter by scope, search the store, rank what comes back, and inject the survivors into the prompt. All of it happens inside the latency budget of a single turn, which constrains every design decision that follows.
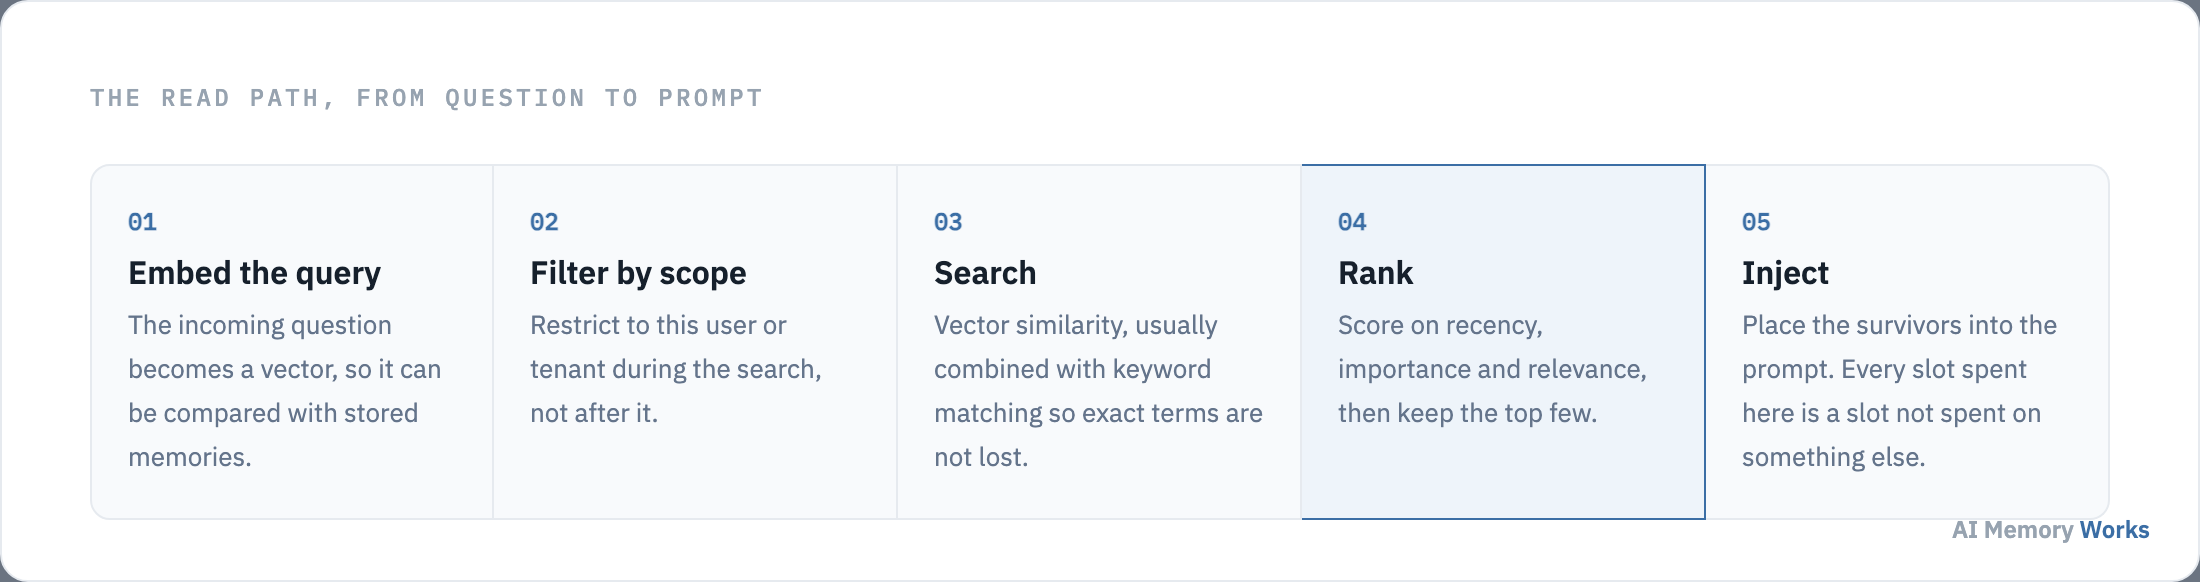
Embedding the query turns the question into a vector so it can be compared against stored memories. A detail that matters more than it looks: the query and the memories must be embedded by the same model, so changing embedding models means re-embedding the entire store.
Filtering by scope restricts the search to this user or tenant. This has to be a condition inside the search rather than a filter applied to the results, both because post-filtering can return nothing useful after discarding other users’ matches, and because it is the boundary that keeps one person’s memories out of another person’s prompt.
Searching is usually vector similarity, often combined with keyword matching so that exact identifiers, names and codes are not lost to semantic approximation. The combination is covered on hybrid search for memory retrieval.
Ranking and injection decide what actually reaches the model, and they are where most of the quality lives: how memories are ranked.
Ranking
How are memories ranked for retrieval?
By combining three signals: how recently the memory was accessed, how important it is, and how relevant it is to the current query. The canonical formulation comes from the Generative Agents paper (Park et al., 2023), which sums the three normalised scores with each weight set to 1.0, and decays recency exponentially at 0.995 per hour since the memory was last accessed.
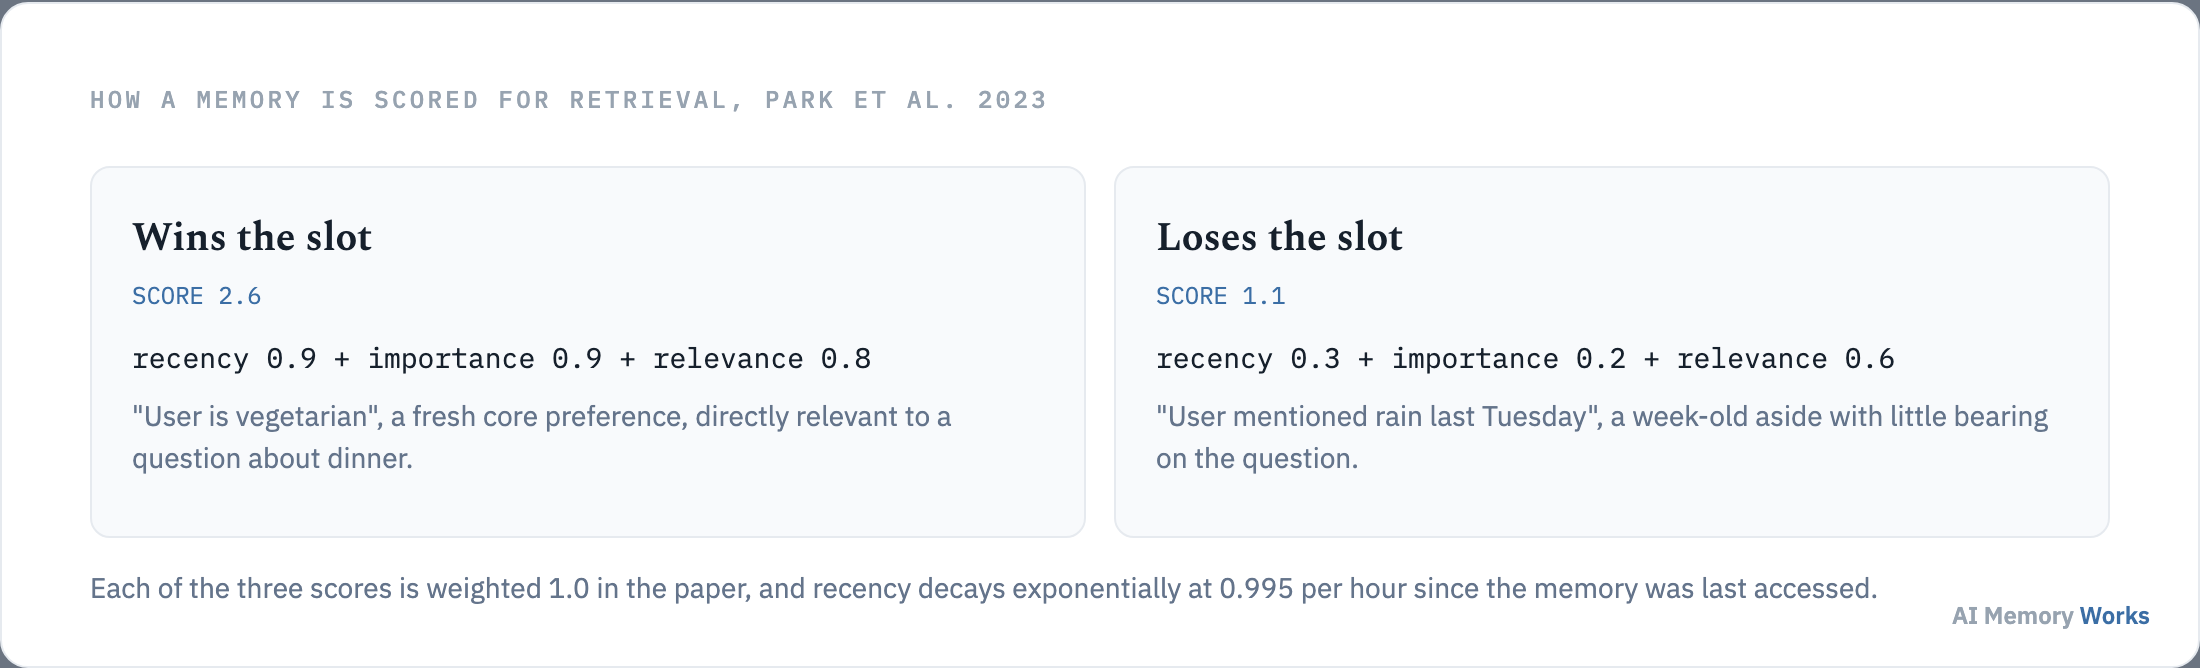
Relevance is the similarity between the query and the memory, and it is the signal every system has. On its own it is not enough, because the most similar memory is not always the most useful one: a question about dinner is semantically close to every restaurant the user ever mentioned.
Recency is a proxy for currency. Decaying it exponentially rather than linearly means the last few days dominate while older memories fade smoothly instead of falling off a cliff. Decay based on last access rather than creation is deliberate: a memory that keeps being useful stays fresh.
Importance is the hardest of the three because it has to be assigned rather than computed. Common approaches are asking a model to rate each memory on write, inferring it from user emphasis, or promoting anything corrected by a human. Getting this signal wrong is what makes an agent surface trivia while ignoring a stated preference.
The count of injected memories is a fourth decision that is easy to leave at a default. More is not better: each additional memory occupies prompt space and adds a chance of pulling the answer off course, which is the “lost in the middle” effect documented by Liu et al. (arXiv:2307.03172). The scoring detail is covered on scoring and ranking memories.
Retrieval is also the step that makes memory cheaper than the alternative: what selective retrieval costs.
Economics
What does memory retrieval cost?
A search per turn and a small number of injected tokens, against the alternative of resending an entire conversation on every call. The published comparison is stark and is the main argument for memory in production.
On the LOCOMO benchmark, Mem0 reports a median search latency of 0.148 seconds and a p95 total latency of 1.44 seconds, against 17.1 seconds for a 26,000-token full-context baseline, a reduction of about 91%. Token consumption falls from roughly 26,000 per query to roughly 1,800, over 90% fewer (Chhikara et al., 2025).
The accuracy side of the same comparison is worth stating honestly rather than omitting: the memory system scores 66.9 on the LOCOMO judge metric, or 68.4 with graph memory, against 72.9 for the full-context baseline. Retrieval trades a small amount of accuracy for a large amount of cost and latency, and it becomes the only option once the conversation exceeds the window entirely.
Two costs are easy to miss when budgeting. The embedding call on every query adds latency before the search even starts, which is why some systems skip retrieval on turns that clearly do not need history. And the search cost grows with the store, which is one more reason consolidation and eviction matter, covered on memory consolidation.
Cost also depends on a decision most systems make implicitly: when to retrieve at all.
The trigger
Should an agent retrieve memories on every turn?
Not necessarily. Retrieving always is simpler and costs a search per turn; retrieving conditionally is cheaper and risks missing the turn that needed history. The right answer depends on how often your traffic actually depends on something stored.
Always retrieving is the right default for assistants where nearly every message is personal: a companion, a personal assistant, a support agent handling a known customer. The search cost is a known constant, the behaviour is predictable, and there is no classifier to get wrong.
Conditional retrieval makes sense where a large share of turns are self-contained. A coding agent asked to explain a language feature does not need the user’s stored preferences; the same agent asked to follow project conventions does. A cheap classifier or a heuristic on the query decides, and the risk is that a misclassification produces an answer that ignores something the user already said, which is the exact failure memory was added to prevent.
A third pattern splits the difference and is common in practice: always retrieve a small, cheap set of high-importance memories such as core preferences, and run the full search only when the query looks historical. That keeps the always-relevant facts present at negligible cost while avoiding a full search on every trivial turn.
Whichever trigger you choose, measure it against turns that should have used memory rather than against average latency. A system that skips retrieval on 40% of turns looks efficient right up until the skipped turns are the ones users complain about.
Cost is predictable. Quality is not, and it fails in specific ways worth recognising: why memory retrieval fails.
Failure modes
Why does memory retrieval fail?
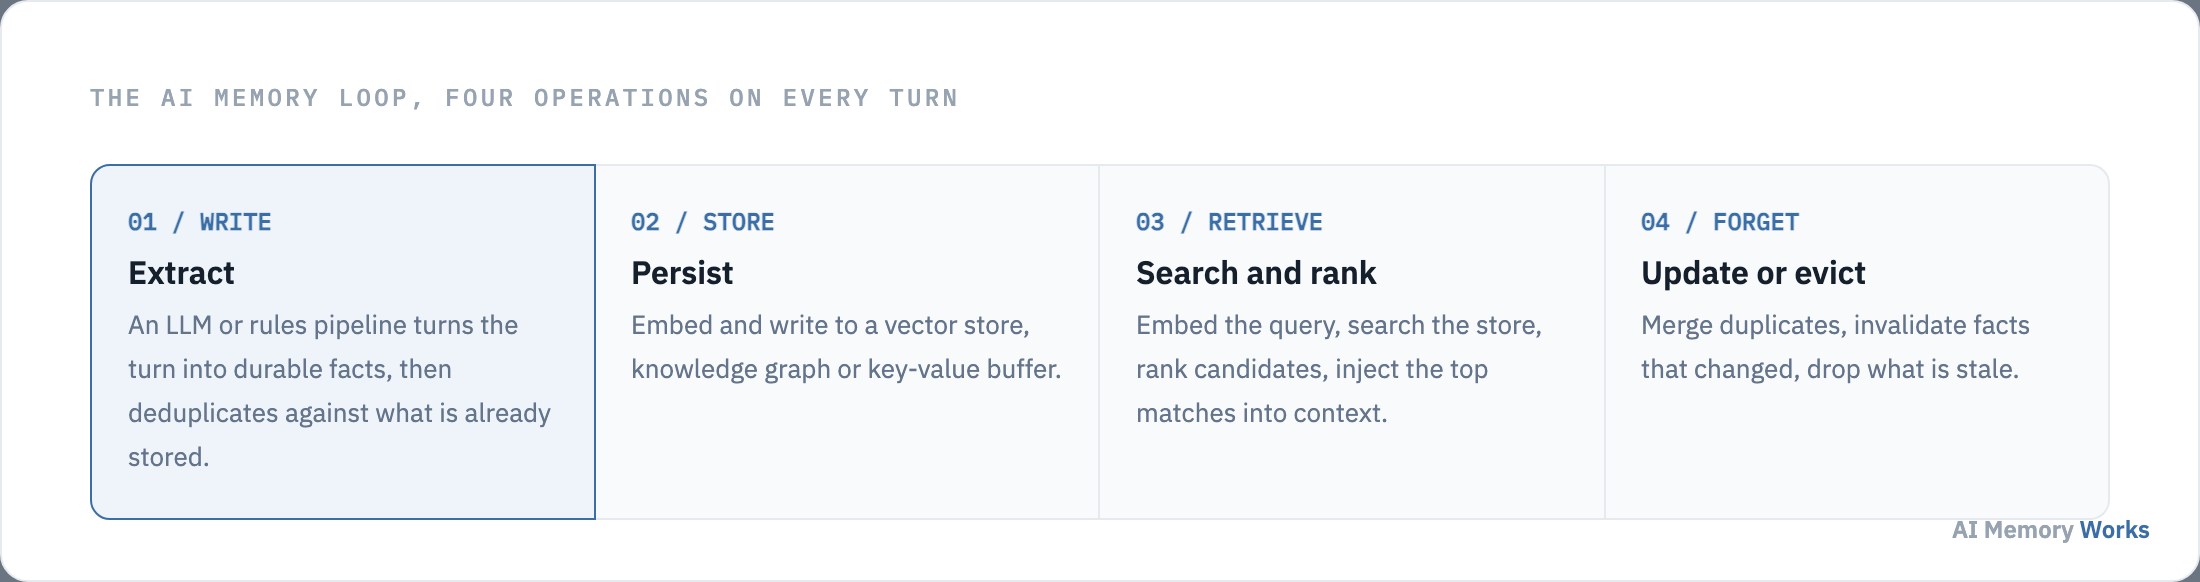
Four failures cover nearly all of it, and only one of them is a search problem. Teams usually tune the search first, which is why retrieval quality often does not improve.
- The memory was never written. Extraction decided the fact was not durable, so no amount of retrieval tuning will find it. This is the most common cause and it is diagnosed by inspecting the store, not the search.
- Phrasing mismatch. The stored memory and the query use different vocabulary for the same thing, so similarity search ranks it low. Hybrid search and storing memories in canonical form both reduce this.
- Drowned by duplicates. The right memory is present but four near-identical variants of another fact fill the slots ahead of it. This is a write-path problem showing up at read time, fixed by deduplication.
- Retrieved and ignored. The memory reached the prompt and the model did not use it, usually because it was buried among too many injected memories. Fewer, better-ranked memories often improve answers more than better search does.
The diagnostic order follows from that list. Check whether the fact is in the store at all, then whether it is in the retrieved set, then whether the answer used it. Each step separates a different class of problem, and skipping to search tuning conflates all three.
Building that check is worth the effort, because it is also the evaluation described in how to add memory to an AI agent: a set of questions whose answers depend on stored facts, run regularly, with retrieval hit rate measured separately from answer correctness.
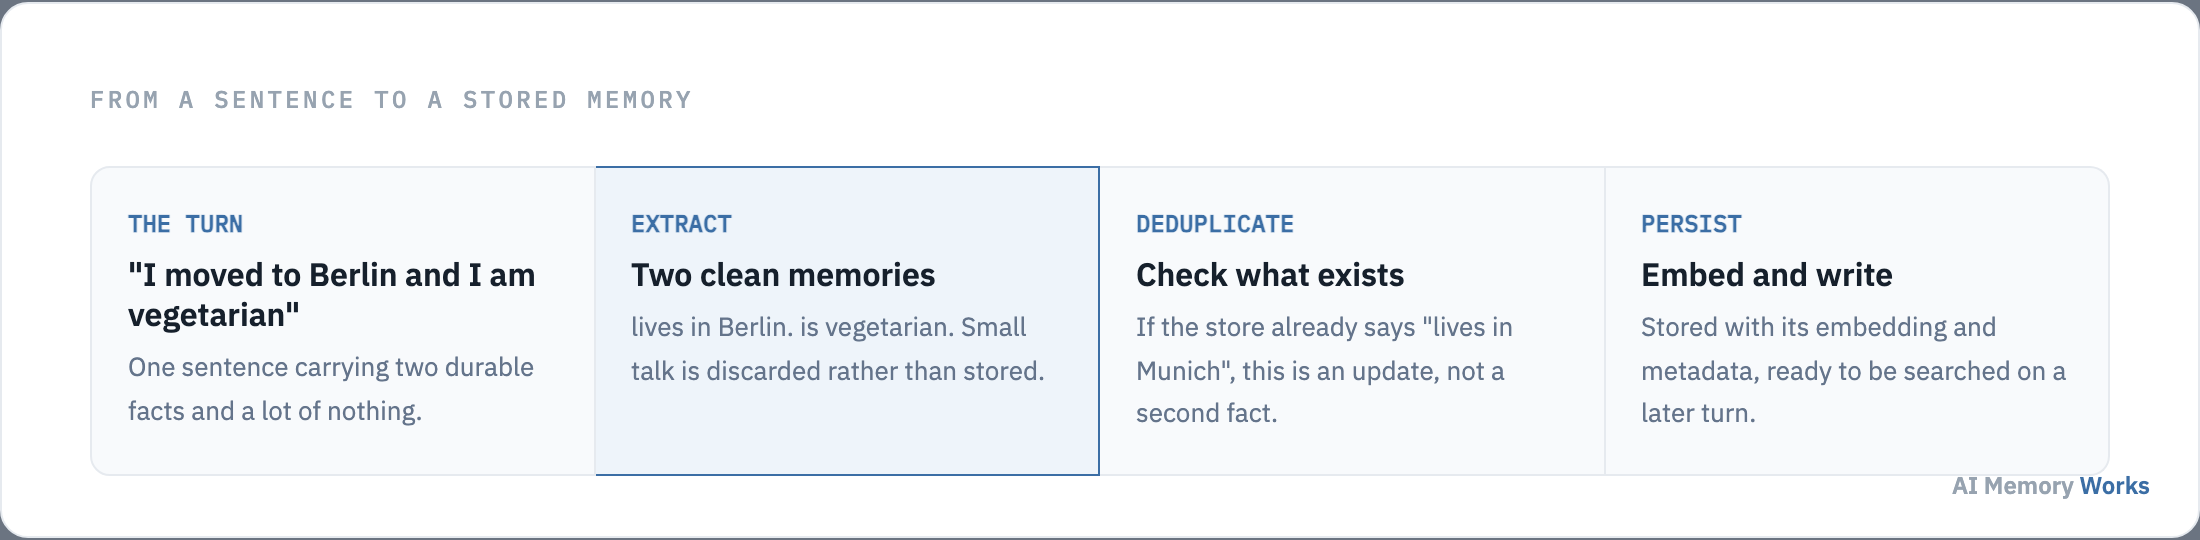
That diagnostic order also explains a common and expensive detour. A team sees poor answers, concludes retrieval is weak, and spends weeks on embedding models and re-ranking, when the fact was never extracted in the first place. Checking the store takes minutes and rules out the largest category first.
The write path that feeds all of this is covered on how agents write and store memories, and the full cycle on how AI memory works.
FAQ
Frequently asked questions
The questions that follow: how many memories to inject, and whether to retrieve on every turn.
How many memories should agents retrieve per turn?
Typically top-k = 5–10 memories, tuned on your eval set. Too few misses context; too many dilutes attention and raises token cost. See injection section above.
How do you tune top-k for memory retrieval?
Run LOCOMO or LongMemEval on your domain with k = 3, 5, 10, 20. Pick the smallest k that maintains recall. Mem0's published eval uses selective retrieval vs 26,000-token full context (Chhikara et al., 2025).
What is typical memory retrieval latency?
Mem0 reports median search latency 0.148 s and p95 total latency 1.44 s on LOCOMO vs 17.1 s full-context baseline (Chhikara et al., 2025). Latency depends on index size and embedding model.
What if the wrong memory is retrieved?
Improve scoring (recency + importance + relevance), add metadata filters (user_id, memory_type), use hybrid search for exact matches, or invalidate stale facts. See memory scoring.
When should you use hybrid search for memory?
When memories contain exact IDs, SKUs, order numbers or names that pure vectors miss. Combine BM25/keyword with embedding similarity. See hybrid search.
When is graph retrieval needed?
When facts involve relationships, temporal validity or conflict resolution — CRM timelines, policy versioning. Zep Graphiti is built for graph retrieval. See knowledge graphs.
How do you benchmark memory retrieval?
LOCOMO and LongMemEval measure conversation recall. Track hit rate, latency and tokens injected per query. See evaluation hub.
How does Engram retrieve memories?
Semantic search on Weaviate memory collections — same platform as RAG vectors, separate namespaces. See Engram explained.
Retrieval before or after writing memory?
Retrieve before generate (agent needs context). Write after generate (extract new facts). Standard sequence: retrieve → generate → write.
Memory retrieval vs RAG retrieval?
Same vector tech, different stores — memory is per-user dynamic facts; RAG is static org documents. Run both pipelines in production agents. See memory vs RAG.