Memory types · Cluster hub
What Are the Types of AI Agent Memory?
Agents use four core memory types, working, semantic, episodic and procedural, and this knowledge base covers six by adding sensory or buffer memory and shared memory across agents. The counts differ between sources because they are drawing the boundary in different places, and this page explains where each line is drawn before walking every type.
The four core types
The core set
What are the four main types of AI agent memory?
Working memory holds what is happening now, semantic memory holds what is true, episodic memory holds what happened, and procedural memory holds how to do things. The split is borrowed from human cognitive psychology and formalised for agents by the CoALA framework, which is why the same four names recur across almost every source.
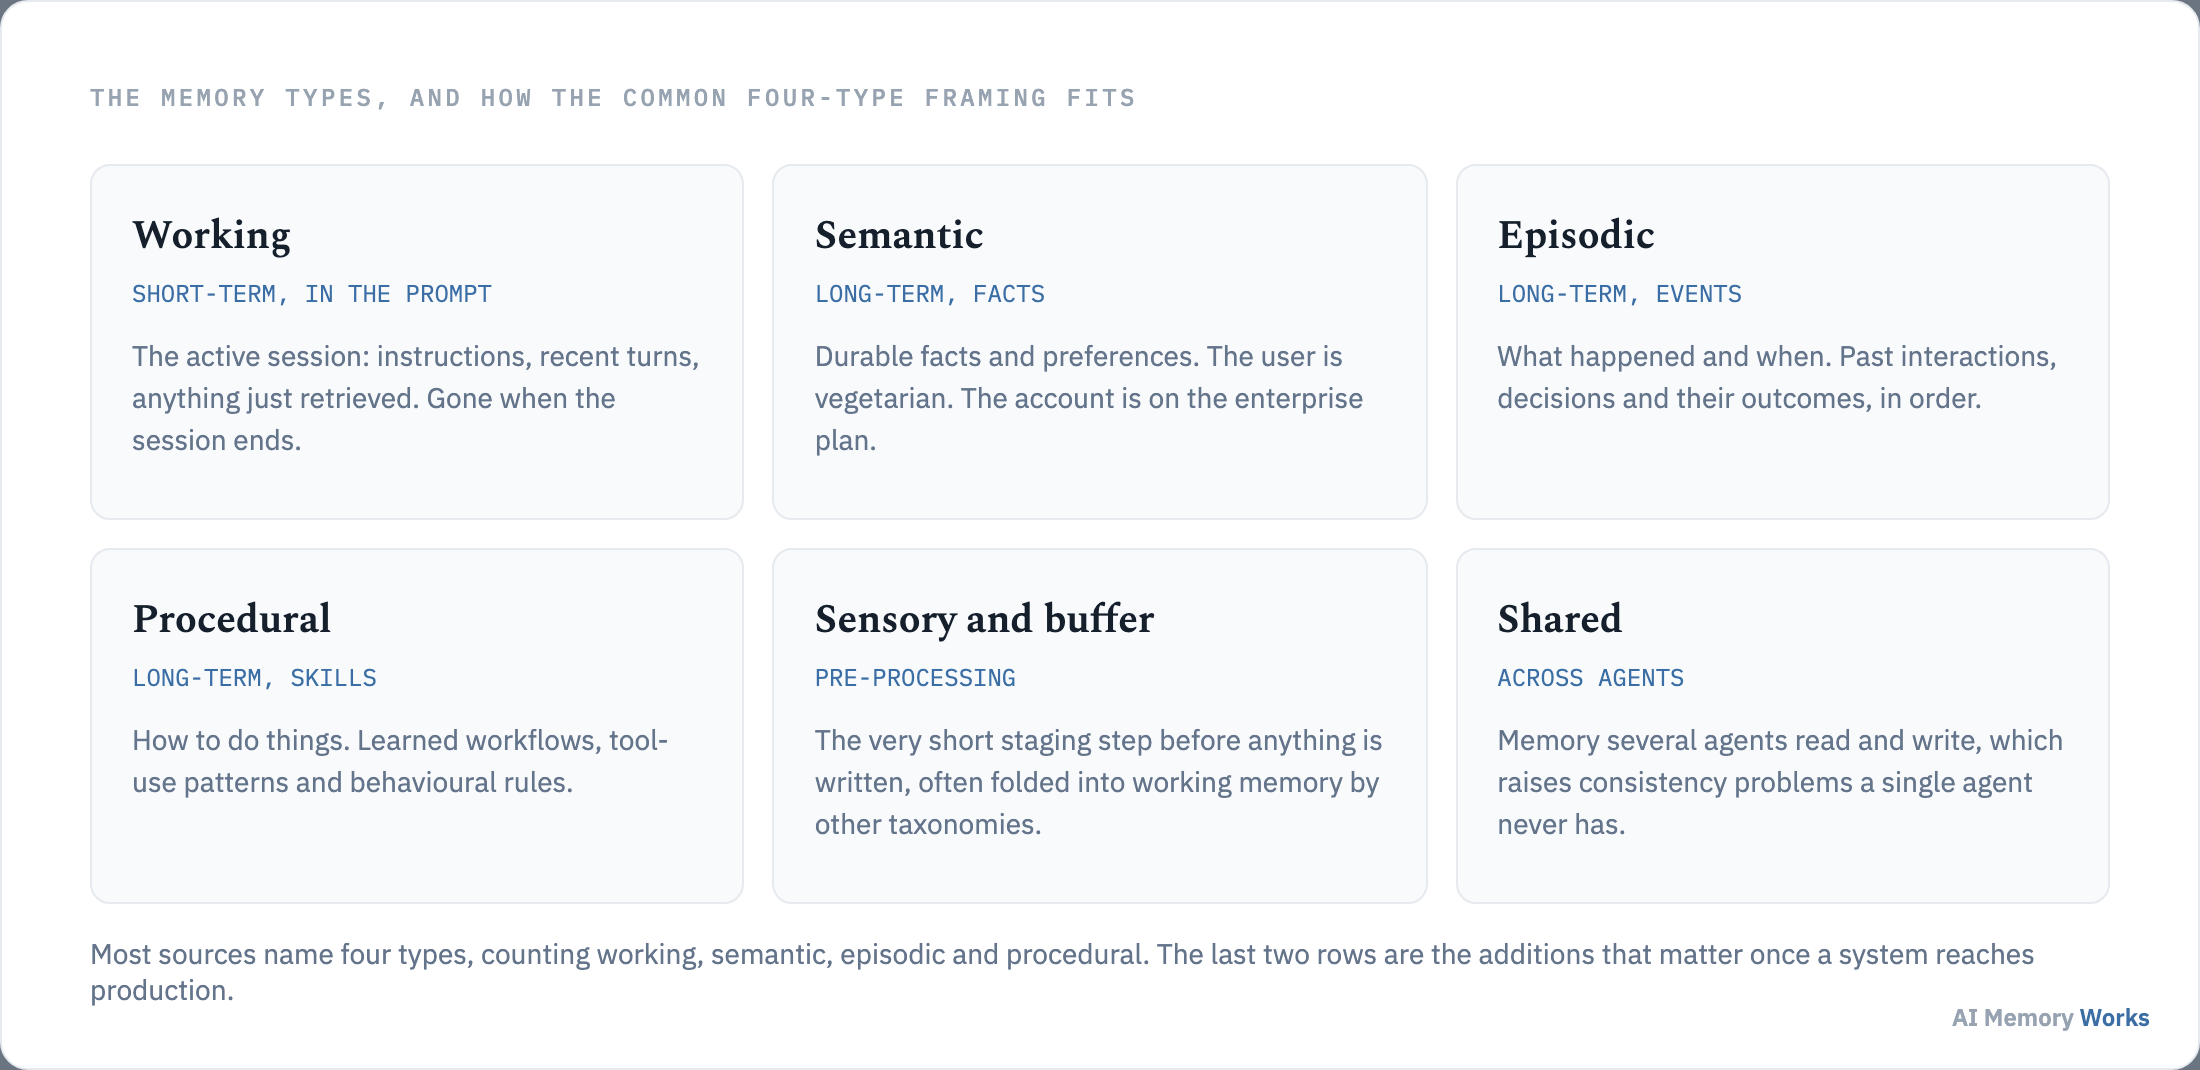
Working memory is the active space inside the current conversation, holding the latest messages, the system instructions and recent tool output. It is the context window itself, which makes it fast, strictly bounded, and gone at the end of the session. Everything else on this page exists to decide what gets loaded into it. See short-term memory in AI agents.
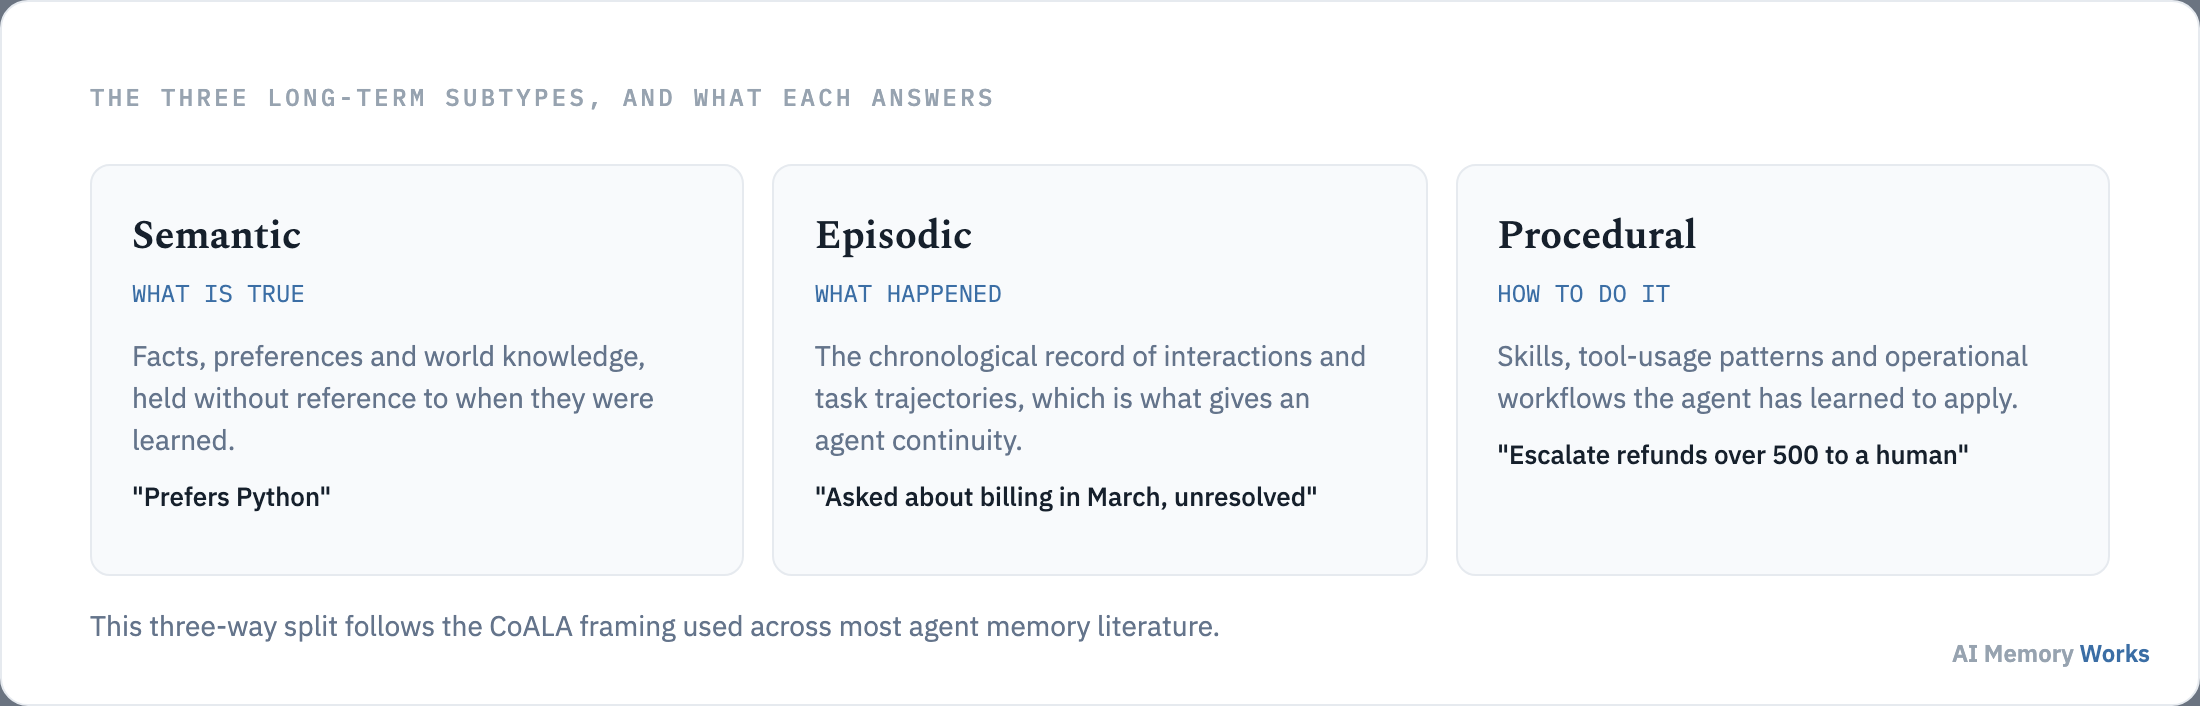
Semantic memory holds durable facts without reference to when they were learned: a user’s dietary preference, an account’s plan tier, a product’s specification. It is the memory type most systems implement first, because it delivers the recognisable behaviour of an assistant that knows who it is talking to. See semantic memory in AI agents.
Episodic memory holds the ordered record of what happened: past interactions, decisions taken, and how they turned out. It is what lets an agent say what it already tried, which is the difference between an assistant that learns within a relationship and one that starts fresh while claiming otherwise. See episodic memory in AI agents.
Procedural memory holds learned skills, tool-use patterns and behavioural rules, closer to a policy than to a fact. An agent that has learned to escalate certain requests, or to check one system before another, is using procedural memory. See procedural memory in AI agents.
Those four are the consensus. The reason you will also see three, five and six is worth understanding, because it changes what a source is counting: why the number of memory types differs between sources.
The disagreement
Why do sources give three, four or six memory types?
Because they are answering slightly different questions: some count only long-term memory, some count the standard cognitive four, and some add the categories that only appear once a system is in production. None of them is wrong, and knowing which count you are reading prevents a lot of confusion.
- Three types means semantic, episodic and procedural. This count is describing long-term memory only, and deliberately leaves out working memory because the context window is not a store. It is the framing used in most academic writing on agent memory.
- Four types adds working memory to those three, which is the practical engineering view: the prompt is where memory has to arrive, so it belongs in the taxonomy.
- Six types adds sensory or buffer memory, the very short staging step before anything is written, and shared memory, which several agents read and write at once. Both are folded into other categories by shorter taxonomies, and both cause real problems that the four-type view has no name for.
A related question confuses the counts further. Searches for the types of AI agents, meaning reflex agents, goal-based agents and so on, use nearly identical wording and return a different taxonomy entirely. That five-type or seven-type list is about how agents decide, not about what they remember.
The two additions this site makes are covered on sensory and buffer memory and shared memory in multi-agent systems.
The pair most often confused with each other is compared directly on episodic versus semantic memory.
Counting aside, the practical division that governs every implementation is simpler: the split between short-term and long-term memory.
The main division
What is the difference between short-term and long-term memory?
Short-term memory is the context window, which the model reads directly and which disappears at the end of the session. Long-term memory is an external store, which survives and is reached only by an explicit search. Every memory type sorts into one side or the other, and the boundary decides the engineering.
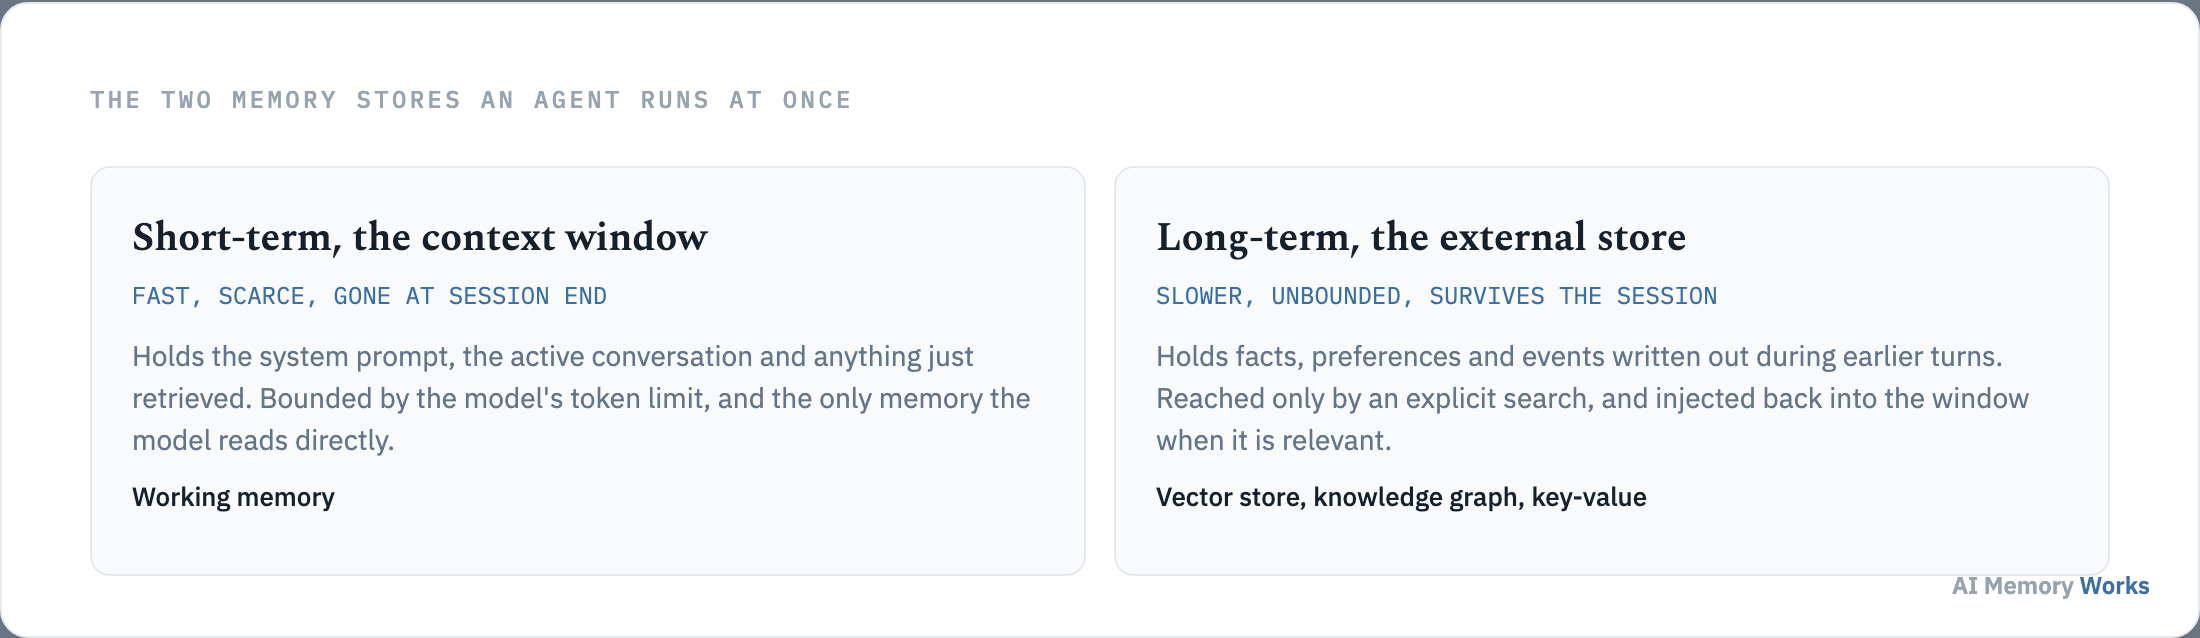
Working memory sits on the short-term side by itself. Semantic, episodic and procedural memory all sit on the long-term side, which is why they share a pipeline: extraction, storage, retrieval and consolidation. That shared pipeline is described on long-term memory for AI agents.
The relationship between the two is one-directional and worth stating precisely. Long-term memory does nothing on its own, because the model still only reads the prompt. Its entire job is to put the right things into short-term memory at the right moment, which makes every retrieval decision a decision about which scarce prompt slots to spend. The comparison in full is on short-term versus long-term memory.
There is one more division that cuts across all of this, and it explains why some knowledge cannot be stored as memory at all: parametric versus non-parametric memory.
A different axis
What is parametric versus non-parametric memory?
Parametric memory is what the model knows because of its weights. Non-parametric memory is everything held outside them, which is what this entire field means by memory. The distinction matters because it decides what can be changed and how quickly.
Parametric knowledge arrived during training and is expensive to alter, requiring fine-tuning rather than a write. It is also not inspectable: you cannot list what a model knows, or delete one fact from it on request. Non-parametric memory is the opposite on every count. It can be written in milliseconds, listed, corrected and deleted, which is exactly why products that let a user manage what an assistant remembers are managing non-parametric memory.
The practical consequence for a build is that anything that must be correctable, auditable or deletable has to live outside the weights. That includes almost everything about an individual user. The full comparison is on parametric versus non-parametric memory, and the related choice on memory versus fine-tuning.
With the taxonomy settled, the question a team actually has to answer is narrower: which memory types your agent needs.
Selection
Which memory types does your agent need?
Almost every agent needs working and semantic memory. Episodic memory is needed when continuity across sessions matters. Procedural memory is needed when the agent should improve at a task rather than only recall facts about it.
By product shape the answers are fairly consistent. A support agent needs semantic memory of the account and episodic memory of the case history. A personal assistant leans almost entirely on semantic memory about one person, with episodic memory close behind. A coding agent needs procedural memory most of all, since the valuable thing is the conventions of a codebase rather than isolated facts about it. A multi-agent system needs shared memory and inherits a consistency problem none of the others have.
Storing everything in one undifferentiated store is the common shortcut and it degrades predictably, because a semantic fact and an episodic event should be retained on different schedules and retrieved by different signals. Use cases are covered on customer support, personal assistants and coding agents.
Whichever types you need, they all move through the same four operations: how the types are written and retrieved.
Mechanism
How are memory types written and retrieved?
Through one loop that every type shares: write, store, retrieve, and forget or update. The type determines what is extracted and how it is ranked, not whether the loop applies.
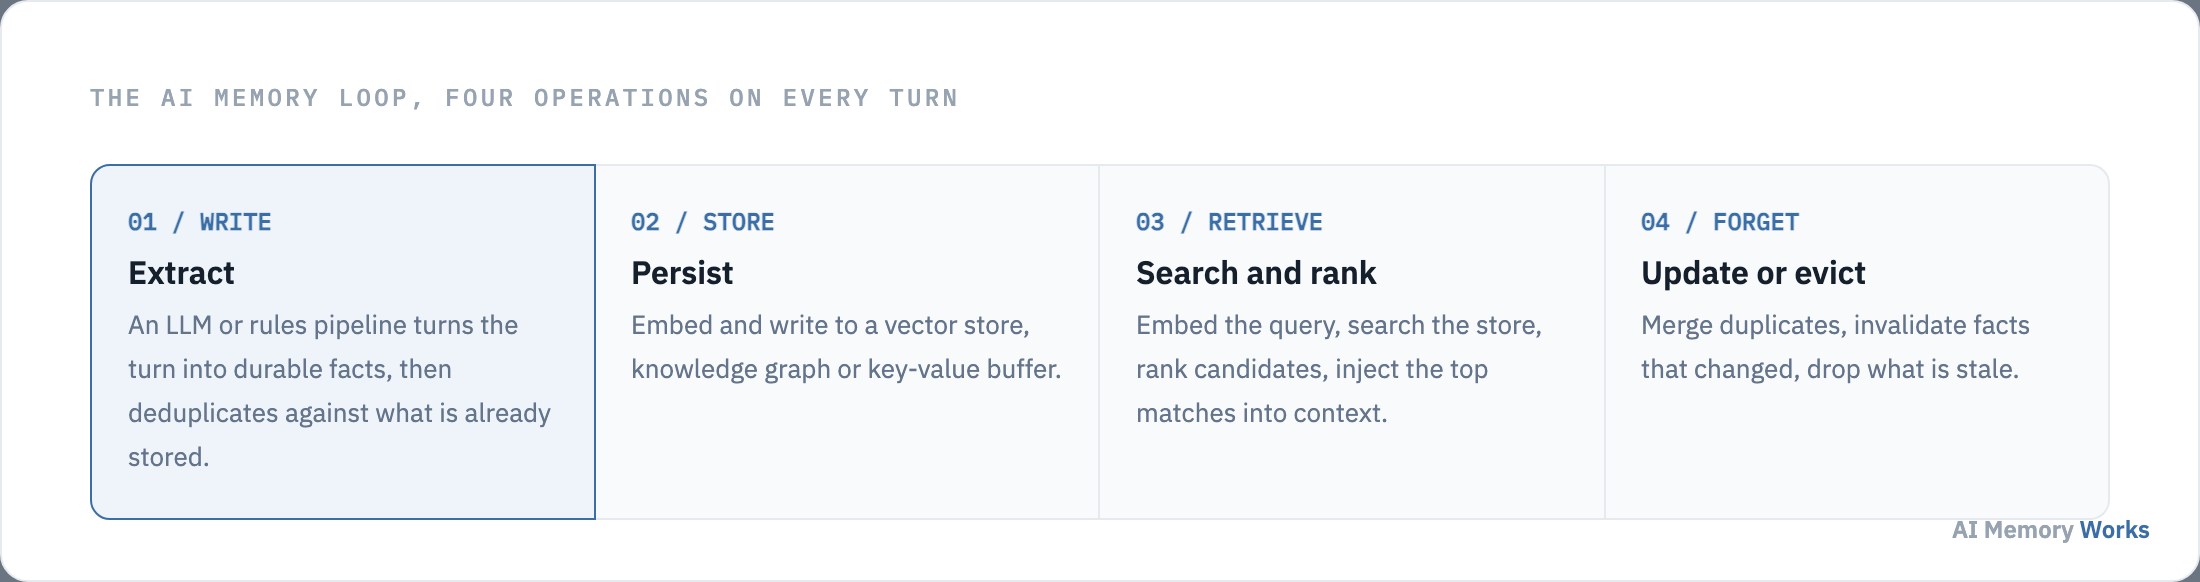
The differences show up in the details. Semantic memories are extracted as short standalone statements and kept until superseded. Episodic memories carry a timestamp and matter in sequence, so they age faster and are usually summarised rather than deleted. Procedural memories are updated rather than expired, because a workflow that has become wrong should be corrected, not forgotten.
The loop itself is walked in how AI memory works, the mechanisms in the architecture cluster, and the implementation in how to add memory to an AI agent.
FAQ
Frequently asked questions
The questions that follow the taxonomy: how the types map to human memory, and which to implement first.
How many types of AI agent memory are there?
The core taxonomy has six types: short-term/working, long-term, episodic, semantic, procedural and sensory/buffer — plus cross-cutting distinctions like parametric vs non-parametric and shared memory for multi-agent systems. See the types hub.
What is the difference between short-term and long-term memory in AI agents?
Short-term (working) memory lives in the context window and holds the current task. Long-term memory persists in an external store across sessions. Agents promote information between tiers via consolidation. See short-term vs long-term.
Episodic vs semantic memory — what's the difference?
Episodic memory stores specific past interactions ("user asked about a refund on Tuesday"). Semantic memory stores stable facts and preferences ("user prefers email"). Both persist long-term but serve different retrieval patterns.
What is working memory in AI agents?
Working memory is the agent's short-term store — typically the context window holding recent turns, tool outputs and the current task. It is lost when the session ends unless written to long-term memory. See short-term memory.
What is procedural memory in AI agents?
Procedural memory stores skills, tools and learned how-to procedures — not facts but capabilities. It bridges to memory as a tool patterns. See procedural memory.
Parametric vs non-parametric memory — which do agents use?
Most agent memory is non-parametric — stored externally and updatable at runtime. Parametric memory lives in model weights (fine-tuning). See parametric vs non-parametric.
Is LSTM the same as AI agent memory?
No. LSTM is a neural network architecture for sequence modeling — not the cognitive-science-inspired memory taxonomy used for AI agents. Agent memory refers to external storage systems (vector DBs, graphs, APIs), not recurrent network cells.
Do human memory types apply to AI agents?
The taxonomy is inspired by cognitive science but implemented differently in software. Human memory is biological; agent memory uses context windows, vector stores and knowledge graphs. See AI memory vs human memory.
Which memory type is best for personalization?
Semantic memory (stable user preferences and facts) plus episodic memory (past interactions) power personalization. Frameworks like Engram and Mem0 specialize in per-user semantic memory. See user memory personalization.
How do memory types map to Mem0, Zep and Letta?
Engram maps semantic/episodic memory on Weaviate-native stacks. Mem0 focuses on per-user semantic/episodic vector memory. Zep adds temporal knowledge-graph semantics. Letta uses virtual-context paging across tiers. See best AI memory tools for the full mapping.